Google Maps gains glanceable directions and an expanded Immersive View

Google Maps gains glanceable directions and an expanded Immersive View Kyle Wiggers 10 hours

Timed to arrive ahead of the summer travel season, Google’s bringing new features to Maps focused on discovery and navigation.

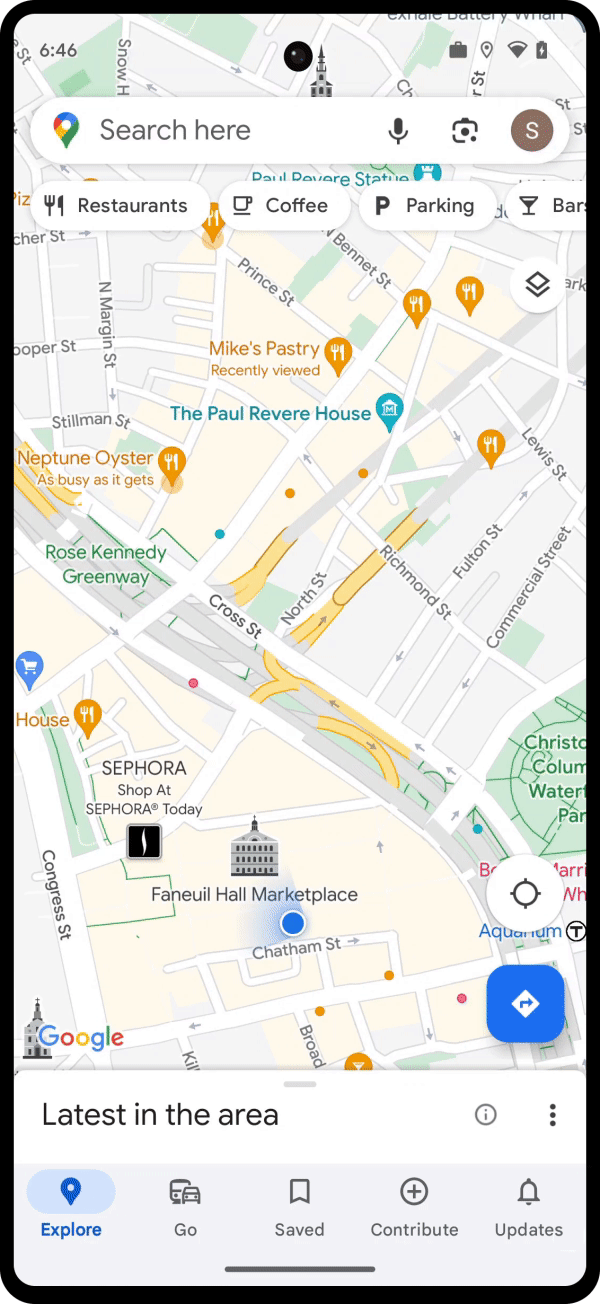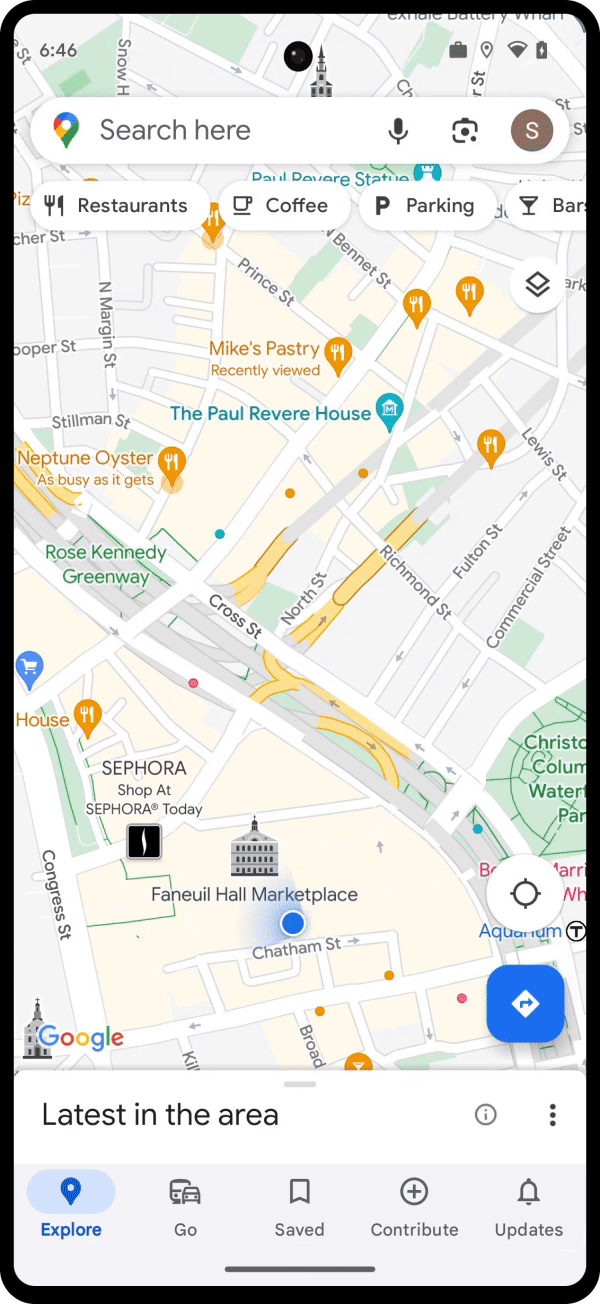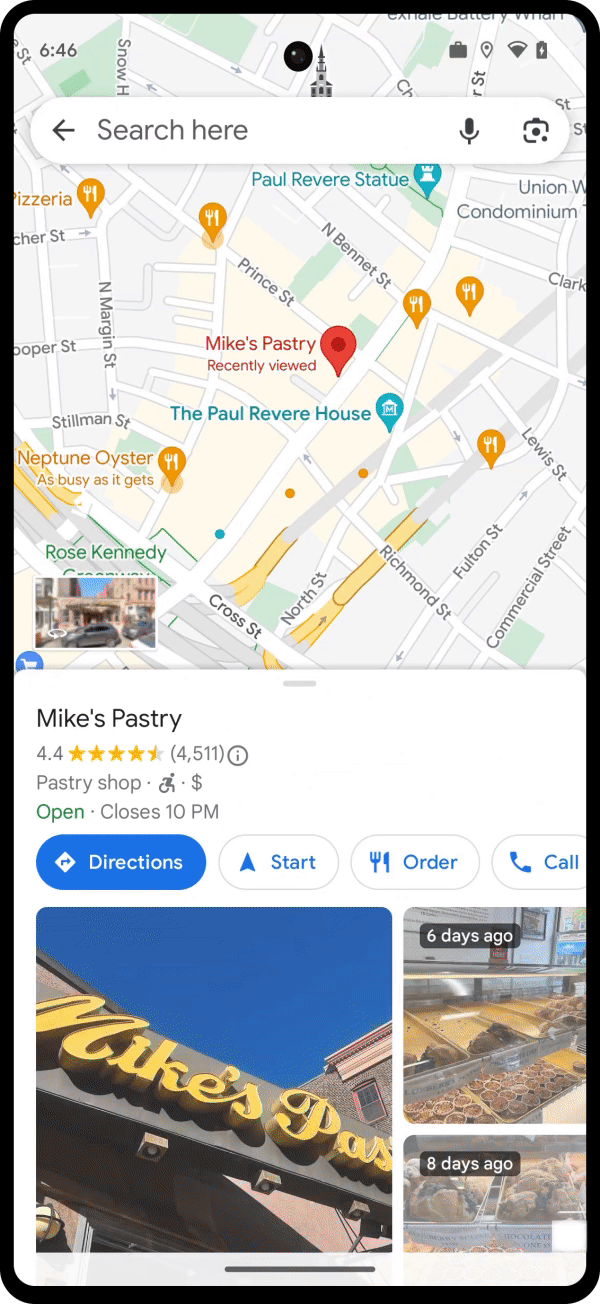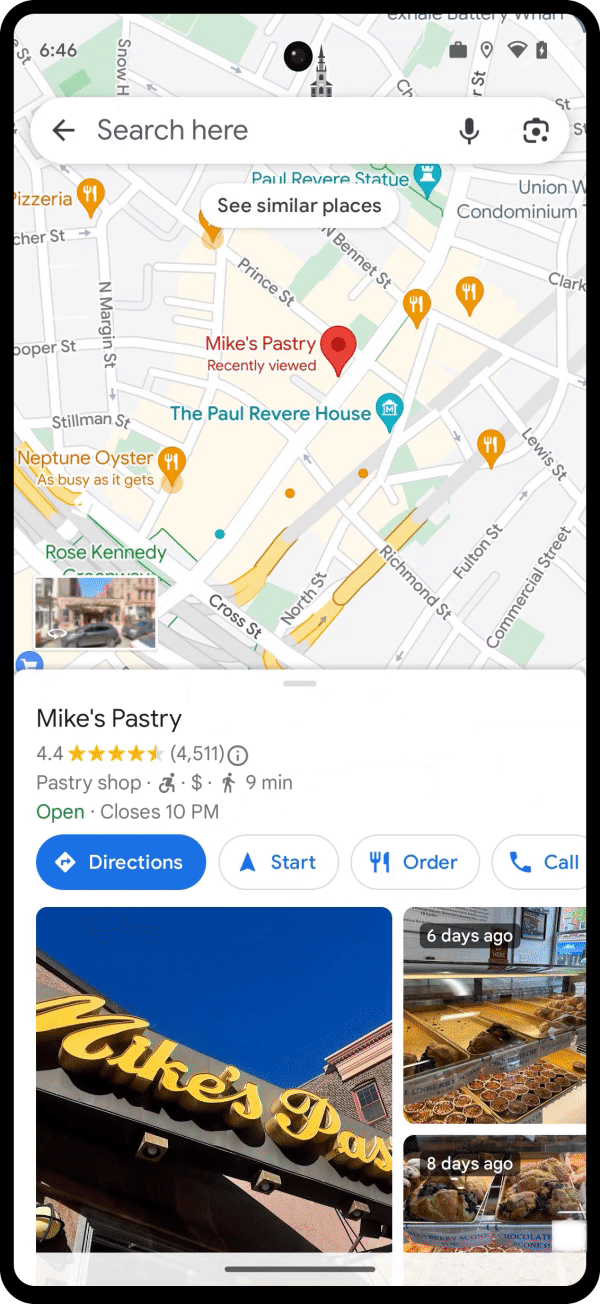
New “glanceable directions,” which Google announced in February, will start rolling out this month in the Maps app on Android and iOS. They’ll let users who opt-in track walking, cycling and driving trip progress from their lock screen or route overview, and see updated ETAs and notifications about where to make each turn.

Google Maps updates

Image Credits: Google

Arriving alongside glanceable directions is updates to Recents on desktop, a shortcut that automatically organizes places you researched in Maps into a highlight on the side of the Maps screen. Soon, Google will save places in Recent highlights even after you’ve closed the Google Maps window, and adds tools to remove places you’ve viewed, create custom routes between destinations and share a selection of places with someone else.

Lastly, Immersive View, Google’s AI-powered feature on the iOS and Android Maps app that fuses together images to create a multidimensional view of the world, is expanding to over 500 landmarks. Among the highlights are Prague Castle and Sydney Harbour Bridge.

Google Maps updates

Image Credits: Google

Christina Tong, senior product manager at Google Maps, shared more in a blog post this morning:

“With the time slider [in Immersive View], you can see what the weather will be like at different times of day and how crowded it will be so you can plan ahead. And where we have data available, you can peek inside of restaurants and cafes to help you decide whether you want to make a reservation.”

Google and YouTube Unveil AI-Powered Ad Solutions

Google and YouTube have introduced new ad solutions, Demand Gen and Video View, powered by AI to enhance advertisers’ creativity and generate increased interest.

Demand Gen and Video View leverage Google AI to facilitate consumer engagement and drive demand throughout the purchasing process.

Read more: This AI Startup From Paris Raises Highest Seed Funding Ever

Demand Gen

Demand Gen enables advertisers to generate responses across YouTube and Google. These campaigns cater specifically to the needs of social marketers, as research indicates that 91% of consumers take immediate action upon discovering new products or brands on Google feeds, such as Discover or Gmail. To reach a wide audience, Demand Gen integrates high-performing video and image assets into YouTube, YouTube Shorts, Discover, and Gmail.

To simplify the process, Demand Gen also introduces a user-friendly construction flow, allowing advertisers to seamlessly import their most successful image and video assets into Google Ads. This enables them to preview the appearance of their ads before they go live.

Furthermore, advertisers can enhance the effectiveness of these campaigns by pairing tailored creatives with newly introduced lookalike segments based on their audience lists. By optimising for conversions and utilising maximise clicks bidding, advertisers can create highly relevant campaigns aligned with their objectives, driving the desired actions at opportune moments. For instance, they can offer existing customers a discount on a new product line to encourage conversions or entice new audiences with special offers to join their brand’s subscription program.

Early alpha testers, including marketing agency Arcane, claim to have positive outcomes with Demand Gen, further highlighting its potential for success.

Video View

With Video View campaigns, brands can maximise views across in-stream, in-feed, and now YouTube Shorts, all within a single campaign. In early testing, Video View campaigns have achieved an average of 40% more views compared to in-stream skippable cost-per-view campaigns.

One of the early testers, Samsung Germany, which aimed to engage its target Gen Z audience during the peak holiday season with Video View campaigns, claimed to have found increased views and achieved a 94% incremental reach, all while reducing CPMs and generating best-in-class consideration lift.

Google Banks on Ads for Profits

Google is exploring ways to monetise its AI-powered search engine by generating revenue through AI-written responses to search queries. The search engine is considering incorporating affiliate marketing into its results, suggesting products and marketplace ratings.

However, the AI-generated content is of lower quality and lacks expertise. Google’s new Search Generative Experience (SGE) aims to transform the search engine into a publication that provides its own mini-articles, but experts argue that the AI-generated advice is often outdated and unreliable.

Despite this, Google sees the new approach as an opportunity for commercial success and a better user experience. There are concerns that Google may eventually allow websites to pay for their content to be generated as answers in search results, potentially compromising the reliability of the information presented.

Read more: Synthesia Becomes a Unicorn with NVIDIA Backed Fundraise

The post Google and YouTube Unveil AI-Powered Ad Solutions appeared first on Analytics India Magazine.

KDnuggets News, June 14: GPT4All Your Free Local ChatGPT! • Falcon LLM: The Open-Source King

Features

  • GPT4All is the Local ChatGPT for your Documents and it is Free! by Fabio Matricardi
  • Falcon LLM: The New King of Open-Source LLMs by Nisha Arya
  • Getting Started with ReactPy by Abid Ali Awan

From Our Partners

  • Create a Time Series Ratio Analysis Dashboard by Boxplot Outlier Data Analysis
  • It's alive! Build your first robots with Python and some cheap, basic components by Manning

This Week's Posts

  • Mastering the Art of Data Storytelling: A Guide for Data Scientists by Nisha Arya
  • How to Optimize SQL Queries for Faster Data Retrieval by Nate Rosidi
  • The Art of Prompt Engineering: Decoding ChatGPT by Josep Ferrer
  • Geocoding for Data Scientists by Evan Miller
  • How to MLOps like a Boss: A Guide to Machine Learning without Tears by Natesh Babu Arunachalam
  • AI: Large Language & Visual Models by Ihar Rubanau
  • Big Data Analytics: Why Is It So Crucial For Business Intelligence? by Nahla Davies
  • OpenAI’s Approach to AI Safety by Nisha Arya
  • The Effects of ChatGPT in Schools and Why It’s Getting Banned by April Miller
  • 21 Must-Have Cheat Sheets for Data Science Interviews: Unlocking Your Path to Success by Nathan Rosidi

From Around The Web

  • ChatGPT as Your Expert Helper by Abid Ali Awan
  • Getting Started with Weka by Data Science Horizons
  • Using ChatGPT for Translation Effectively by Abid Ali Awan
  • Deep Reinforcement Learning improved sorting algorithms by Jonathan Bogerd
  • Strategies for Effective Brainstorming with ChatGPT by Abid Ali Awan

More On This Topic

  • Falcon LLM: The New King of Open-Source LLMs
  • GPT4All is the Local ChatGPT for your Documents and it is Free!
  • OpenChatKit: Open-Source ChatGPT Alternative
  • 8 Open-Source Alternative to ChatGPT and Bard
  • ChatGLM-6B: A Lightweight, Open-Source ChatGPT Alternative
  • Dolly 2.0: ChatGPT Open Source Alternative for Commercial Use

How AI is revolutionizing change data capture

This technology-inspired data abstract background is perfect for

Change Data Capture (CDC) is a crucial process in modern data management, enabling organizations to capture and replicate changes made to their databases in real time. With the rapid advancements in technology, artificial intelligence (AI) has emerged as a game-changer in the field of CDC. In this article, we will explore how AI is revolutionizing change data capture and transforming the way organizations handle their data.

CDC introduction

Change Data Capture (CDC) refers to the process of identifying and capturing data changes that occur in databases. It allows organizations to keep their data synchronized across various systems and applications, enabling real-time decision-making and analysis. On the other hand, AI involves the development of intelligent systems that can perform tasks that would typically require human intelligence.

Traditional change data capture methods

Traditionally, change data capture relied on techniques such as database triggers, log reading, and polling mechanisms. While these methods served the purpose, they had limitations and challenges. For instance, database triggers added significant overhead to the database system, affecting its performance. Log reading and polling mechanisms often resulted in delays and required extensive manual configuration.

AI-powered change data capture

The integration of AI in changing data capture processes has opened up new possibilities. AI-powered CDC leverages machine learning algorithms and natural language processing (NLP) techniques to automate the capture, transformation, and analysis of data changes. This approach brings numerous benefits and advantages over traditional methods.

Machine learning algorithms in CDC

Machine learning algorithms play a crucial role in AI-powered CDC. These algorithms can analyze historical data patterns, identify trends, and predict future changes. By training on large datasets, they become capable of capturing and processing data changes in real time, thereby enhancing the efficiency and accuracy of CDC processes.

Natural language processing in CDC

Natural Language Processing (NLP) has gained significant attention in the field of data management. When applied to change data capture, NLP enables systems to understand and interpret unstructured data, such as text-based change logs or data descriptions. This capability simplifies the transformation of data changes and enhances the overall accuracy of the CDC process.

Real-time data integration

One of the key advantages of AI-powered CDC is its ability to facilitate real-time data integration. Traditional methods often struggled with the near real-time replication of data changes. AI, on the other hand, enables organizations to capture, transform, and integrate data changes in real time, allowing for faster decision-making and improved operational efficiency.

Improved data quality and accuracy

AI-driven CDC brings improvements in data quality and accuracy. By automating the capture and transformation of data changes, AI reduces the risk of human errors and inconsistencies that are often encountered in manual processes. This ensures that the replicated data remains accurate and consistent across different systems.

Enhanced data transformation and analysis

AI-powered CDC also enables enhanced data transformation and analysis. With the help of machine learning algorithms, organizations can extract valuable insights from the captured data changes. These insights can be utilized for various purposes, such as identifying patterns, predicting future trends, and optimizing business processes.

AI for anomaly detection and predictive analytics

AI has the potential to revolutionize anomaly detection in CDC. By continuously analyzing data changes, machine learning algorithms can identify unusual patterns or behaviors in real time. This enables organizations to detect and respond to anomalies promptly, preventing potential issues or threats. Moreover, AI-driven predictive analytics can help organizations anticipate future data changes and take proactive measures.

Overcoming security and privacy concerns

When implementing AI-powered CDC, organizations must address security and privacy concerns. AI systems deal with large volumes of sensitive data, and ensuring its protection is crucial. Robust security measures, such as encryption and access controls, should be implemented to safeguard data during the capture, transformation, and integration processes.

Future trends and potential challenges

The future of AI in changing data capture looks promising. Emerging trends include the integration of AI with blockchain technology for enhanced data security, the adoption of edge computing for real-time processing, and the utilization of AI-powered data governance frameworks. However, organizations must also be prepared to face challenges such as the ethical use of AI and potential biases in algorithms.

Conclusion

Artificial intelligence is revolutionizing change data capture by automating and optimizing the process. Through machine learning algorithms and natural language processing, organizations can capture, transform, and integrate data changes in real time. This leads to improved data quality, enhanced analysis capabilities, and the ability to detect anomalies and predict future trends. As the technology continues to evolve, it is essential for organizations to embrace AI-powered CDC and stay ahead in the era of data-driven decision-making.

Google Lens can now search for skin conditions

Google Lens can now search for skin conditions Kyle Wiggers 7 hours

Google’s enhancing Google Lens, its computer vision-powered app that brings up information related to the objects it identifies, with new features.

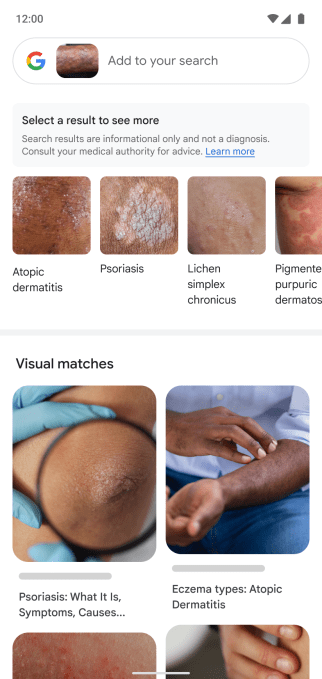
Starting today, Lens can surface skin conditions similar to what you might see on your own skin, like moles and rashes. Uploading a picture or photo through Lens will kick off a search for visual matches, which will also work for other physical maladies that you might not be sure how to describe with words (like a bump on the lip, a line on nails or hair loss).

It’s a step short of the AI-driven app Google launched in 2021 to diagnose skin, hair and nail conditions. That app, which debuted first in the E.U., faced barriers to entry in the U.S., where it would have had to have been approved by the Food and Drug Administration. (Google declined to seek approval.)

Google Bard skin search

Image Credits: Google

Still, the Lens feature might be useful for folks deciding whether to seek medical attention or over-the-counter treatments.

Elsewhere, as previously announced at I/O, Lens is integrating with Bard, Google’s AI-powered chatbot experience. Users will be able to include images in their Bard prompts and Lens will work behind the scenes to help Bard make sense of what’s being shown. For example, shown a photo of shoes and asked what they’re called, Bard — informed by Lens’ analysis — will come back with an answer.

It’s the latest update to Bard, Google’s answer to ChatGPT, as Google invests an increasing amount of resources into generative AI technologies. Just last week, Google introduced a capability that allows Bard to write, execute and test its own code in the background — improving its ability to program and solve complex math problems. And in May, Google partnered with Adobe to bring art generation to Bard.

Lenovo to Invest $1 billion for Accelerating AI Solutions

Lenovo to Invest $1 billion for Accelerating AI Solutions

Lenovo has announced a groundbreaking investment of $1 billion over the next three years to expand its infrastructure solutions and accelerate the deployment of AI for businesses worldwide. With record-breaking revenue exceeding $2 billion, increasing digitalization, and a rising demand for IT infrastructure upgrades, Lenovo aims to simplify the implementation of new AI capabilities by delivering AI directly to the source of data.

As part of its investment strategy, Lenovo will allocate an additional $100 million to expand the Lenovo AI Innovators program. This program has already yielded impressive results, generating over 150 cutting-edge AI-ready solutions in collaboration with 45 leading independent software vendor (ISV) partners within Lenovo’s comprehensive ecosystem.

These solutions, developed in just one year since the program’s launch, enable rapid deployment of advanced AI capabilities such as generative AI, computer vision, prediction, and virtual assistants.

Sumir Bhatia, President of Lenovo ISG in the Asia-Pacific region, expressed the company’s unwavering commitment to the future of AI. He emphasized that Lenovo’s significant investment not only demonstrates their dedication to being the most trusted partner in customers’ intelligent transformation journeys but also fuels innovation in AI technology.

The Lenovo AI Innovators program serves as a catalyst for AI discovery and adoption, bringing together an ecosystem of top-tier software partners to deliver tailored, proven, and ready-to-deploy AI solutions across industries. These solutions encompass computer vision, audio recognition, prediction, security, and virtual assistants, ensuring that businesses can leverage AI’s power throughout their operations.

Recently, Accenture has also announced that it is going to invest $3 billion in AI and also double its talent to 80,000 by hiring more people in the field.

Introducing new products

Lenovo’s comprehensive AI-ready infrastructure portfolio now includes over 70 products.

The new ThinkEdge SE360 V2, a purpose-built edge server, offers enhanced computing capabilities for AI applications such as computer vision, voice AI, and generative AI. It supports Intel Data Center GPU Flex Series, the NVIDIA AI platform, including NVIDIA L4 Tensor Core GPU, NVIDIA AI Enterprise software platform, and Qualcomm Cloud AI 100 platforms, enabling intensive workloads at the data source. With its compact size and high GPU density, the ThinkEdge SE360 V2 is ideal for remote and rugged environments.

Lenovo has also launched the ThinkEdge SE350 V2, designed for hybrid cloud and modern HCI deployments. This solution provides double the storage capacity and utilizes the Intel Xeon D processor, enabling efficient AI processing while consolidating workloads, data backup, collaboration, and content delivery.

In the data center, Lenovo introduces the ThinkSystem SR675 V3, a versatile and accelerated computing platform tailored for AI. It offers multiple server configurations, including support for NVIDIA HGX 4-GPU systems or 4-DW PCle GPU/8-DW PCle GPU servers in a compact 3U footprint.

The ThinkSystem SR675 V3 leverages digital twins, combined with AI, to improve business processes and design outcomes. Lenovo’s collaboration with NVIDIA on the NVIDIA OVX system enhances performance for NVIDIA Omniverse Enterprise workloads, enabling advanced ray tracing and graphics capabilities.

The post Lenovo to Invest $1 billion for Accelerating AI Solutions appeared first on Analytics India Magazine.

Zilliz Offers LLM-focused Features, New Pricing Model

Zilliz Offers LLM-focused Features, New Pricing Model June 14, 2023 by Jaime Hampton

Zilliz is looking to become the preferred vector database choice for LLM-powered applications through strategic enhancements and a cost-effective new pricing model that now includes a free tier. The company just announced the latest version of Zilliz Cloud, its fully managed vector database service, with new features and enhancements geared toward AI development.

Zilliz Cloud includes features of Milvus, an open source vector database built for processing vector data at scale that was invented by Zilliz founder and CEO Charles Xie. Although many relational and NoSQL databases have been modified with vector functionality, Zilliz is a native vector database specifically designed for storing and managing vector embeddings.

Vector databases have several use cases but are especially in demand at the moment due to the proliferation of large language models and the subsequent AI development gold rush. Native vector databases often boast faster query times, lower memory usage, and better scalability than traditional databases when it comes to LLM training and deployment.

Depending on their size, training LLMs results in thousands or even billions of vectors and vector embeddings, and a vector database performs a similarity search that finds the best match between the user’s prompt and a specific vector embedding. Zilliz claims to give developers a billion-vector-per-second performance, something the company believes gives it an edge over competitors like Pinecone and Elastic in becoming the preferred database for LLM-powered applications.

A new benchmark tool allows customers to compare Zilliz and Milvus to other popular vector database options. (Source: Zilliz)

The latest version of Zilliz Cloud includes several new tools and features aimed at this goal. There is now API support for popular programming languages and frameworks such as Python, JS, and RESTful APIs. Zilliz Cloud also newly supports JSON data types and users can store and manage JSON data alongside the existing Approximate Nearest Neighbor (ANN) Search capabilities, the company said in a blog post.

The company is also offering dynamic schema support with customizable Zilliz Cloud schemas for users working with data with specific fields or attributes. This new feature allows users to insert entities with dynamically varied fields into a collection rather than being limited to a predefined static schema, the company asserts. Users can also manage access and permissions for their teams with a new Organizations and Roles feature, which may appeal to larger organizations with multiple projects and teams.

Zilliz is working to minimize the problem of LLMs’ tendency to fabricate plausible-sounding information, also known as hallucination. The company says this problem can be reduced by using an external Zilliz Cloud database of accurate, domain-specific data that can help the LLM deliver dependable answers for business use.

Another aspect of the company’s quest to be the top choice for LLM applications is a new pricing plan that gives developers options to balance cost, performance, service quality, and compliance. A new free tier called the starter plan is available on GCP and is appropriate for those looking to experiment or prototype. A standard plan is available on GCP and AWS for teams with less than five engineers and less complex workloads. The enterprise plan is for customers with large-scale organizations requiring advanced security and support. Lastly, there is a self-hosted plan where users can deploy Zilliz on a virtual private cloud with complete control of privacy, security, and regulatory compliance.

Finally, a new open source benchmark tool allows users to compare Milvus or Zilliz with other database solutions. The company says this tool has comprehensive metrics and evaluation capabilities to allow customers to find the solution best aligned with their requirements.

“Generative AI is going to change everything – but first we have to trust it,” said Xie in a statement. “Developers of all sizes will need Zilliz Cloud to power their generative AI applications. And with our new pricing, they all can. With this latest release, we’re out to promote innovation and creativity and help developers create amazing applications that transform their businesses – and the lives of their users – for the better.”

This article first appeared on sister site Datanami.

Related

There and Back Again…a RAPIDS Tale

By Kris Manohar & Kevin Baboolal
There and Back Again…a RAPIDS Tale
Image by Editor

Editor's Note:We are thrilled to announce that this post has been selected as the winner of KDnuggets & NVIDIA's Blog Writing Contest.

Introduction

Machine learning has revolutionized various domains by leveraging vast amounts of data. However, there are situations where acquiring sufficient data becomes a challenge due to cost or scarcity. In such cases, traditional approaches often struggle to provide accurate predictions. This blog post explores the limitations posed by small datasets and unveils an innovative solution proposed by TTLAB that harnesses the power of the nearest neighbor approach and a specialized kernel. We will delve into the details of their algorithm, its benefits, and how GPU optimization accelerates its execution.

The Challenge of Limited Data

In machine learning, having a substantial amount of data is crucial for training accurate models. However, when faced with a small dataset comprising only a few hundred rows, the shortcomings become evident. One common issue is the zero frequency problem encountered in some classification algorithms such as the Naive Bayes Classifier. This occurs when the algorithm encounters an unseen category value during testing, leading to a zero probability estimation for that case. Similarly, regression tasks face challenges when the test set contains values that were absent in the training set. You may even find your choice of algorithm is improved (though sub-optimal) when these missing features are excluded. These issues also manifest in larger datasets with highly imbalanced classes.

Overcoming Data Scarcity

Although train-test splits often mitigate these issues, there remains a hidden problem when dealing with smaller datasets. Forcing an algorithm to generalize based on fewer samples can lead to suboptimal predictions. Even if the algorithm runs, its predictions may lack robustness and accuracy. The simple solution of acquiring more data is not always feasible due to cost or availability constraints. In such situations, an innovative approach proposed by TTLAB proves to be robust and accurate.

The TTLAB Algorithm

TTLAB's algorithm tackles the challenges posed by biased and limited datasets. Their approach involves taking the weighted average of all rows in the training dataset to predict the value for a target variable in a test sample. The key lies in adjusting the weights of each training row for every test row, based on a parameterized non-linear function that calculates the distance between two points in the feature space. Although the weighting function used has a single parameter (the rate of decay of influence of a training sample as its distance from the test sample increases), the computing effort to optimize over this parameter could be large. By considering the entire training dataset, the algorithm delivers robust predictions. This approach has shown remarkable success in enhancing the performance of popular models such as random forests and naive Bayes. As the algorithm gains popularity, efforts are underway to further enhance its efficiency. The current implementation involves tuning the hyperparameter kappa, which requires a grid search. To expedite this process, a successive quadratic approximation is being explored, promising faster parameter optimization. Additionally, ongoing peer reviews aim to validate and refine the algorithm for broader adoption.

To implement the TTLAB algorithm for classification for loops and numpy proved inefficient resulting in very long runtimes. The CPU implementation showcased in the linked publication focuses on classification problems, demonstrating the versatility and efficacy of the approach. https://arxiv.org/pdf/2205.14779.pdf. The publication also shows that the algorithm benefits greatly from vectorization, hinting at further speed improvements that can be gained from GPU acceleration with CuPy. In fact, to perform hyper-parameter tuning and random K-folds for result validation would have taken weeks for the multitude of datasets being tested. By leveraging the power of GPUs, the computations were distributed effectively, resulting in improved performance.

Accelerating Execution with GPUs

Even with optimizations like vectorization and .apply refactoring, the execution time remains impractical for real-world applications. However, with GPU optimization, the runtime is drastically reduced, bringing execution times down from hours to minutes. This remarkable acceleration opens up possibilities for using the algorithm in scenarios where prompt results are essential.

Following the lessons learnt from the CPU implementation, we attempted to further optimize our implementation. For this, we moved up the layer to CuDF Dataframes. Vectorizing calculations onto the GPU is a breeze with CuDF. For us, it was as simple as changing import pandas to import CuDF (you must vectorize properly in pandas.)

train_df["sum_diffs"] = 0  train_df["sum_diffs"] = train_df[diff_cols].sum(axis=1).values  train_df["d"] = train_df["sum_diffs"] ** 0.5  train_df["frac"] = 1 / (1 + train_df["d"]) ** kappa  train_df["part"] = train_df[target_col] * train_df["frac"]  test_df.loc[index, "pred"] = train_df["part"].sum() / train_df["frac"].sum()

Further down our rabbit hole we need to rely on Numba kernels. At this point, things get tricky. Recall why the algorithm’s predictions are robust because each prediction uses all the rows in the training dataframe. However, the Numba kernels don’t support passing CuDF dataframes. Right now the we are experimenting with some tricks suggested on Github to handle this case. (https://github.com/rapidsai/cudf/issues/13375)

For now, we can at least pass of the raw compute to a numba kernel via the .apply_rows

def predict_kernel(F, T, numer, denom, kappa):      for i, (x, t) in enumerate(zip(F, T)):          d = abs(x - t)  # the distance measure          w = 1 / pow(d, kappa)  # parameterize non-linear scaling          numer[i] = w          denom[i] = d      _tdf = train_df[[att, target_col]].apply_rows(      predict_kernel,      incols={att: "F", "G3": "T"},      outcols={"numer": np.float64, "denom": np.float64},      kwargs={"kappa": kappa},  )    p = _tdf["numer"].sum() / _tdf["denom"].sum()  # prediction - weighted average

At this point, we did not eliminate all for loops, but simply pushing most of the number crunching to Numba reduced the CuDf runtime > 50% landing us in around the 2 to 4 seconds for the standard 80-20 train-test split.

Wrap up

It has been an exhilarating and delightful journey exploring the capabilities of the rapids, cupy, and cudf libraries for various machine learning tasks. These libraries have proven to be user-friendly and easily understandable, making it accessible to most users. The design and maintenance of these libraries are commendable, allowing users to dive deep into the intricacies when necessary. In just a few hours a day over the course of a week, we were able to progress from being novices to pushing the boundaries of the library by implementing a highly customized prediction algorithm. Our next aim is to achieve unprecedented speed, aiming to break the micro-second barrier with large datasets ranging from 20K to 30K. Once this milestone is reached, we plan to release the algorithm as a pip package powered by rapids, making it available for wider adoption and usage.

Kris Manohar is a executive director at ICPC, Trinidad and Tobago.

More On This Topic

  • RAPIDS cuDF Cheat Sheet
  • Mastering String Transformations in RAPIDS libcudf
  • Zero to RAPIDS in Minutes with NVIDIA GPUs + Saturn Cloud
  • RAPIDS cuDF to Speed up Your Next Data Science Workflow
  • RAPIDS cuDF for Accelerated Data Science on Google Colab
  • GPU-Powered Data Science (NOT Deep Learning) with RAPIDS

Mitigating AI biases in healthcare with Amy Brown from Authenticx

Mitigating AI biases in healthcare with Amy Brown from Authenticx Rebecca Szkutak Dominic-Madori Davis 8 hours

Welcome back to Found, where we get the stories behind the startups.

This week Becca and Dom are joined by Amy Brown, the co-founder and CEO of Authenticx, a Midwestern startup that helps insurance companies and medical organizations extract data from their call centers using AI. Amy told Becca and Dom about how her background working in the same call centers inspired her to foray into entrepreneurship. She also talked about the sacrifices and very human side of being an entrepreneur and how they were very intentional when building their AI model.

Subscribe to Found to hear more stories from founders each week.

Connect with us:

  1. On Twitter
  2. On Instagram
  3. Via email: found@techcrunch.com

Google Faces Potential Breakup of Ad-tech Business by European Commission

The European Commission has formally charged Google with an antitrust complaint related to its advertising technology, known as ad-tech. The Commission’s preliminary conclusion is that Google has distorted competition in the ad-tech industry in Europe by favouring its own online display advertising technology services at the expense of competing providers. Google has allegedly been promoting its own ads since at least 2014, influencing how they are purchased and published on websites and mobile apps.

According to Margrethe Vestager, the EU’s executive vice-president in charge of competition policy, Google’s dominant position in the online advertising technology sector, where it collects user data, sells advertising space, and acts as an intermediary, has enabled it to harm competitors and increase costs for advertisers. Vestager,also explained that divestiture was being considered due to Google’s pervasive presence in the ad business.

The European Commission has now given Alphabet, Google’s corporate parent, an opportunity to respond to the allegations and present its case.

If Google is found guilty of violating EU antitrust laws, it could face fines of up to 10% of its annual worldwide turnover, which could amount to nearly $28 billion based on its 2022 revenue. The Commission has also suggested potential “structural remedies” to address the antitrust concerns, including restructuring Google’s adtech business to comply with competition rules in the EU.

If the order for divestiture is issued, it could significantly impact Google’s primary revenue stream. While the company offers various services, advertising remains its major income generator, contributing around 80% of its annual revenue in 2022. This case marks the EU’s fourth major decision against Google, following fines totaling over €8 billion in previous antitrust cases. Google is challenging these earlier fines in court.

Google’s vice president of global ads, Dan Taylor, has stated that the company disagrees with the Commission’s view, highlighting that the investigation focuses on a narrow aspect of their advertising business. Taylor emphasised the value that Google’s advertising technology tools provide to websites, apps, and businesses of all sizes.

Big Techs Under Regulatory Stress

This antitrust complaint adds to the regulatory challenges faced by Alphabet and Google. Not only is Google being investigated by the EU, but its advertising business is also under scrutiny outside of Europe. The UK’s Competition and Markets Authority (CMA) is examining Google’s practices for potential anticompetitive behaviour. In the US, the Justice Department and multiple states have filed lawsuits against Google for alleged anticompetitive practices in various segments of its business.

Additionally, big-techs aren’t without trouble in India and Asia either. Top executives from Amazon, Google, Netflix, Microsoft, and other companies were summoned in August 2022 by a parliamentary panel in India to discuss anti-competitive practices. This followed a report that highlighted such practices by Google and Meta.

Subsequently, in October 2022, the Competition Commission of India imposed two penalties on Google, amounting to a total of Rs 2,274 crore (approximately $310 million), for anti-competitive practices related to its Play Store billing policy. In the same month, Google was fined Rs 1,337.76 crore ($162 million) and Rs 936.44 crore ($113 million).

The post Google Faces Potential Breakup of Ad-tech Business by European Commission appeared first on Analytics India Magazine.