The Rise of Lame LLM Papers

The Rise of Lame LLM Papers

A few months ago, AIM made GPT-4 take India’s toughest exam – UPSC. ChatGPT, powered by GPT-4, was able to crack the exam with 162.76 marks. We noted that by altering the inquiry, we could eventually prompt the model to generate accurate responses. However, in the experiment, we only considered the first responses from the bot.

Recently, a paper from MIT researchers named Exploring the MIT Mathematics and EECS Curriculum Using Large Language Models was trending. The paper claimed that GPT-4 scored 100% on MIT’s EECS curriculum with a dataset of 4,550 questions and solutions. Sounded like a great feat before some researchers decided to dig deeper.

Raunak Chowdhari, Neil Deshmukh, and David Koplow from MIT EECS seniors decided to investigate the paper and were left disappointed with the results. The researchers found out that the questions on the paper were incomplete and there was no way that GPT-4 could have found the right answers, and it didn’t.

A recent work from @iddo claimed GPT4 can score 100% on MIT's EECS curriculum with the right prompting.
My friends and I were excited to read the analysis behind such a feat, but after digging deeper, what we found left us surprised and disappointed.https://t.co/mpDqlenk04
🧵 https://t.co/EVTToZUzL8

— Raunak Chowdhuri (@sauhaarda) June 17, 2023

Moreover, researchers of the paper used GPT-4 to evaluate and score the answers generated by GPT-4. They even continuously prompted GPT-4 until the right answer was achieved. And when the answers were not being corrected, full answers were provided to GPT-4 in the uploaded dataset, so that the model can output it as its own. When the three researchers tried running zero-shot GPT-4 on the dataset, the results were only 62.5%, significantly worse than the 90% correctness claimed by the paper.

The paper has 15 authors. It becomes inexcusable for them to push off the criticism by saying that the paper is not peer reviewed. The problems with the dataset and methodology could have been pointed out and corrected by any one of them. But it appears to be an intentional “mistake” to publish false information for the sake of making headlines.

The researchers concluded that there has been this trend in the AI research field recently — shrinking timeline for research resulting in finding shortcuts in research. This along with taking GPT-4 as the benchmark for testing LLMs comes with a lot of problems as the reliability is not measured against a human counterpart, just another LLM model, which is also hallucinatory.

Where it all started

OpenAI is also no stranger to publishing lame papers. Earlier, researchers were criticising the closed-door policy of the company for publishing absolutely no technicalities in the GPT-4 paper. Next came the paper trying to qualify GPT as a general purpose technology and measuring the technology’s impact on jobs over the years while also promoting everyone to use it.

In the research field, the trend and touted capabilities of GPT-4 have made everyone compare their research with it. GPT-4 at this point is being regarded as “ground-truth” for every new technological advancement, specifically in the field of LLM.

Moreover, the black-box approach of the GPT-4 paper has been followed by anyone and everyone. A user on the HackerNews’ discussion of the MIT paper says that machine learning is not a scientific field anymore, therefore, “anyone can say and do whatever they like and there’s no way to tell them that what they’re doing is wrong.” It has become like social sciences — unfalsifiable and unreproducible research built on top of another unfalsifiable and non-reproducible research.

It is worth noting that there have been no good metrics and meaningful benchmarks for language generation models for decades now. People end up citing and choosing whatever approach and model to compare results with, resulting in no standardised metric for capabilities of a specific approach.

Chasing the gold rush

Currently, a lot of research in the field of LLM and generative AI after the release of OpenAI’s GPT models is just following the trend and hype in a bid to stay relevant. This results in a lot of nuanced research with no proper grounding or credibility, leading to a rush of false papers on the internet.

This definitely sets a bad precedent in the field of AI research, making everyone question the authenticity of research papers. This also makes one wonder — what fraction of the papers on the internet are actually lame but haven’t faced similar scrutiny? And with the current trend of the “ground-truth” GPT-4 writing papers, the quality is expected to go down even further.

The post The Rise of Lame LLM Papers appeared first on Analytics India Magazine.

How governments use alternative data to inform policy decisions

Front view, Capitol dome building at night, Washington DC, USA. Illuminated Home of Congress and Capitol Hill. The concept of cyber security to protect confidential information, padlock hologram

Alternative data generally refers to information beyond traditional sources that include corporate financial statements and filings, stock market data, and government reports. Initially used by investment firms, today, alternative data is also actively utilized by government agencies to analyze economic, social, and political environments and formulate policies.

More information than ever before is being digitized, creating new alternative data sources. This article summarizes these sources and provides examples of how governments use alternative data to implement policies aimed at improving social welfare, crime rates, healthcare, and the environment.

Alternative data sources are growing

The use of digital applications to conduct business, governmental, and social transactions — commonly referred to as “digitization” — leads to an increase in the production of public data. As a result, sources of alternative data are growing and presently include:

1. Mobile and desktop applications

Applications are a trove of data revealing insights into consumer preferences and behaviors. Industries that collect data and use this particular source include travel, food delivery, consumer goods, health and fitness, transportation, and entertainment.

2. Credit and debit card transactions

Credit and debit card transactions reveal insights into consumer spending habits, preferences, and disposable income. Common use cases include academic, government, and marketing research.

3. Email receipt transaction data

Similar to credit and debit card transaction data, receipts sent via email to purchasers reveal critical information about consumer behavior and spending patterns.

Subject to privacy laws and regulations, email receipt transaction data is obtained from various sources, including email service providers and third-party data firms. Common use cases include academic, government, and marketing research.

4. Satellite data

Satellites are a valuable way to collect environmental and human behavior data. Examples include measuring and monitoring vegetation, land use, coastline changes, soil moisture, surface elevation, tectonic activity, melting glaciers, temperature changes, and air quality.

5. Low-level drones

Drones equipped with cameras and sensors can capture high-resolution images, videos, and detailed data from the Earth’s surface. Applications include monitoring changes in building infrastructure, vegetation, agriculture, topography, and air quality.

6. Online public resources

The vast expanse of data available on the internet makes online public resources a dominant source of alternative data. Some examples include:

Public databases

Public databases include filings from the European Securities and Markets Authority (ESMA) and Securities Exchange Commission (SEC), global supply chain import and export records, patent and trademark filings, and government contracts. While valuable, these documents are typically challenging to obtain at a large scale due to inaccessible file formats, like PDF.

Web scraping

Publicly available information on social media sites, marketplaces, and other websites can provide a wide range of alternative data. Some examples include:

  • Real-time product and service pricing data
  • Consumer sentiment data from product reviews
  • Stock, bond, and commodity pricing data
  • Job market data
  • Census data
  • Real-time weather data

Online public data is typically obtained through web scraping — the automated gathering of information from the internet.

Web scraping uses scripts and software tools to extract, parse, and store data in a structured format that analysts can read. Examples of data types gathered by web scraping include text, images, and videos. Watch a live demonstration of a web scraper in action to learn more.

Five ways government agencies use alternative data

Government agencies are increasingly unlocking the power of alternative data to gain insights and make policy decisions that can positively impact citizens.

Recent examples include:

1. Economic “nowcasting”

Nowcasting — a portmanteau of “now” and “forecasting” — uses high-frequency data and statistical models to predict the present or near-term future state of the economy.

Alternative data sources such as social media, online job postings, credit card transactions, and satellites typically provide timelier and more relevant information than traditional sources like government reports. As a result, government agencies (e.g., the Central Bank of Japan) are nowcasting indicators like inflation using alternative sources, such as mobility data.

2. Social welfare programs

The Fundación Paraguaya, a self-sustainable NGO, helps people living in poverty by using alternative data to identify their needs and, based on this, provide resources to help them achieve their goals.

As part of its strategy, the foundation extracts data from a dedicated application and web platform to identify economic trends, generate real-time reports, and create “poverty maps.” These activities enable policymakers to develop strategies that channel aid to areas that need more resources.

3. Environmental policy

The European Union’s Copernicus program collects air and water quality data using various methods (like satellites) to inform policy decisions. For example, satellite data collected by researchers helps identify high-pollution areas. Doing so enables policymakers to make regulatory decisions aimed at reducing emissions.

4. Healthcare and transportation planning

In 2018, the government of Singapore launched “Smart Nation,” a program leveraging technology and data aimed at improving the lives of its citizens. Part of the program involved a pilot project called “Smart Elderly Monitoring and Alert System,” which promoted the use of the Healthy 365 App to monitor the health of elderly residents living in public housing.

Another example was the on-demand public bus service trial in 2018 that paired dynamic routing and matching algorithms to optimize public bus services. Using a mobile app, commuters requested pick-ups and drop-offs at any bus stop on routes with unpredictable or low ridership.

5. Crime reduction

The city of New Orleans in the United States launched a program in 2017 called “Operation: Real-Time Crime Center.” The program used alternative data from several sources to identify and respond to crime in real time, including social media, public cameras, and other surveillance technology.

According to a case study published by the agency, the program reduced murders by 46 percent between 2018 and 2019. In addition, gun violence was reduced by 82 percent in one of the most dangerous areas, and city-wide armed robberies dropped by over 30 percent.

Alternative data obtained via web scraping can positively impact social change

Alternative data is obtained from many places; however, the internet remains the largest and most accessible source of information. You can learn more about alternative data scraping, its challenges, and how to overcome them in our whitepaper: Scraping Alternative Data: Technological Challenges to Keep in Mind.

A Data Scientist’s Essential Guide to Exploratory Data Analysis

A Data Scientist’s Essential Guide to Exploratory Data Analysis
Image from Bing Image Creator Introduction

Exploratory Data Analysis (EDA) is the single most important task to conduct at the beginning of every data science project.

In essence, it involves thoroughly examining and characterizing your data in order to find its underlying characteristics, possible anomalies, and hidden patterns and relationships.

This understanding of your data is what will ultimately guide through the following steps of you machine learning pipeline, from data preprocessing to model building and analysis of results.

The process of EDA fundamentally comprises three main tasks:

  • Step 1: Dataset Overview and Descriptive Statistics
  • Step 2: Feature Assessment and Visualization, and
  • Step 3: Data Quality Evaluation

As you may have guessed, each of these tasks may entail a quite comprehensive amount of analyses, which will easily have you slicing, printing, and plotting your pandas dataframes like a madman.

Unless you pick the right tool for the job.

In this article, we’ll dive into each step of an effective EDA process, and discuss why you should turn ydata-profiling into your one-stop shop to master it.

To demonstrate best practices and investigate insights, we’ll be using the Adult Census Income Dataset, freely available on Kaggle or UCI Repository (License: CC0: Public Domain).

Step 1: Data Overview an Descriptive Statistics

When we first get our hands on an unknown dataset, there is an automatic thought that pops up right away: What am I working with?

We need to have a deep understanding of our data to handle it efficiently in future machine learning tasks

As a rule of thumb, we traditionally start by characterizing the data relatively to the number of observations, number and types of features, overall missing rate, and percentage of duplicate observations.

With some pandas manipulation and the right cheatsheet, we could eventually print out the above information with some short snippets of code:

Dataset Overview: Adult Census Dataset. Number of observations, features, feature types, duplicated rows, and missing values. Snippet by Author.

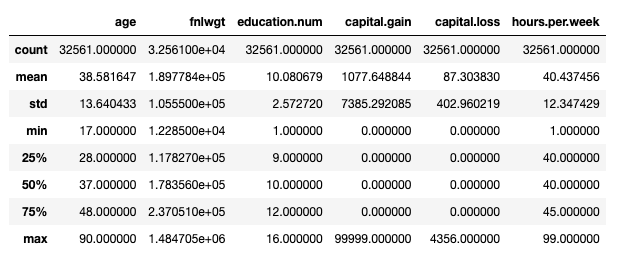
All in all, the output format is not ideal… If you’re familiar with pandas, you’ll also know the standard modus operandi of starting an EDA process — df.describe():

A Data Scientist’s Essential Guide to Exploratory Data Analysis
Adult Dataset: Main statistics presented with df.describe(). Image by Author.

This however, only considers numeric features. We could use a df.describe(include='object') to print out some additional information on categorical features (count, unique, mode, frequency), but a simple check of existing categories would involve something a little more verbose:

Dataset Overview: Adult Census Dataset. Printing the existing categories and respective frequencies for each categorical feature in data. Snippet by Author.

However, we can do this — and guess what, all of the subsequent EDA tasks! — in a single line of code, using ydata-profiling:

Profiling Report of the Adult Census Dataset, using ydata-profiling. Snippet by Author.

The above code generates a complete profiling report of the data, which we can use to further move our EDA process, without the need to write any more code!

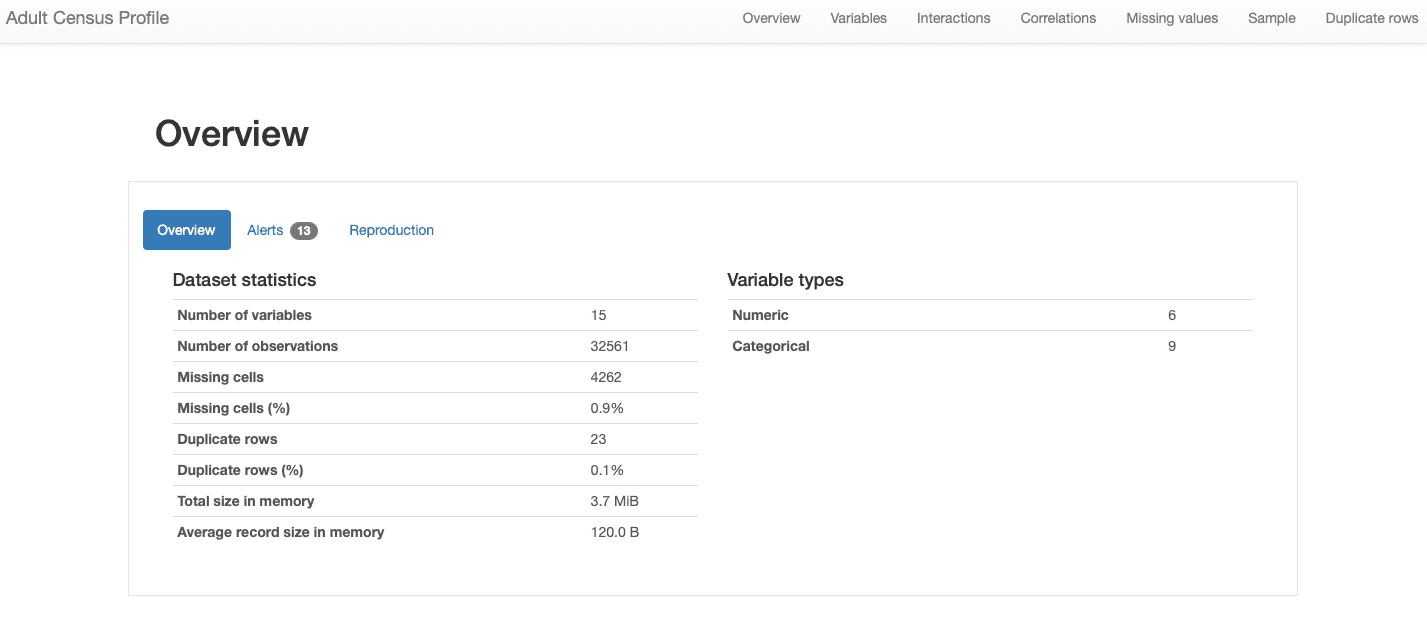
We’ll go through the various sections of the report in the following sections. In what concerns the overall characteristics of the data, all the information we were looking for is included in the Overview section:

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Data Profiling Report — Dataset Overview. Image by Author.

We can see that our dataset comprises 15 features and 32561 observations, with 23 duplicate records, and an overall missing rate of 0.9%.

Additionally, the dataset has been correctly identified as a tabular dataset, and rather heterogeneous, presenting both numerical and categorical features. For time-series data, which has time dependency and presents different types of patterns, ydata-profiling would incorporate other statistics and analysis in the report.

We can further inspect the raw data and existing duplicate records to have an overall understanding of the features, before going into more complex analysis:

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Data Profiling Report — Sample preview. Image by Author.

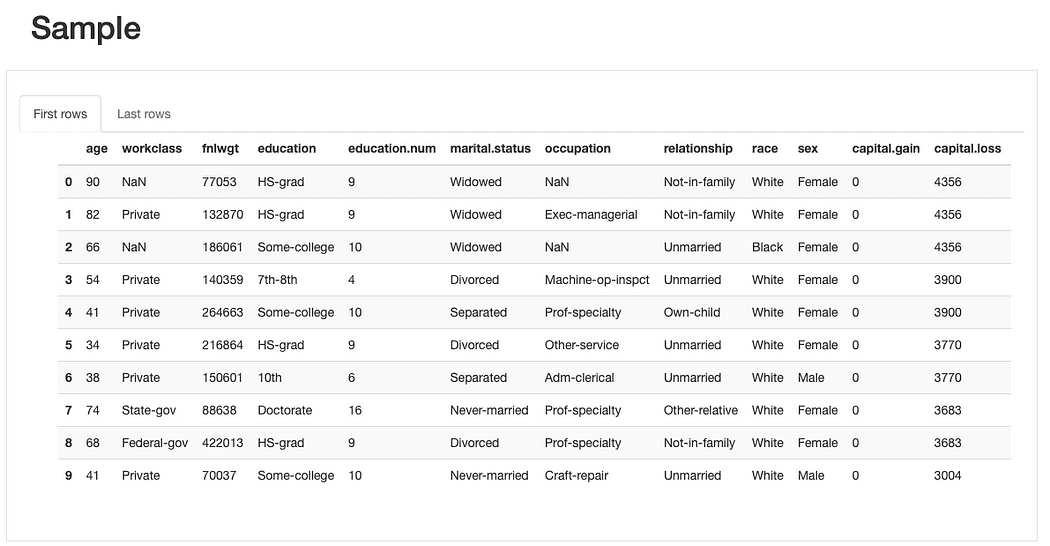
From the brief sample preview of the data sample, we can see right away that although the dataset has a low percentage of missing data overall, some features might be affected by it more than others. We can also identify a rather considerable number of categories for some features, and 0-valued features (or at least with a significant amount of 0’s).

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Data Profiling Report — Duplicate rows preview. Image by Author.

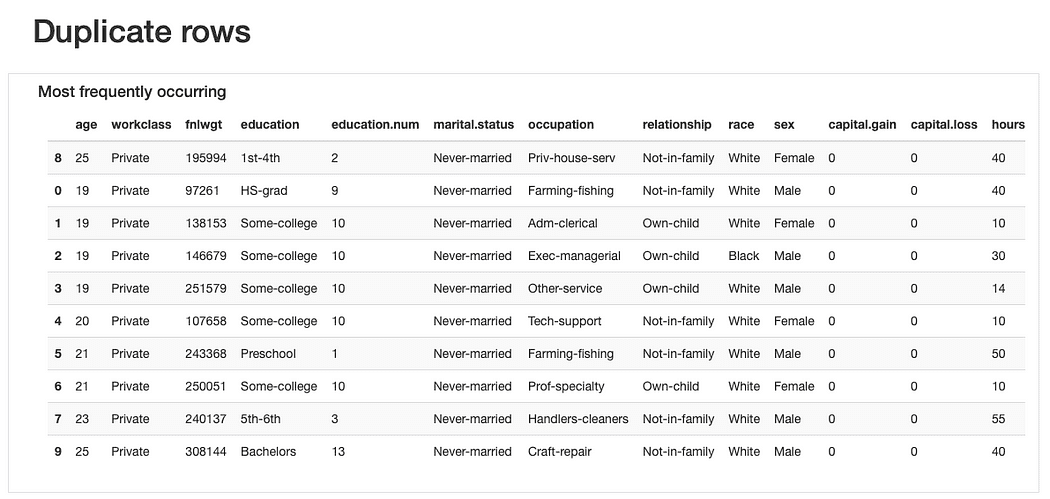
Regarding the duplicate rows, it would not be strange to find “repeated” observations given that most features represent categories where several people might “fit in” simultaneously.

Yet, perhaps a “data smell” could be that these observations share the same age values (which is plausible) and the exact same fnlwgt which, considering the presented values, seems harder to believe. So further analysis would be required, but we should most likely drop these duplicates later on.

Overall, the data overview might be a simple analysis, but one extremely impactful, as it will help us define the upcoming tasks in our pipeline.

Step 2: Feature Assessment and Visualization

After having a peek at the overall data descriptors, we need to zoom in on our dataset’s features, in order to get some insights on their individual properties — Univariate Analysis — as well their interactions and relationships — Multivariate Analysis.

Both tasks rely heavily on investigating adequate statistics and visualizations, which need to be to tailored to the type of feature at hand (e.g., numeric, categorical), and the behavior we’re looking to dissect (e.g., interactions, correlations).

Let’s take a look at best practices for each task.

Univariate Analysis

Analyzing the individual characteristics of each feature is crucial as it will help us decide on their relevance for the analysis and the type of data preparation they may require to achieve optimal results.

For instance, we may find values that are extremely out of range and may refer to inconsistencies or outliers. We may need to standardize numerical data or perform a one-hot encoding of categorical features, depending on the number of existing categories. Or we may have to perform additional data preparation to handle numeric features that are shifted or skewed, if the machine learning algorithm we intend to use expects a particular distribution (normally Gaussian).

Best practices therefore call for the thorough investigation of individual properties such as descriptive statistics and data distribution.

These will highlight the need for subsequent tasks of outlier removal, standardization, label encoding, data imputation, data augmentation, and other types of preprocessing.

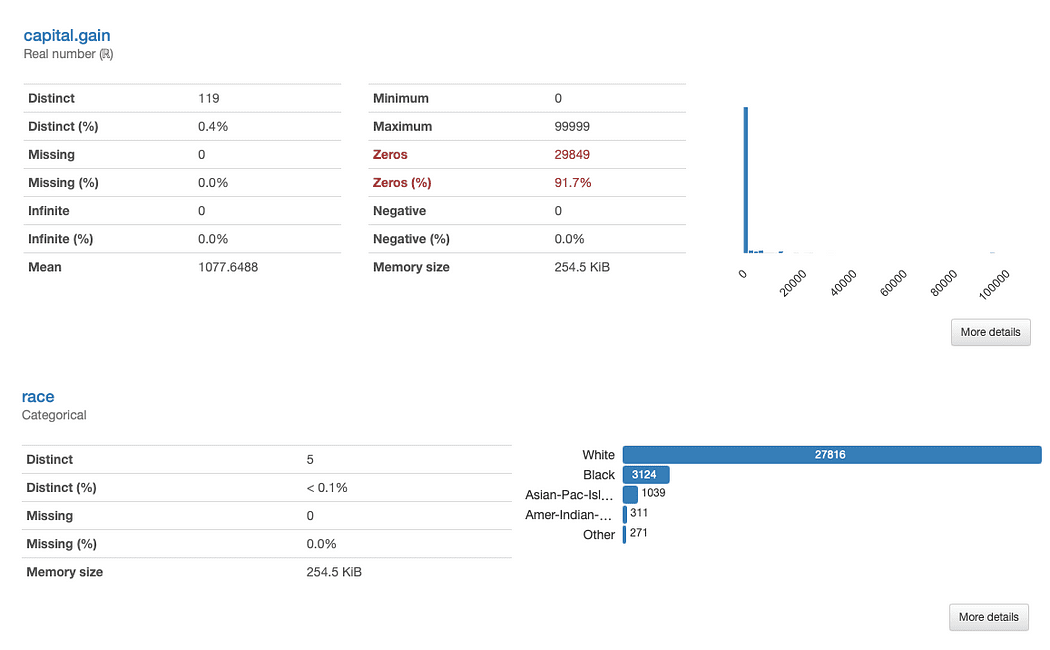
Let’s investigate race and capital.gain in more detail. What can we immediately spot?

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Profiling Report (race and capital.gain). Image by Author.

The assessment of capital.gain is straightforward:

Given the data distribution, we might question if the feature adds any value to our analysis, as 91.7% of values are “0”.

Analyzing race is slightly more complex:

There’s a clear underrepresentation of races other than White. This brings two main issues to mind:

  • One is the general tendency of machine learning algorithms to overlook less represented concepts, known as the problem of small disjuncts, that leads to reduced learning performance;
  • The other is somewhat derivative of this issue: as we’re dealing with a sensitive feature, this “overlooking tendency” may have consequences that directly relate to bias and fairness issues. Something that we definitely don’t want to creep into our models.

Taking this into account, maybe we should consider performing data augmentation conditioned on the underrepresented categories, as well as considering fairness-aware metrics for model evaluation, to check for any discrepancies in performance that relate to race values.

We will further detail on other data characteristics that need to be addressed when we discuss data quality best practices (Step 3). This example just goes to show how much insights we can take just by assessing each individual feature’s properties.

Finally, note how, as previously mentioned, different feature types call for different statistics and visualization strategies:

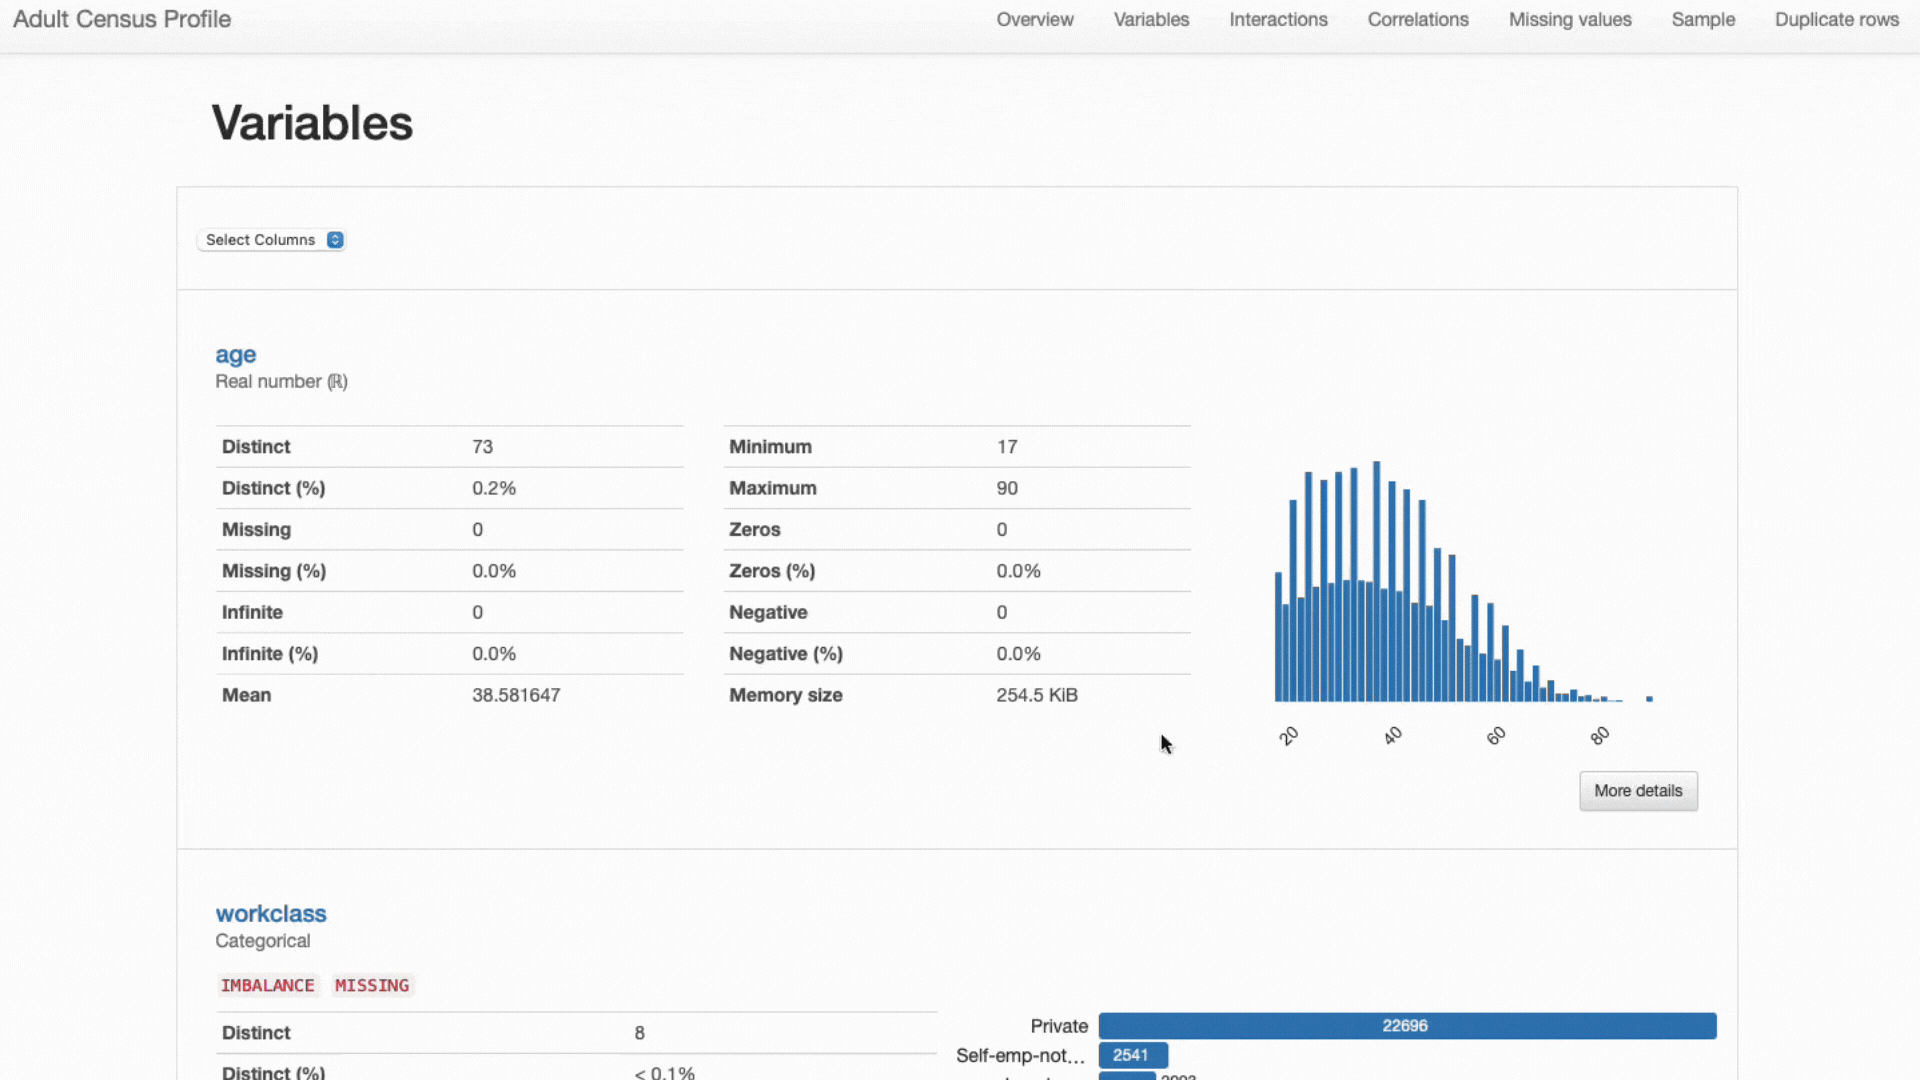
  • Numeric features most often comprise information regarding mean, standard deviation, skewness, kurtosis, and other quantile statistics, and are best represented using histogram plots;
  • Categorical features are usually described using the mode, median, and frequency tables, and represented using bar plots for category analysis.

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Profiling Report. Presented statistics and visualizations are adjusted to each feature type. Screencast by Author.

Such a detailed analysis would be cumbersome to carry out with general pandas manipulation, but fortunately ydata-profiling has all of this functionality built into the ProfileReport for our convenience: no extra lines of code were added to the snippet!

Multivariate Analysis

For Multivariate Analysis, best practices focus mainly on two strategies: analyzing the interactions between features, and analyzing their correlations.

Analyzing Interactions

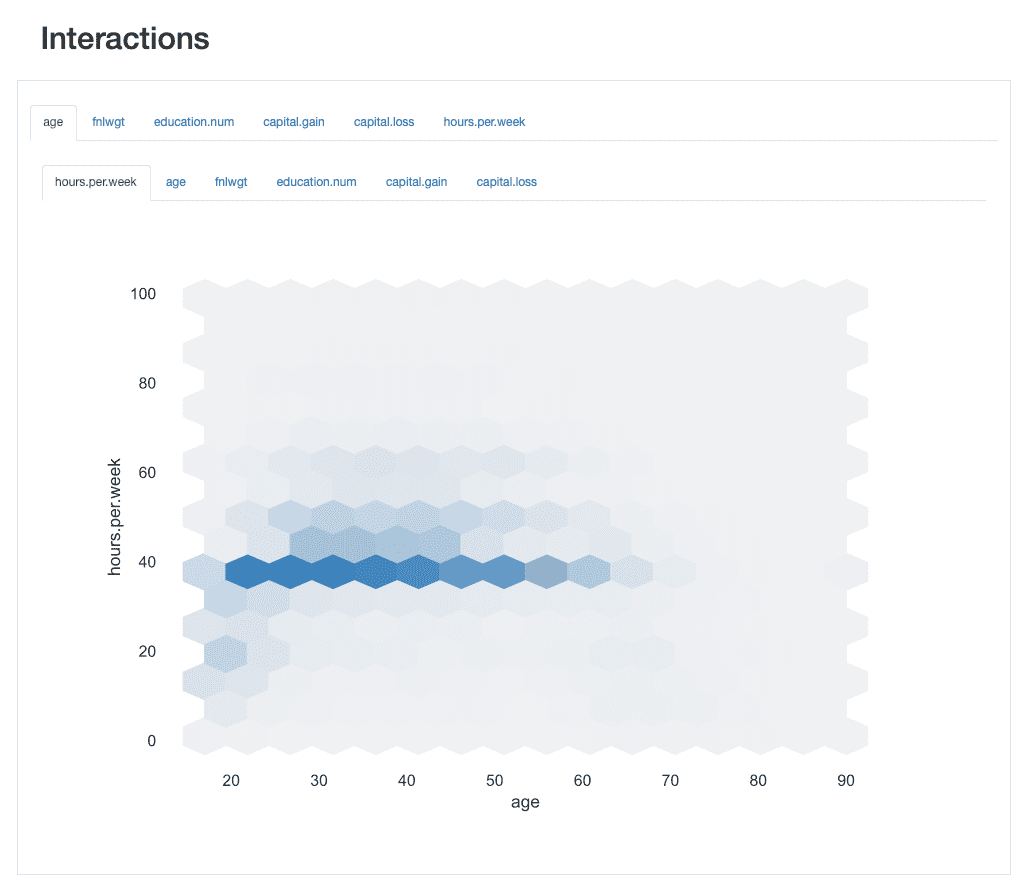
Interactions let us visually explore how each pair of features behaves, i.e., how the values of one feature relate to the values of the other.

For instance, they may exhibit positive or negative relationships, depending on whether the increase of one’s values is associated with an increase or decrease of the values of the other, respectively.

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Profiling Report — Interactions. Image by Author.

Taking the interaction between age and hours.per.weekas an example, we can see that the great majority of the working force works a standard of 40 hours. However, there are some “busy bees” that work past that (up until 60 or even 65 hours) between the ages of 30 and 45. People in their 20’s are less likely to overwork, and may have a more light work schedule on some weeks.

Analyzing Correlations

Similarly to interactions, correlations let us analyze the relationship between features. Correlations, however, “put a value” on it, so that it is easier for us to determine the “strength” of that relationship.

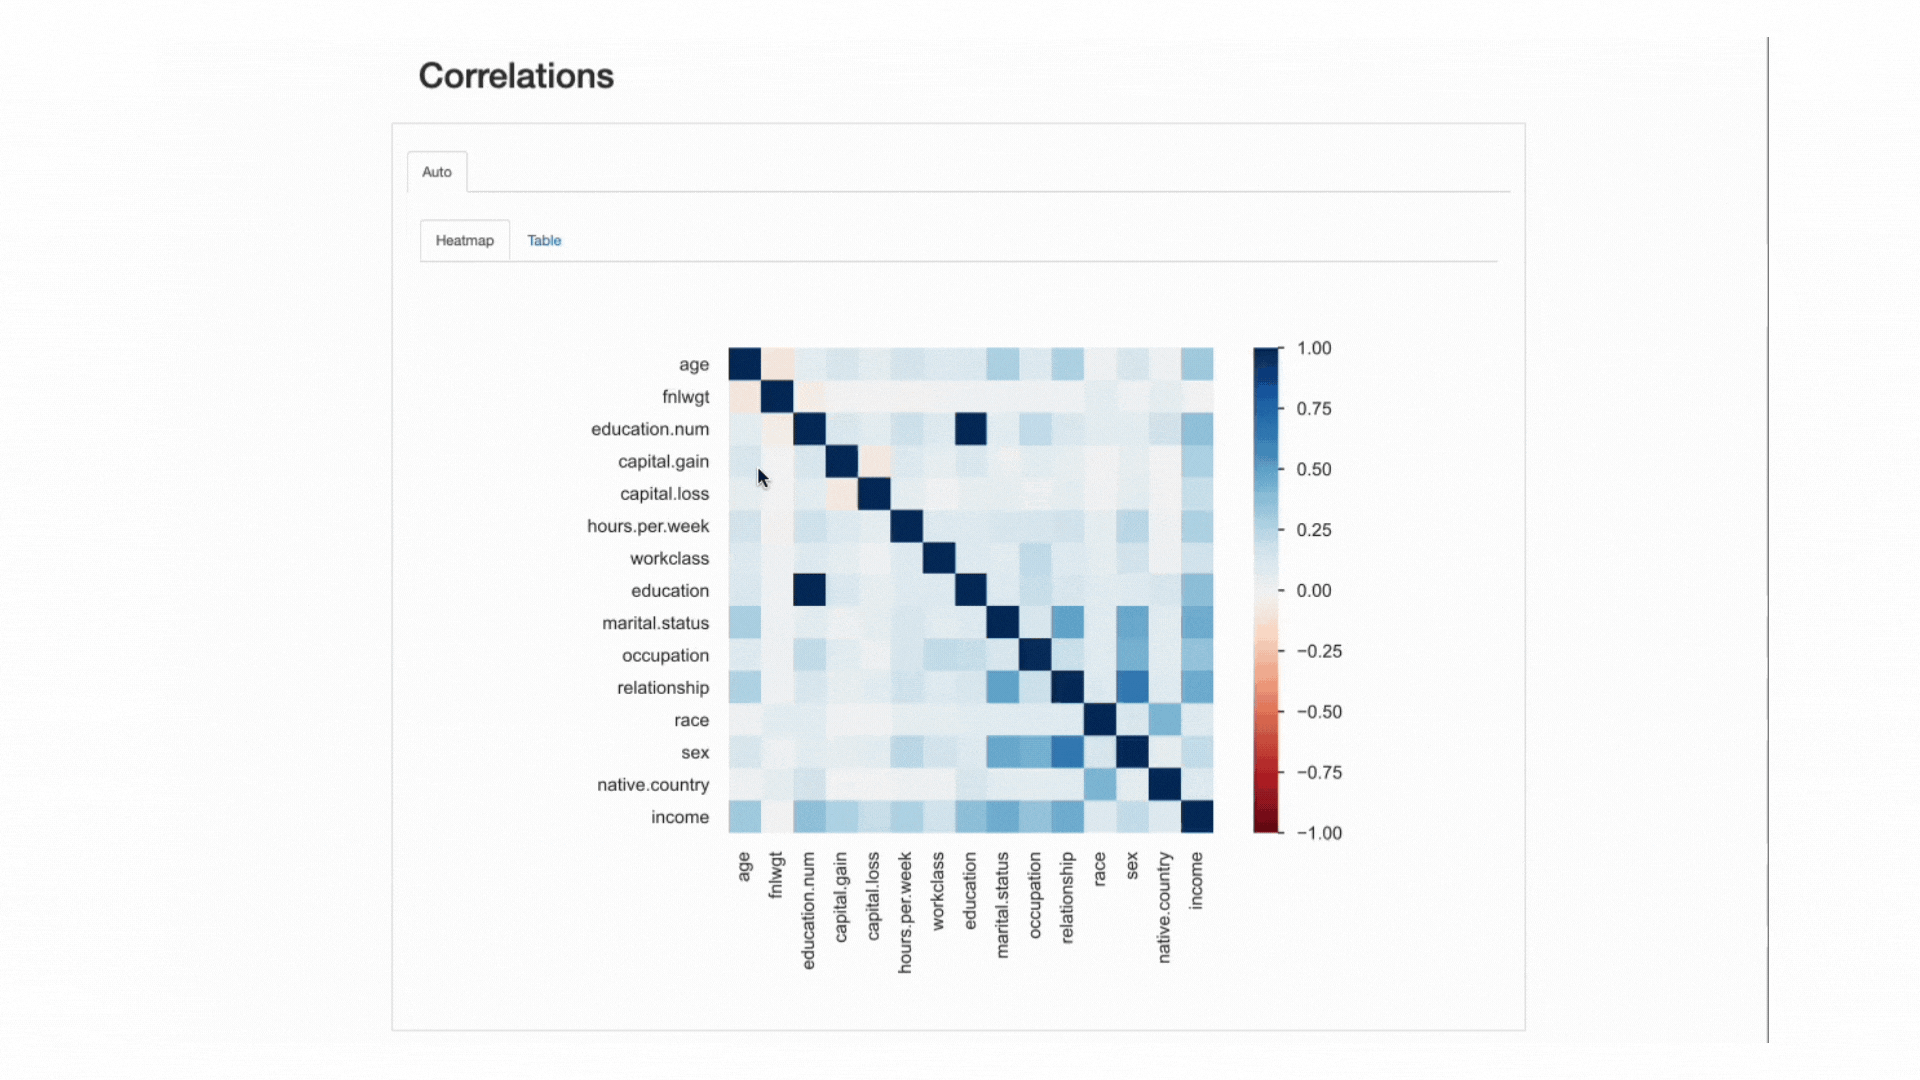
This “strength” is measured by correlation coefficients and can be analyzed either numerically (e.g., inspecting a correlation matrix) or with a heatmap, that uses color and shading to visually highlight interesting patterns:

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Profiling Report — Heatmap and Correlation Matrix. Screencast by Author.

Regarding our dataset, notice how the correlation between education and education.num stands out. In fact, they hold the same information, and education.num is just a binning of the education values.

Other pattern that catches the eye is the the correlation between sex and relationship although again not very informative: looking at the values of both features, we would realize that these features are most likely related because male and female will correspond to husband and wife, respectively.

These type of redundancies may be checked to see whether we may remove some of these features from the analysis (marital.status is also related to relationship and sex; native.country and race for instance, among others).

A Data Scientist’s Essential Guide to Exploratory Data Analysis
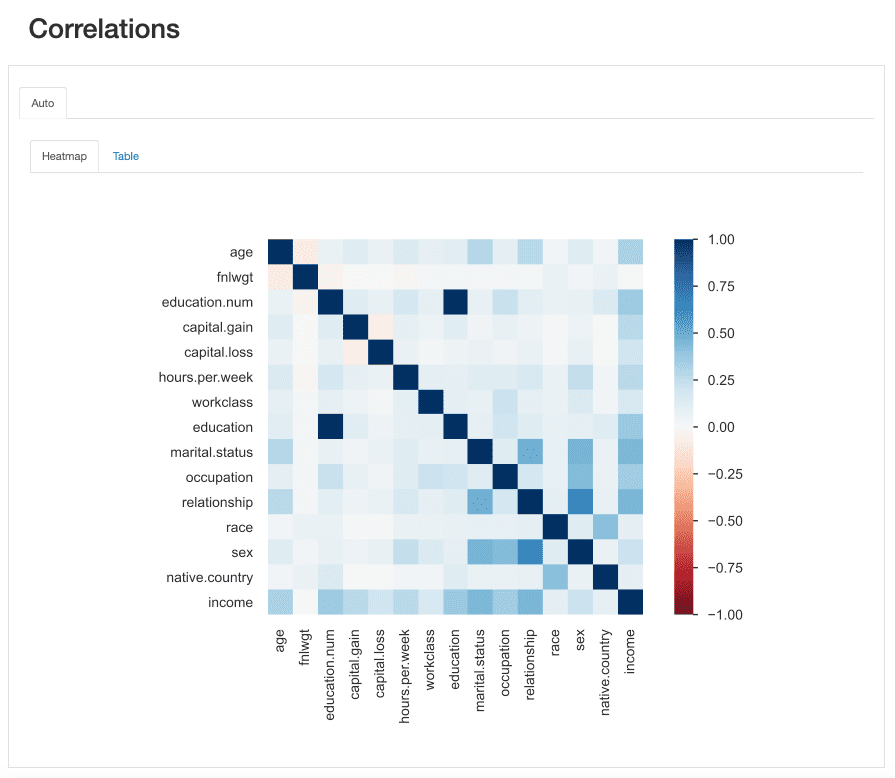
ydata-profiling: Profiling Report — Correlations. Image by Author.

However, there are other correlations that stand out and could be interesting for the purpose of our analysis.

For instance, the correlation betweensex and occupation, or sex and hours.per.week.

Finally, the correlations between income and the remaining features are truly informative, specially in case we’re trying to map out a classification problem. Knowing what are the most correlated features to our target class helps us identify the most discriminative features and well as find possible data leakers that may affect our model.

From the heatmap, seems that marital.status or relationship are amongst the most important predictors, while fnlwgt for instance, does not seem to have a great impact on the outcome.

Similarly to data descriptors and visualizations, interactions and correlations also need to attend to the types of features at hand.

In other words, different combinations will be measured with different correlation coefficients. By default, ydata-profiling runs correlations on auto, which means that:

  • Numeric versus Numeric correlations are measured using Spearman’s rank correlation coefficient;
  • Categorical versus Categorical correlations are measured using Cramer’s V;
  • Numeric versus Categorical correlations also use Cramer’s V, where the numeric feature is first discretized;

And if you want to check other correlation coefficients (e.g., Pearson’s, Kendall’s, Phi) you can easily configure the report’s parameters.

Step 3: Data Quality Evaluation

As we navigate towards a data-centric paradigm of AI development, being on top of the possible complicating factors that arise in our data is essential.

With “complicating factors”, we refer to errors that may occurs during the data collection of processing, or data intrinsic characteristics that are simply a reflection of the nature of the data.

These include missing data, imbalanced data, constant values, duplicates, highly correlated or redundant features, noisy data, among others.

A Data Scientist’s Essential Guide to Exploratory Data Analysis
Data Quality Issues: Errors and Data Intrinsic Charcateristics. Image by Author.

Finding these data quality issues at the beginning of a project (and monitoring them continuously during development) is critical.

If they are not identified and addressed prior to the model building stage, they can jeopardize the whole ML pipeline and the subsequent analyses and conclusions that may derive from it.

Without an automated process, the ability to identify and address these issues would be left entirely to the personal experience and expertise of the person conducting the EDA analysis, which is obvious not ideal. Plus, what a weight to have on one’s shoulders, especially considering high-dimensional datasets. Incoming nightmare alert!

This is one of the most highly appreciated features of ydata-profiling, the automatic generation of data quality alerts:

A Data Scientist’s Essential Guide to Exploratory Data Analysis
ydata-profiling: Profiling Report — Data Quality Alerts. Image by Author.

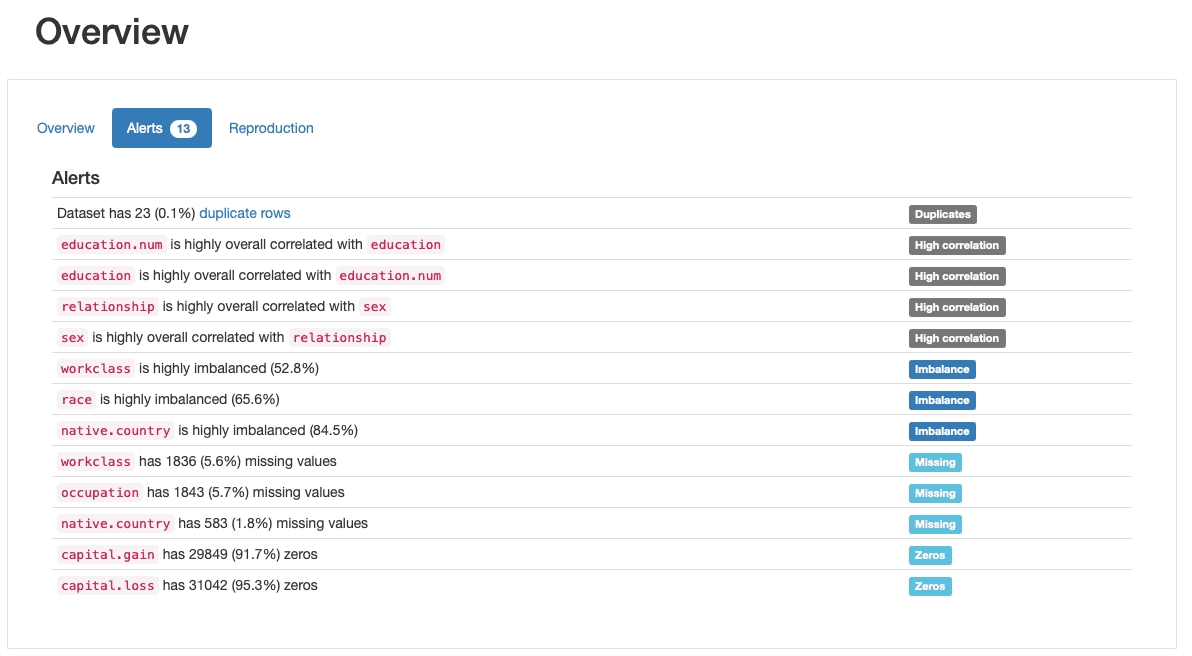
The profile outputs at least 5 different types of data quality issues, namely duplicates, high correlation, imbalance, missing, and zeros.

Indeed, we had already identified some of these before, as we went through step 2: race is a highly imbalanced feature and capital.gain is predominantly populated by 0’s. We’ve also seen the tight correlation between education and education.num, and relationship and sex.

Analyzing Missing Data Patterns

Among the comprehensive scope of alerts considered, ydata-profiling is especially helpful in analyzing missing data patterns.

Since missing data is a very common problem in real-world domains and may compromise the application of some classifiers altogether or severely bias their predictions, another best practice is to carefully analyze the missing data percentage and behavior that our features may display:

A Data Scientist’s Essential Guide to Exploratory Data Analysis
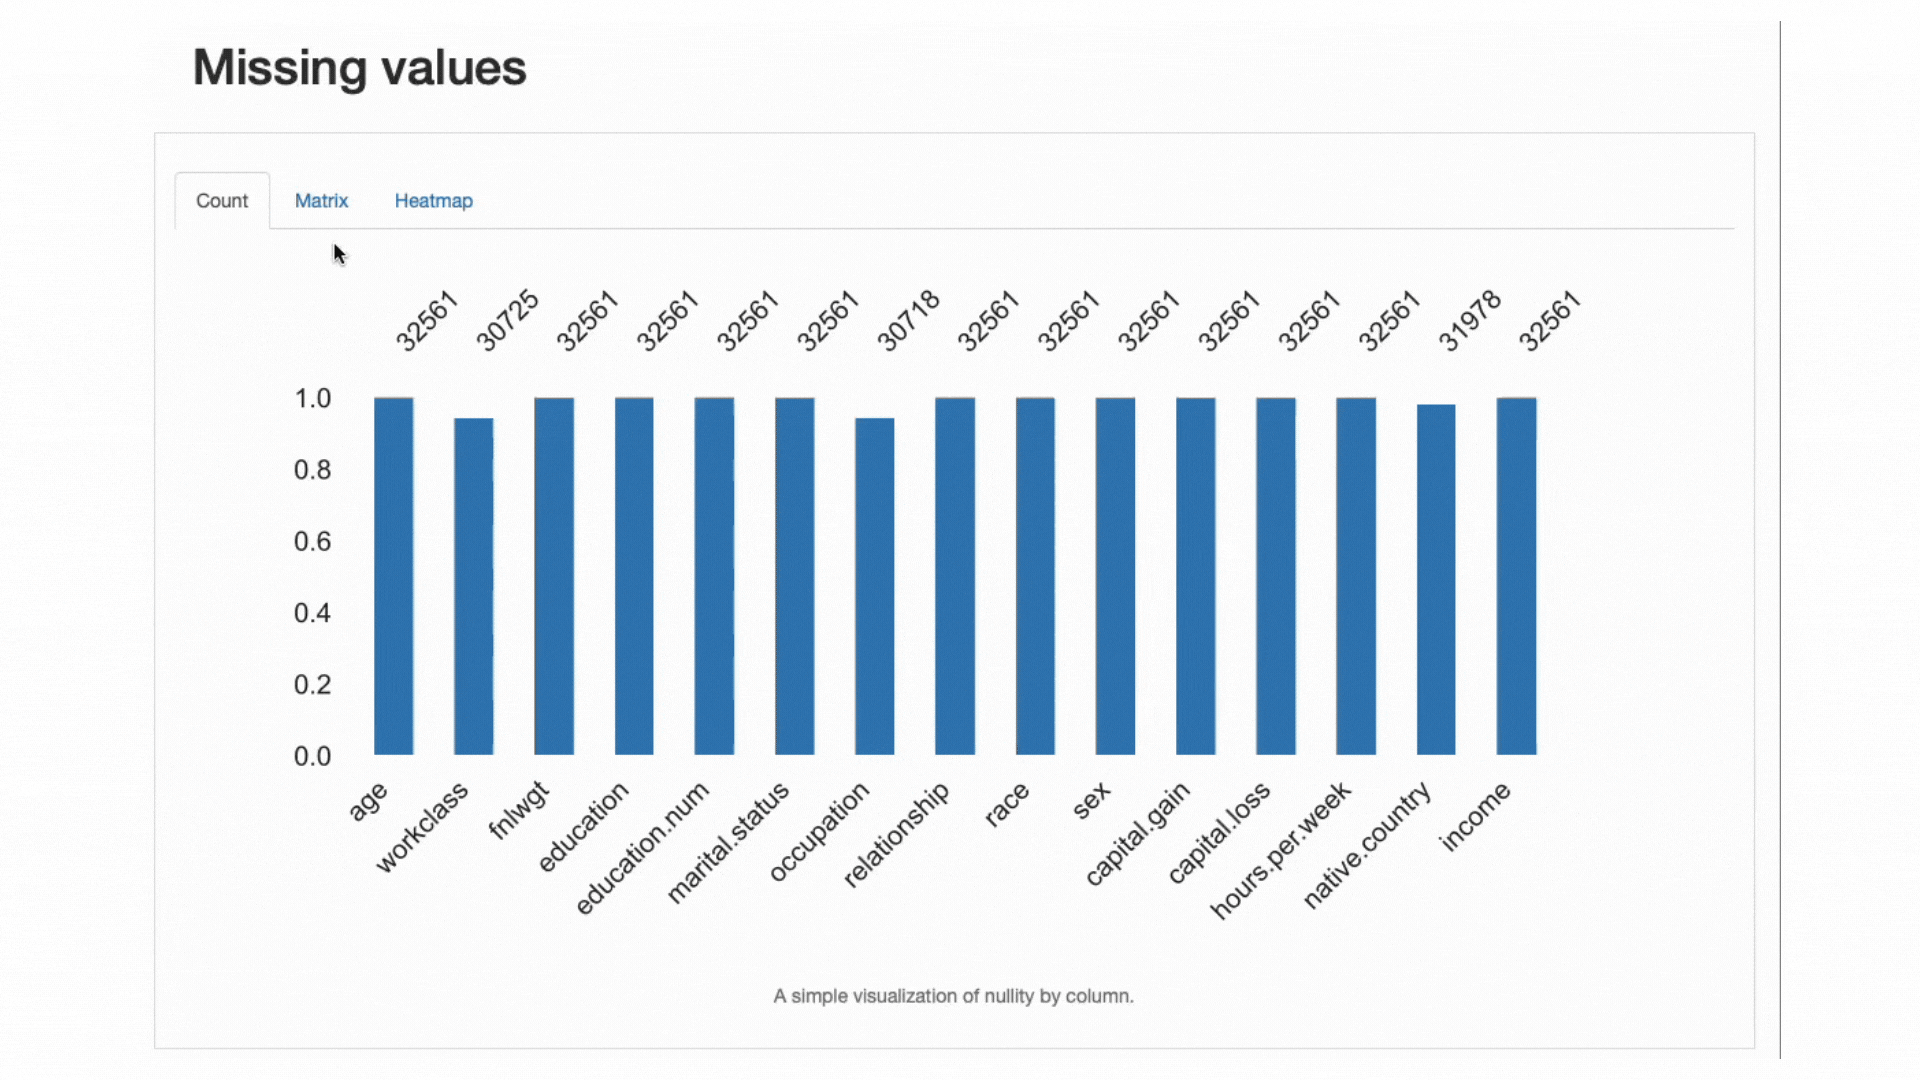
ydata-profiling: Profiling Report — Analyzing Missing Values. Screencast by Author.

From the data alerts section, we already knew that workclass, occupation, and native.country had absent observations. The heatmap further tells us that there is a direct relationship with the missing pattern in occupation and workclass: when there’s a missing value in one feature, the other will also be missing.

Key Insight: Data Profiling goes beyond EDA!

So far, we’ve been discussing the tasks that make up a thorough EDA process and how the assessment of data quality issues and characteristics — a process we can refer to as Data Profiling — is definitely a best practice.

Yet, it is important do clarify that data profiling goes beyond EDA. Whereas we generally define EDA as the exploratory, interactive step before developing any type of data pipeline, data profiling is an iterative process that should occur at every step of data preprocessing and model building.

Conclusions

An efficient EDA lays the foundation of a successful machine learning pipeline.

It’s like running a diagnosis on your data, learning everything you need to know about what it entails — its properties, relationships, issues — so that you can later address them in the best way possible.

It’s also the start of our inspiration phase: it’s from EDA that questions and hypotheses start arising, and analysis are planned to validate or reject them along the way.

Throughout the article, we’ve covered the 3 main fundamental steps that will guide you through an effective EDA, and discussed the impact of having a top-notch tool — ydata-profiling — to point us in the right direction, and save us a tremendous amount of time and mental burden.

I hope this guide will help you master the art of “playing data detective” and as always, feedback, questions, and suggestions are much appreciated. Let me know what other topics would like me to write about, or better yet, come meet me at the Data-Centric AI Community and let’s collaborate!

Miriam Santos focus on educating the Data Science & Machine Learning Communities on how to move from raw, dirty, "bad" or imperfect data to smart, intelligent, high-quality data, enabling machine learning classifiers to draw accurate and reliable inferences across several industries (Fintech, Healthcare & Pharma, Telecomm, and Retail).

Original. Reposted with permission.

More On This Topic

  • 11 Essential Code Blocks for Complete EDA (Exploratory Data Analysis)
  • A Lightning Fast Look at Single Line Exploratory Data Analysis
  • Exploratory Data Analysis Techniques for Unstructured Data
  • How Visualization is Transforming Exploratory Data Analysis
  • Powerful Exploratory Data Analysis in just two lines of code
  • The Essential Guide to Transformers, the Key to Modern SOTA AI

If you use AI-generated code, what’s your liability exposure?

Hand touching data points

There will be hackers, criminals, rogue nation states, high school students, and crackpots all attempting to feed erroneous data into every AI they can find.

As we continue to explore the legal implications of using AI-generated code, I wanted to extend a big thanks to ZDNET commenter @pbug5612 for inspiring us to journey down this rabbit hole.

In our first article of the series, we looked at who owns the code created by AI chatbots like ChatGPT. In this article, we'll discuss issues of liability.

Also: The best AI chatbots: ChatGPT and other noteworthy alternatives

Functional liability

To frame this discussion, I'll turn to attorney and long-time Internet Press Guild member Richard Santalesa. With his tech journalism background, Santalesa understands this stuff from both a legal and a tech perspective. (He's a founding member of the SmartEdgeLaw Group.)

"Until cases grind through the courts to definitively answer this question," Santalesa advises, "the legal implications of AI-generated code are the same as with human-created code."

Keep in mind, he continues, that code generated by humans is far from error-free. You'll never see a service level agreement warranting that code is perfect or that users will have uninterrupted use of the services.

He also points out that it's rare for all parts of a software application to be entirely home-grown. He says, "Most coders use SDKs and code libraries that they have not personally vetted or analyzed, but rely upon nonetheless. I think AI-generated code — for the time being — will be in the same bucket as to legal implications."

Also: ChatGPT and the new AI are wreaking havoc on cybersecurity in exciting and frightening ways

Send in the trolls

Sean O'Brien, a lecturer in cybersecurity at Yale Law School and founder of the Yale Privacy Lab, pointed out a risk for developers that's undeniably worrisome:

The chances that AI prompts might output proprietary code are very high, if we're talking about tools such as ChatGPT and Copilot which have been trained on a massive trove of code of both the open source and proprietary variety.

We don't know what trained the chatbots. And so we don't know if segments of code output from ChatGPT and other similar tools are generated by the AI or merely echoed back from code that it ingested as part of the training process.

If you're a developer, it's time to sit down. Here's O'Brien's prediction:

I believe there will soon be an entire sub-industry of trolling that mirror patent trolls, but this time surrounding AI-generated works. As more authors use AI-powered tools to ship code under proprietary licenses, a feedback loop is created. There will be software ecosystems polluted with proprietary code that will be the subject of cease-and-desist claims by enterprising firms.

As soon as Yale's Sean O'Brien mentioned the troll factor, the hairs on the back of my neck stood up. This is going to be very, very messy. Think about that and try not to get ill.

Here's another thought. There will be those who attempt to corrupt the training corpora (the sources of knowledge that AIs use to provide their results). One of the things we humans do is find ways to game the system. So not only will there be armies of legal trolls trying to find folks to sue, there will be hackers, criminals, rogue nation states, high school students, and crackpots, all attempting to feed erroneous data into every AI they can find, either for the lulz or for much more nefarious reasons.

Also: 5 ways to explore the use of generative AI at work

Maybe try not to think about that too much.

Canadian attorney Robert Piasentin, a partner in the Technology Group at McMillan LLP, a Canadian business law firm, points out that chatbots could have been trained on open-source work and legitimate sources, but they may also have been trained on copyrighted work. And that training data might include flawed or biased data (or algorithms) as well as corporate proprietary data.

Here's how he describes it: "If the AI draws on incorrect, deficient or biased information, the output of the AI tool may give rise to various potential claims depending on the nature of the potential damage or harm that the output may have caused (whether directly or indirectly)."

Who is at fault?

What none of the lawyers discussed is who is at fault if the code generated by an AI results in some catastrophic outcome.

For example: The person/company delivering a product shares some responsibility for, say, choosing a library that has known deficiencies. If a product ships using a library that has known exploits, and that product causes something that results in tangible harm, who owns that failure? The product maker, the library coder, or the company that chose the product?

Usually, it's all three.

Also: ChatGPT's latest challenger: The Supreme Court

Now add AI code into the mix. Clearly, most of the responsibility falls on the shoulders of the coder who chooses to use code generated by an AI. After all, it's common knowledge that the code may not work and needs to be very thoroughly tested.

But in a comprehensive lawsuit, will claimants also go after the companies that produce the AIs and even those organizations whose content was taken (even if without permission) to train those AIs?

As every attorney has told me, there is very little case law thus far. We won't really know the answers until something goes horribly wrong, parties wind up in court, and it's adjudicated thoroughly.

We're in uncharted waters here. My best advice, for now, is to test your code thoroughly. Test, test, and then test some more.

Also: Low and no-code software may soon test the limits of IT hand-holding

You can follow my day-to-day project updates on social media. Be sure to follow me on Twitter at @DavidGewirtz, on Facebook at Facebook.com/DavidGewirtz, on Instagram at Instagram.com/DavidGewirtz, and on YouTube at YouTube.com/DavidGewirtzTV.

See also

Alibaba prepares for leadership shakeup as CEO moves to focus on cloud

Abstract cloud on blue background

Alibaba Group is preparing for a leadership shakeup that will see its current CEO and chairman Daniel Zhang relinquish his roles and focus exclusively on the company's cloud business.

The announcement Tuesday comes just months after the Chinese tech giant in March unveiled a major overhaul of its organizational structure, which split the company into six business entities, including Cloud Intelligence Group and Taobao Tmall Commerce Group. Each entity has its own CEO and board of directors. Zhang was named CEO and chairman of the cloud business, in addition to his roles as overall group CEO and chairman.

Also: I bought some off-brand geeky stuff from Temu (and wasn't mad about it)

Last month, Alibaba said it was spinning off the cloud unit within a year and having the entity operate as an independent publicly listed company.

Zhang had said the move was necessary amid "challenges and opportunities" in an uncertain economic landscape and pointed to cloud as one of three strategic focus areas for the company.

Plans now are in the works for him to focus solely on the cloud business, with Joseph C. Tsai taking over as chairman and Eddie Wu assuming the role of CEO, in addition to a directorship on the board. Tsai currently is the executive vice chairman, while Wu is chairman of Alibaba's e-commerce business, Taobao and Tmall.

Also: I bought 4 brand-name tech gadgets on Temu for work. Here's how it went

The succession plan will roll out over the next few months, with the new appointments to kick in starting Sept. 10 this year. Wu will retain his role at Taobao and Tmall.

Zhang, who took the group CEO helm in 2015, said the transition was "the right time" given the importance of Alibaba's cloud business as the spinoff plans took shape. He added that the emergence of generative artificial intelligence (AI) had opened up new opportunities that the cloud business was "well-positioned" to capture.

Alibaba in April introduced a partnership program aimed at driving the development of customized generative AI models and applications for companies across various verticals, including finance and petrochemicals. The cloud vendor earlier had launched its own large language model, Tongyi Qianwen, which is expected to be integrated with all of Alibaba's own business applications, including e-commerce, search, navigation, and intelligence voice assistance.

Also: Generative AI should be more inclusive as it evolves, according to OpenAI's CEO

Incoming CEO Wu was CTO of Alipay since December 2004 and chief architect of Alibaba's technology platforms, including the Taobao mobile app, according to Alibaba. He was the technology director at the company's inception in 1999.

In explaining the organizational restructure, Zhang previously said it would allow the respective businesses to be more agile and empower decision-making, so they could respond more quickly to market changes. The move was described as the most significant governance overhaul in Alibaba's 24-year history.

Featured

Oracle Launches Sovereign Cloud for EU Enterprises

Oracle Launches Sovereign Cloud for EU Enterprises

Amid privacy concerns in the EU and the General Data Protection Regulation (GDPR), Oracle has announced the opening of its EU Sovereign Cloud to cater to the needs of enterprises and government entities seeking to comply with evolving data residency and privacy regulations.

Unlike competitors like Amazon Web Services (AWS), Microsoft Azure, and Google Cloud, which provide controls within their existing cloud regions or services to comply with data regulations, Oracle’s EU Sovereign Cloud stands out by maintaining physical separation from its ten existing cloud regions in the EU. By embracing the cloud, organisations can benefit from Oracle’s solutions while adhering to these regulatory frameworks.

The EU Sovereign Cloud will be composed of two data regions or data centres strategically located in Frankfurt and Madrid. These facilities will be operated by Oracle-owned EU legal entities incorporated within the European Union and staffed exclusively by professionals based in the EU. Notably, enterprises from all 27 member states will have equal access to the cloud at the same cost as other existing cloud regions offered by Oracle.

The introduction of the Sovereign Cloud expands Oracle’s extensive network, which already comprises 37 commercial regions and seven government regions spanning across 23 countries. Furthermore, in a recent announcement, the company expressed its intention to launch a new cloud region in Serbia.

In further advancements, Oracle has introduced two new data security measures to its Vault Key Management feature as part of the Sovereign Cloud. These measures include the OCI Dedicated Key Management Service and the OCI External Key Management Service.

External Key Management capability empowers enterprises to encrypt their data using encryption keys that are generated and managed by the customer externally, outside of OCI. Oracle also enables seamless connectivity of data to OCI’s virtual cloud network through a dedicated private connection.

Presently, the newly established Sovereign Cloud is compatible with FastConnect partners including Arelion, DE-CIX, Digital Realty, Equinix, and InterCloud.

Disaster recovery will be a key focus of the two data centres established within the EU Sovereign Cloud, aiming to enhance data security and safeguard against unforeseen disruptions. This strategic decision builds upon Oracle’s earlier announcement of its intention to introduce the EU Sovereign Cloud back in July 2022.

Read: 2022 in Review: Oracle

To ensure compliance with relevant regulations, the newly launched EU Sovereign Cloud adheres to the Schrems II ruling, guidelines from the European Data Protection Board (EDPB), and other evolving frameworks like NIS 2.

Leo Leung, Oracle’s Vice President of Products and Strategy, emphasised that the Sovereign Cloud regions follow the principles of their Government Cloud offerings in the United States and the United Kingdom. In the US, Oracle provides separate Government Clouds tailored to defence and administrative bodies, each equipped with distinct security features.

Oracle’s expansion of the EU Sovereign Cloud aims to empower organisations across Europe to leverage the advantages of cloud computing while meeting the intricate requirements posed by data residency and privacy regulations.

The post Oracle Launches Sovereign Cloud for EU Enterprises appeared first on Analytics India Magazine.

How to Avoid an AI Winter and Kick-start the AI Renaissance

How to Avoid an AI Winter and Kick-start the AI Renaissance June 20, 2023 by Anthony Chong

Generative AI solutions like ChatGPT and Bard are both exciting and impressive in their ability to take in enormous datasets and build complex correlations to generate content from just a simple prompt. The massive advances realized by these approaches are an indicator that the field of artificial intelligence is on the verge of a renaissance. The trouble is that neither ChatGPT nor Bard are able to check the accuracy of their answers and, let’s face it, there’s a huge difference between sounding correct and actually performing well. As a result, chatbots are not actually useful for solving business problems.

If this disconnect sounds familiar, it’s because we’ve been at this exciting technological precipice before. The 1950s saw the computational boom that led to the coining of the term “artificial intelligence” itself, and the 1980s saw breakthroughs in neural networks and the personal computing revolution that enabled widespread access to computation. But at both of those junctures, AI never met the lofty expectations generated from the hype. The subsequent disappointment and disillusionment with the technology led to a stagnation in research funding and a decline in the development of artificial intelligence technologies. The result was the beginning of the "AI Winter."

To avoid another stagnation, it is important to acknowledge the real limitations of generative AIs and address these limitations by developing and strengthening other key AI technologies.

How Generative AIs Work

Generative AIs use large language models, which are neural networks trained on a vast amount of text. Their power comes from their ability to build correlations on these massive datasets. Once the AI has been trained on sufficient data, if given a short prompt, it can then recall the style of the text it has seen before, and generate content with a similar design.

While the technological prowess these AIs demonstrate carries the same excitement as the development of web browsers in the 1990s, there are different beliefs as to how to move the field forward. Some believe that generative AIs can solve any problem, given enough data; their path towards an AI renaissance simply requires training generative models on more data. But this is fundamentally ignorant of the fact that there are entire classes of problems that generative AIs simply cannot address.

Buyer Beware: Understanding the Current Limitations of Generative AIs

Despite the interest in ChatGPT and Bard, users/and scholars both indicate that there is a huge, and consequential, difference between sounding correct and truly performing well. Sure, generative AIs are producing answers to prompts that sound impressive, but they are not necessarily accurate. This is because they are not designed to understand if their answers are correct and there’s a wide swath of problems where accuracy is of the utmost importance. The problem is that traditional generative AIs are trained on generic models using an abundance of unvetted data and they are incapable of leveraging a business’ internal data. Though internal data is necessary to answer some of the most urgent problems, generative AIs are unlikely to get access anytime soon as sensitive customer data would not be public on the internet, and generative AIs are not constructed to learn from smaller, “business-sized” data.

As Noam Chomsky points out, another example of ChatGPT’s limitations involves the concept of causation. For instance, if a person asks a question such as “If it rains, will the grass be wet?” intuitively, that person would understand that the rain causes the grass to be wet. Yet, ChatGPT is not programmed to have a sense of causality, to understand the hierarchy of knowledge that underpins a logical sense of cause-and-effect. Another often overlooked limitation of ChatGPT involves the computing costs needed to support it. Each subsequent generation of generative AI requires major increases to compute costs as it needs to intake more and more information to improve its correlative approaches making it prohibitively expensive for most organizations.

Alternative Technologies Poised to Jump-start the AI Renaissance

For AIs to become truly powerful in solving a wide class of problems, other technologies will need to develop concurrently with generative AI. Combining a variety of modern technologies can compound gains in their ability and guide AI into a renaissance. These include:

  • Causal AI which is designed to determine cause and effect and control for other variables. It’s standard industry practice to use A/B testing to figure out what intervention—e.g. “What sized promotional discount should I be sending my customers?” — and determine causes distinct to an individual customer’s behaviors. Running A/B testing at massive scales, with many different simultaneous variables, is tricky—and here is where the power of causal AIs can be harnessed. Correlative AIs alone cannot understand the logical chain reactions that underpin the reasons why, if it is raining, a person may not want to have a picnic.
  • Online Learning is a technical term for an AI that continuously updates itself based on conditions, predictions, and accuracy. Current generative AIs are unable to update themselves based on feedback in real time. Consider the pandemic. Consumer habits change drastically and no amount of historical data could have predicted how buyer behavior would change and how organizations would need to pivot. Bottom line is any AI worth its salt needs to be nimble enough to learn “on the ground,” in real time, and provide answers based on actual conditions to solve the relevant problem.

With this combination of technologies, AI can tackle a myriad of different classes of problems. Notably, while AI has ordinarily worked with massive datasets, having an “AI Swiss Army Knife” can enable decision making on the scale of individual datapoints and limited datasets like the transactions of a single business. More importantly, it could be the start of a true AI renaissance that the world has been waiting for.

About the Author

Anthony Chong is CEO/Co-Founder of IKASI, providers of sophisticated, predictive AI solutions that help organizations drive profits. To learn more, visit them, connect on LinkedIn, or follow them on Twitter.

Related

Orca LLM: Simulating the Reasoning Processes of ChatGPT

Orca LLM: Simulating the Reasoning Processes of ChatGPT

Introduction

In the realm of large language models (LLMs), there has been a constant pursuit to enhance the capabilities of smaller models without compromising their efficiency. The traditional approach has been to use imitation learning, where smaller models learn from the outputs generated by large foundation models (LFMs). However, this approach has been marred by several challenges, including limited imitation signals from shallow LFM outputs, small-scale homogeneous training data, and a lack of rigorous evaluation. This often leads to smaller models imitating the style but not the reasoning process of LFMs.

The paper Orca: Progressive Learning from Complex Explanation Traces of GPT-4 introduces Orca, a 13-billion parameter model designed to imitate the reasoning process of large foundation models (LFMs) such as GPT-4. Unlike traditional large language models (LLMs), Orca employs a unique training approach that combines progressive learning and teacher assistance to overcome the capacity gap between smaller student models and their larger counterparts.

Training Methodology

Orca's training process consists of two stages.

In the first stage, Orca is trained on FLAN-5M, which includes ChatGPT augmentations. This intermediate teacher assistant helps bridge the capacity gap between Orca and GPT-4, which has a significantly larger parameter size. By leveraging ChatGPT's capabilities, Orca benefits from improved imitation learning performance.

In the second stage, Orca undergoes training on FLAN-1M, which incorporates GPT-4 augmentations. This progressive learning approach follows a curriculum learning paradigm, where the student model learns from easier examples before tackling more challenging ones. By gradually exposing Orca to increasingly complex reasoning and step-by-step explanations, the model enhances its reasoning abilities and mimicking skills.

Advantages and Contributions

Orca's training methodology offers several advantages over traditional LLMs.

Firstly, it addresses the capacity gap issue by utilizing an intermediate teacher model, allowing Orca to learn from a more capable source. This approach has been shown to improve imitation learning performance for smaller student models.

Secondly, the progressive learning aspect of Orca's training enables the model to build upon its knowledge incrementally. By starting with simpler examples and gradually introducing more complex ones, Orca develops a stronger foundation for reasoning and explanation generation.

Furthermore, Orca's ability to imitate the reasoning process of LFMs like GPT-4 opens up possibilities for enhanced performance in various tasks. By tapping into the rich signals provided by GPT-4's explanation traces and step-by-step thought processes, Orca gains valuable insights and improves its own capabilities.

Performance Benchmarks

Orca has shown remarkable performance in complex zero-shot reasoning benchmarks. It outperforms traditional state-of-the-art instruction-tuned models like Vicuna-13B by over 100% on benchmarks like Big-Bench Hard (BBH) and over 42% on AGIEval. Additionally, Orca achieves the same scores as ChatGPT on the BBH benchmarks and shows competitive performance on professional and academic exams such as the SAT, LSAT, GRE, and GMAT. This is particularly impressive considering that these are zero-shot settings without chain-of-thought, and Orca still performs competitively while trailing behind GPT-4.

Implications and Future Directions

The development of Orca represents a significant advancement in the field of LLMs. By learning from rich signals and imitating the reasoning process of LFMs, Orca is able to perform complex reasoning tasks with a high degree of accuracy. This has wide-ranging implications, especially in areas where complex reasoning and problem-solving are required.

Moreover, this research indicates that learning from step-by-step AI model explanations is a promising direction for improving model capabilities. This opens up new avenues for research and development in the field of LLMs.

Conclusion

Orca presents a novel approach to training large language models, combining progressive learning and teacher assistance to enhance imitation learning. By leveraging intermediate teacher models and gradually exposing the student model to more complex examples, Orca overcomes the capacity gap and improves its reasoning and explanation generation abilities. The paper's findings contribute to the advancement of imitation learning techniques and have implications for the development of future language models.

For more details on Orca and its research, refer to the introductory article from Microsoft and the accompanying research paper.

More On This Topic

  • 10 Principles of Practical Statistical Reasoning
  • Explainable Visual Reasoning: How MIT Builds Neural Networks that can…
  • Machine Learning Textbook: Stochastic Processes and Simulations
  • Amazon Web Services Webinar: Accelerating clinical trial and biomedical…
  • Visual ChatGPT: Microsoft Combine ChatGPT and VFMs
  • ChatGPT: Everything You Need to Know

A Practical Guide to Transfer Learning using PyTorch

Co-authored with Naresh and Gaurav.

This article will cover the what, why, and how of transfer learning.

  • What is transfer learning
  • Why should you use transfer learning
  • How can you use transfer learning on a real classification task

Specifically, we’ll be covering the following aspects of transfer learning.

  • The motivation behind the idea of transfer learning and its benefits.
  • Develop an intuition for base model selection. (notebook)
  • Discuss different choices and the trade-offs made along the way.
  • Implementation of an image classification task with PyTorch. (notebook)
  • Performance comparison of various base models.
  • Resources to learn more about transfer learning and the current state of the art

Transfer learning is a large and growing field and this article covers just a few of its aspects. However, there are many deep learning online communities which discuss transfer learning. For example, here is a good article on how we can leverage transfer learning to reach higher benchmarks than training models from scratch.

Intended Audience and Prerequisites

  • You’re familiar with basic machine learning (ML) concepts such as defining and training classification models
  • You’re familiar with PyTorch and torchvision

In the next section, we'll formally introduce transfer learning and explain it with examples.

What is transfer learning?

From this page,

“Transfer learning is a machine learning method where a model developed for a task is reused as the starting point for a model on a second task.”

A deep learning model is a network of weights whose values are optimized using a loss function during the training progress. The weights of the network are typically initialized randomly before the start of the training process. In transfer learning, we use a pre-trained model that has been trained on a related task. This gives us a set of initial weights that are likely to perform better than the randomly initialized weights. We optimize the pre-trained weights further for our specific task.

Jeremy Howard (from fast.ai) says.

“Wherever possible, you should aim to start your neural network training with a pre-trained model and fine-tune it. You really don’t want to be starting with random weights, because that means that you’re starting with a model that doesn’t know how to do anything at all! With pretraining, you can use 1000x less data than starting from scratch.”

Below, we’ll see how one can think of the concept of transfer learning as it relates to humans.

Human Analogy for Transfer Learning

  • Model training: After a child is born, it takes them a while to learn to stand, balance, and walk. During this time, they go through the phase of building physical muscles, and their brain learns to understand and internalize the skills to stand, balance and walk. They go through several attempts, some successful and some failures, to reach a stage where they can stand, balance and walk with some consistency. This is similar to training a deep learning model which takes a lot of time (training epochs) to learn a generic task (such as classifying an image as belonging to one of the 1000 ImageNet classes) when it is trained on that task.
  • Transfer learning: A child who has learned to walk finds it far easier to learn related advanced skills such as jumping and running. Transfer Learning is comparable to this aspect of human learning where a pre-trained model that has already learned generic skills is leveraged to efficiently train for other related tasks.

Now that we have built an intuitive understanding of transfer learning and an analogy with human learning, let’s take a look at why one would use transfer learning for ML models.

Why should I use transfer learning?

Many vision AI tasks such as image classification, image segmentation, object localization, or detection differ only in the specific objects they are classifying, segmenting, or detecting. The models trained on these tasks have learned the features of the objects in their training dataset. Hence, they can be easily adapted to related tasks. For example, a model trained to identify the presence of a car in an image could be fine-tuned for identifying a cat or a dog.

The main advantage of transfer learning is the ability to empower you to achieve better accuracy on your tasks. We can break down its advantages as follows:

  • Training efficiency: When you start with a pre-trained model that has already learned the general features of the data, you then only need to fine-tune the model to your specific task, which can be done much more quickly (i.e. using fewer training epochs).
  • Model accuracy: Using transfer learning can give you a significant performance boost compared to training a model from scratch using the same amount of resources. Choosing the right pre-trained model for transfer-learning for your specific task is important though.
  • Training data size: Since a pre-trained model would have already learned to identify many of the features that overlap with your task-specific features, you can train the pre-trained model with less domain-specific data. This is useful if you don’t have as much labeled data for your specific task.

So, how do we go about doing transfer learning in practice? The next section implements transfer learning in PyTorch for a flower classification task.

Transfer Learning with PyTorch

To perform transfer learning with PyTorch, we first need to select a dataset and a pre-trained vision model for image classification. This article focuses on using torch-vision (a domain library used with PyTorch). Let’s understand where to find such pre-trained models and datasets.

Where to find pre-trained vision models for image classification?

There are lots of websites providing high-quality pre-trained image classification models. For example:

  1. Torchvision
  2. PyTorch Image Models

For the purposes of this article, we will use pre-trained models from torchvision. It's worth learning a bit about how these models were trained. Let's explore that question next!

Which datasets are torchvision models pre-trained on?

For vision-related tasks involving images, torchvision models are usually pre-trained on the ImageNet dataset. The most popular ImageNet subset used by researchers and for model pre-training vision models contains about 1.2M images across 1000 classes. ImageNet classification is used as a pre-training task due to:

  1. Its ready availability to the research community
  2. The breadth and variety of images it contains
  3. Its use by various researchers — making it attractive to compare results using a common denominator of Imagenet 1k classification

You can read more about the history of the ImageNet challenge, historical background, and information about the complete dataset on this wikipedia page.

Legality considerations when using pre-trained models

ImageNet is released for non-commercial research purposes only (https://image-net.org/download). Hence, it’s not clear if one can legally use the weights from a model that was pre-trained on ImageNet for commercial purposes. If you plan to do so, please seek legal advice.

Now that we know where we can find the pre-trained models we’ll be using for transfer learning, let’s take a look at where we can procure the dataset we wish to use for our custom classification task.

Dataset: Oxford Flowers 102

We will be using the Flowers 102 dataset to illustrate transfer learning using PyTorch. We will train a model to classify images in the Flowers 102 dataset into one of the 102 categories. This is a multi-class (single-label) categorization problem in which predicted classes are mutually exclusive. We’ll be leveraging Torchvision for this task since it already provides this dataset for us to use.

The Flowers 102 dataset was obtained from the Visual Geometry Group at Oxford. Please see the page for licensing terms for the use of the dataset.

Next, let’s take a look at the high-level steps involved in this process.

How does transfer learning work?

Transfer learning for image classification tasks can be viewed as a sequence of three steps as shown in Figure 1. These steps are as follows:
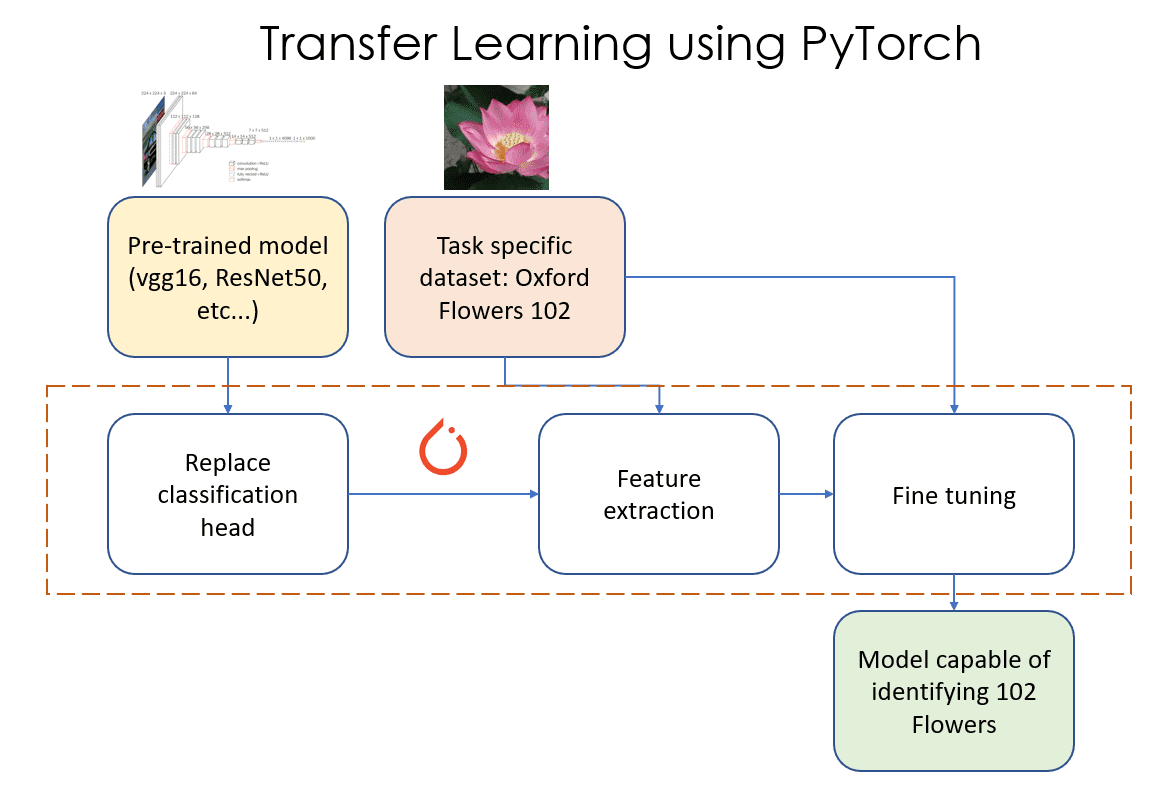
A Practical Guide to Transfer Learning using PyTorch
Figure 1: Transfer Learning using PyTorch. Source: Author(s)

  1. Replace classifier layer: In this phase, we identify and replace the last “classification head” of our pre-trained model with our own “classification head” that has the right number of output features (102 in this example).
  2. Feature extraction: In this phase, we freeze (make those layers non-trainable) all the layers of the model except the newly added classification layer, and train just this newly added layer.
  3. Fine tuning: In this phase, we unfreeze some subset of the layers in the model (unfreezing a layer means making it trainable). In this article, we will unfreeze all the layers of the model and train them as we would train any Machine Learning (ML) PyTorch model.

Each of these phases has a lot of additional detail and nuance that we need to know and worry about. We’ll get into those details soon. For now, let’s deep dive into 2 of the key phases, namely feature extraction, and fine-tuning below.

Feature extraction and fine-tuning

You can find more information about feature extraction and fine-tuning here.

  1. What is the difference between feature extraction and fine-tuning in transfer learning?
  2. Learning without forgetting

The diagrams below illustrate feature extraction and fine tuning visually.
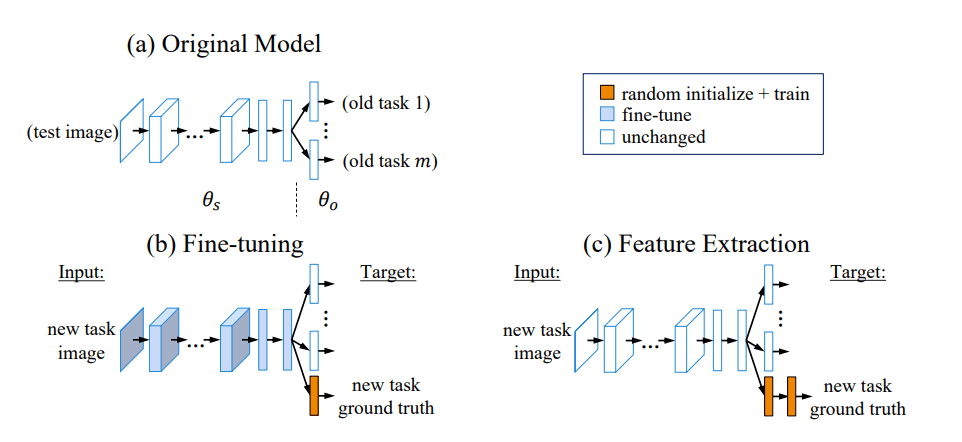
A Practical Guide to Transfer Learning using PyTorch
Figure 2: Visual explanation of fine tuning (b) and feature extraction (c). Source: Learning without forgetting
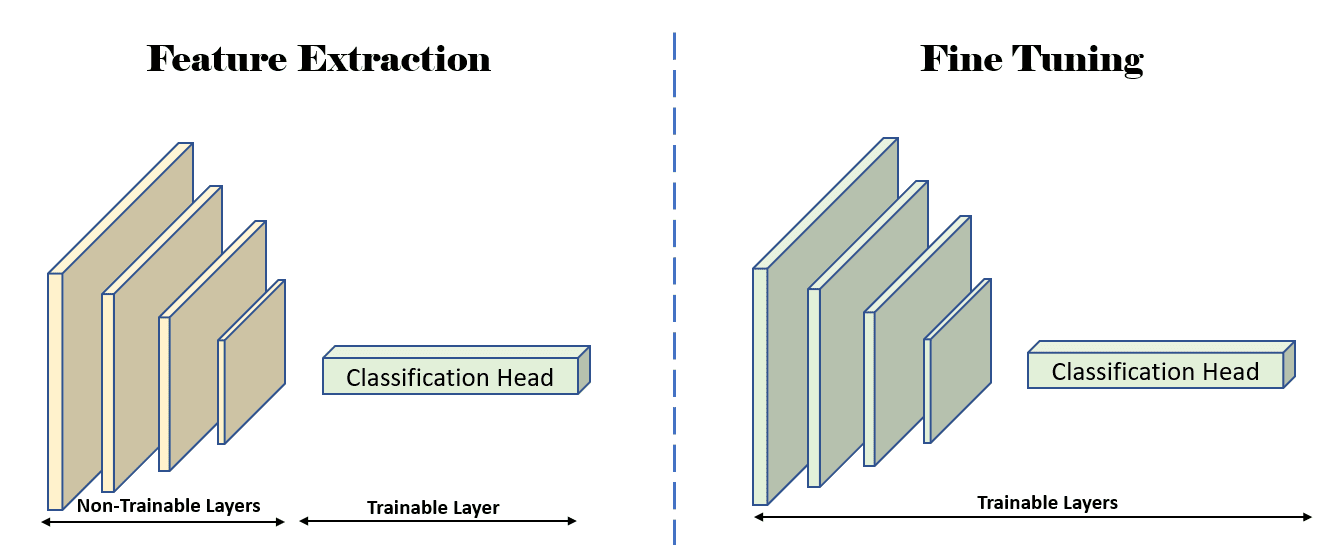
A Practical Guide to Transfer Learning using PyTorch
Figure 3: Illustration showing which layers are trainable (unfrozen) during the feature-extraction, and fine-tuning stages. Source: Author(s)

Now that we’ve developed a good understanding of the custom classification task, the pre-trained model we’ll be using for this task, and how transfer learning works, let’s look at some concrete code that performs transfer learning.

Show me the Code

In this section you will learn concepts like exploratory model analysis, initial model selection, how to define a model, implement transfer learning steps (discussed above), and how to prevent overfitting. We’ll discuss the train/val/test split for this dataset and interpret the results.

The complete code for this experiment can be found here (Flowers102 classification using pre-trained models). The section on exploratory model analysis is in a separate notebook.

Exploratory model analysis

Similar to exploratory data analysis in data science, the first step in transfer-learning is exploratory model analysis. In this step, we explore all the pre-trained models available for image classification tasks, and determine how each one is structured.

In general, it’s hard to know which model will perform best for our task, so it’s not uncommon to try out a few models that seem promising or applicable for our situation. In this hypothetical scenario, let’s assume that model size isn’t important (we don’t want to deploy these models on mobile devices or such edge devices). We’ll first look at the list of available pre-trained classification models in torchvision.

classification_models = torchvision.models.list_models(module=torchvision.models)    print(len(classification_models), "classification models:", classification_models)

Will print

80 classification models: ['alexnet', 'convnext_base', 'convnext_large', 'convnext_small', 'convnext_tiny', 'densenet121', 'densenet161', 'densenet169', 'densenet201', 'efficientnet_b0', 'efficientnet_b1', 'efficientnet_b2', 'efficientnet_b3', 'efficientnet_b4', 'efficientnet_b5', 'efficientnet_b6', 'efficientnet_b7', 'efficientnet_v2_l', 'efficientnet_v2_m', 'efficientnet_v2_s', 'googlenet', 'inception_v3', 'maxvit_t', 'mnasnet0_5', 'mnasnet0_75', 'mnasnet1_0', 'mnasnet1_3', 'mobilenet_v2', 'mobilenet_v3_large', 'mobilenet_v3_small', 'regnet_x_16gf', 'regnet_x_1_6gf', 'regnet_x_32gf', 'regnet_x_3_2gf', 'regnet_x_400mf', 'regnet_x_800mf', 'regnet_x_8gf', 'regnet_y_128gf', 'regnet_y_16gf', 'regnet_y_1_6gf', 'regnet_y_32gf', 'regnet_y_3_2gf', 'regnet_y_400mf', 'regnet_y_800mf', 'regnet_y_8gf', 'resnet101', 'resnet152', 'resnet18', 'resnet34', 'resnet50', 'resnext101_32x8d', 'resnext101_64x4d', 'resnext50_32x4d', 'shufflenet_v2_x0_5', 'shufflenet_v2_x1_0', 'shufflenet_v2_x1_5', 'shufflenet_v2_x2_0', 'squeezenet1_0', 'squeezenet1_1', 'swin_b', 'swin_s', 'swin_t', 'swin_v2_b', 'swin_v2_s', 'swin_v2_t', 'vgg11', 'vgg11_bn', 'vgg13', 'vgg13_bn', 'vgg16', 'vgg16_bn', 'vgg19', 'vgg19_bn', 'vit_b_16', 'vit_b_32', 'vit_h_14', 'vit_l_16', 'vit_l_32', 'wide_resnet101_2', 'wide_resnet50_2']

Wow! That’s a pretty large list of models to choose from! If you’re feeling confused, don’t worry — in the next section, we’ll look at the factors to consider when choosing the initial set of models for performing transfer learning.

Initial model selection

Now that we have a list of 80 candidate models to choose from, we need to narrow it down to a handful of models that we can run experiments on. The choice of the pre-trained model backbone is a hyper-parameter, and we can (and should) explore multiple options by running experiments to see which one works best. Running experiments is costly and time consuming, and it’s unlikely that we’ll be able to try all the models, which is why we try to narrow down the list to 3-4 models to begin with.

We decided to go with the following pre-trained model backbones to begin with.

  1. Vgg16: 135M parameters
  2. ResNet50: 23M parameters
  3. ResNet152: 58M parameters

Here’s how/why we chose these 3 to begin with.

  1. We’re not constrained by model size or inference latency, so we don’t need to find the models that are super efficient. If you want a comparative study of various vision models for mobile devices, please read the paper titled “Comparison and Benchmarking of AI Models and Frameworks on Mobile Devices”.
  2. The models we choose are fairly popular in the vision ML community and tend to be good go-to choices for classification tasks. You could use the citation count for papers on these models as decent proxies for how effective these models could be. However, please be aware of a potential bias where papers on models such as AlexNet that have been around long will have more citations even though one would not use them for any serious classification task as a default choice.
  3. Even within model architectures, there tend to be many flavours or sizes of models. For example, EfficientNet comes in trims named B0 through B7. Please refer to the papers on the specific models for details on what these trims mean.

Citation counts of various papers on pre-trained classification models available in torchvision.

  1. Resnet: 165k
  2. AlexNet: 132k
  3. Vgg16: 102k
  4. MobileNet: 19k
  5. Vision Transformers: 16k
  6. EfficientNet: 12k
  7. ShuffleNet: 6k

If you’d like to read more on factors that may affect your choice of pre-trained model, please read the following articles:

  1. 4 Pre-Trained CNN Models to Use for Computer Vision with Transfer Learning
  2. How to choose the best pre-trained model for your Convolutional Neural Network?
  3. Benchmark Analysis of Representative Deep Neural Network Architectures

Let’s check out the classification heads for these models.

vgg16 = torchvision.models.vgg16_bn(weights=None)

resnet50 = torchvision.models.resnet50(weights=None)

resnet152 = torchvision.models.resnet152(weights=None)

print("vgg16n", vgg16.classifier)

print("resnet50n", resnet50.fc)

print("resnet152n", resnet152.fc)

vgg16

Sequential(

(0): Linear(in_features=25088, out_features=4096, bias=True)

(1): ReLU(inplace=True)

(2): Dropout(p=0.5, inplace=False)

(3): Linear(in_features=4096, out_features=4096, bias=True)

(4): ReLU(inplace=True)

(5): Dropout(p=0.5, inplace=False)

(6): Linear(in_features=4096, out_features=1000, bias=True)

)

resnet50

Linear(in_features=2048, out_features=1000, bias=True)

resnet152

Linear(in_features=2048, out_features=1000, bias=True)

You can find the complete notebook for exploratory model analysis here.

Since we’re going to be running experiments on 3 pre-trained models and performing transfer learning on each one of them separately, let’s define some abstractions and classes that will help us run and track these experiments.

Defining a PyTorch model to wrap pre-trained models

To allow easy exploration, we will define a PyTorch model named Flowers102Classifier, and use that throughout this exercise. We will progressively add functionality to this class till we achieve our final goal. The complete notebook for transfer learning for Flowers 102 classification can be found here.

The sections below will dive deeper into each of the mechanical steps needed to perform transfer learning.

Replacing the old classification head with a new one

The existing classification head for each of these models that is pre-trained on the ImageNet classification task has 1000 output features. Our custom task for flower classification has 102 output features. Hence, we need to replace the final classification head (layer) with a new one that has 102 output features.

The constructor for our class will include code that loads the pre-trained model of interest from torchvision using pre-trained weights, and will replace the classification head with a custom classification head for 102 classes.

def __init__(self, backbone, load_pretrained):      super().__init__()      assert backbone in backbones      self.backbone = backbone      self.pretrained_model = None      self.classifier_layers = []      self.new_layers = []        if backbone == "resnet50":          if load_pretrained:              self.pretrained_model = torchvision.models.resnet50(                  weights=torchvision.models.ResNet50_Weights.IMAGENET1K_V2              )          else:              self.pretrained_model = torchvision.models.resnet50(weights=None)          # end if            self.classifier_layers = [self.pretrained_model.fc]          # Replace the final layer with a classifier for 102 classes for the Flowers 102 dataset.          self.pretrained_model.fc = nn.Linear(              in_features=2048, out_features=102, bias=True          )          self.new_layers = [self.pretrained_model.fc]      elif backbone == "resnet152":          if load_pretrained:              self.pretrained_model = torchvision.models.resnet152(                  weights=torchvision.models.ResNet152_Weights.IMAGENET1K_V2              )          else:              self.pretrained_model = torchvision.models.resnet152(weights=None)          # end if            self.classifier_layers = [self.pretrained_model.fc]          # Replace the final layer with a classifier for 102 classes for the Flowers 102 dataset.          self.pretrained_model.fc = nn.Linear(              in_features=2048, out_features=102, bias=True          )          self.new_layers = [self.pretrained_model.fc]      elif backbone == "vgg16":          if load_pretrained:              self.pretrained_model = torchvision.models.vgg16_bn(                  weights=torchvision.models.VGG16_BN_Weights.IMAGENET1K_V1              )          else:              self.pretrained_model = torchvision.models.vgg16_bn(weights=None)          # end if            self.classifier_layers = [self.pretrained_model.classifier]          # Replace the final layer with a classifier for 102 classes for the Flowers 102 dataset.          self.pretrained_model.classifier[6] = nn.Linear(              in_features=4096, out_features=102, bias=True          )          self.new_layers = [self.pretrained_model.classifier[6]]  

Since we’ll be performing feature-extraction followed by fine-tuning, we’ll save the newly added layers into the self.new_layers list. This will help us set the weights of those layers as trainable or non-tainable depending on what we’re doing.

Now that we have replaced the older classification head with a new classification head that has randomly initialized weights, we will need to train those weights so that the model can perform accurate predictions. This includes feature extraction and fine tuning and we’ll take a look at that next.

Transfer Learning (trainable parameters and learning rates)

Transfer learning involves running feature extraction and fine tuning in that specific order. Let’s take a closer look at why they need to be run in that order and how we can handle trainable parameters for the various transfer learning phases.

Feature Extraction: We set requires_grad to False for weights in all the layers in the model, and set requires_grad to True for only the newly added layers.

We train the new layer(s) for 16 epochs with a learning rate of 1e-3. This ensures that the new layer(s) are able to adjust and adapt their weights to the weights in the feature extractor part of the network. It’s important to freeze the rest of the layers in the network and train only the new layer(s) so that we don’t shock the network into forgetting what it has already learned. If we don’t freeze the earlier layers, they will end up getting re-trained on junk weights that were randomly initialized when we added the new classification head.

Fine Tuning: We set requires_grad to True for weights in all the layers of the model. We train the entire network for 8 epochs. However, we adopt a differential learning rate strategy in this case. We decay the learning rate (LR) so that the LR decreases as we move toward the input layers (away from the output classification head). We decay the learning rate as we move up the model towards the initial layers of the model because those initial layers have learned basic features about the image, which would be common for most vision AI tasks. Hence, the initial layers are trained with a very low LR to avoid disturbing what they have learned. As we move down the model towards the classification head, the model is learning something task specific, so it makes sense to train those later layers with a higher LR. One can adopt different strategies here, and in our case, we use 2 different strategies to illustrate the effectiveness of both of them.

  1. VGG16: For the vgg16 network, we decay the LR linearly from LR=1e-4 to LR=1e-7 (1000x lower than the LR of the classification layer). Since there are 44 layers in the feature extraction phase, each layer is assigned a LR that is (1e-7 — 1e-4)/44 = 2.3e-6 lower than the previous layer.
  2. ResNet: For the ResNet (50/152) network, we decay the LR exponentially starting from LR=1e-4. We reduce the LR by 3x for every layer we move up.
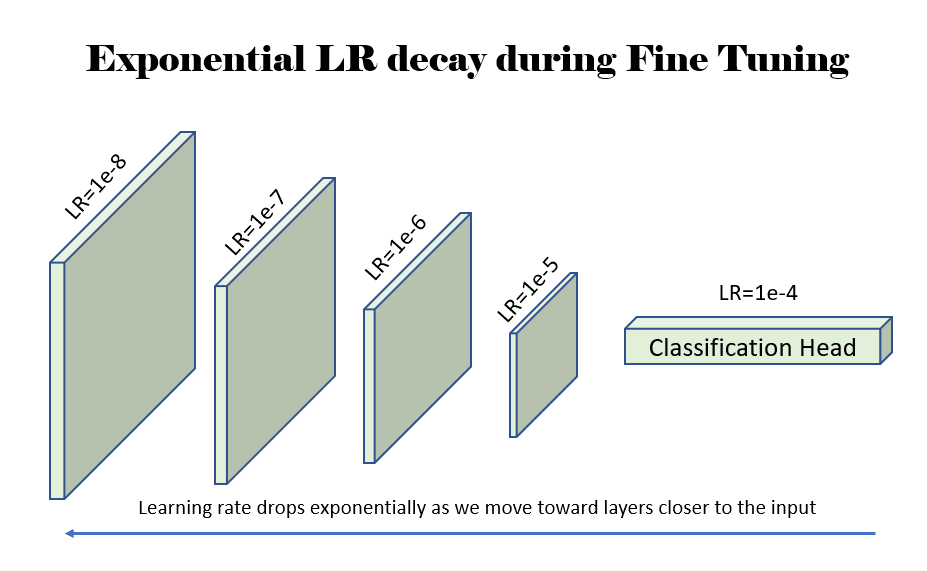
A Practical Guide to Transfer Learning using PyTorch
Figure 4: An example showing the learning rate (LR) decaying exponentially by a factor of 10 as we move up toward the layers closer to the input to the network. Source: Author(s).

The code for freezing layers for both feature extraction as well as fine tuning is shown in the function named fine_tune() below.

def fine_tune(self, what: FineTuneType):      # The requires_grad parameter controls whether this parameter is      # trainable during model training.      m = self.pretrained_model      for p in m.parameters():          p.requires_grad = False      if what is FineTuneType.NEW_LAYERS:          for l in self.new_layers:              for p in l.parameters():                  p.requires_grad = True      elif what is FineTuneType.CLASSIFIER:          for l in self.classifier_layers:              for p in l.parameters():                  p.requires_grad = True      else:          for p in m.parameters():              p.requires_grad = True  

Code snippet: Freezing and unfreezing parameters using requires_grad during the feature-extraction (NEW_LAYERS) and fine-tuning (ALL) phase.

In PyTorch, the way to set differential LRs for each layer is to specify the weights that need that LR to the optimizer that will be used during transfer learning. In our notebook, we use the Adam optimizer. The get_optimizer_params() method below gets the optimizer parameters to pass into the Adam (or other) optimizer we will be using.

def get_optimizer_params(self):      """This method is used only during model fine-tuning when we need to      set a linearly or exponentially decaying learning rate (LR) for the      layers in the model. We exponentially decay the learning rate as we      move away from the last output layer.      """      options = []      if self.backbone == "vgg16":          # For vgg16, we start with a learning rate of 1e-3 for the last layer, and          # decay it to 1e-7 at the first conv layer. The intermediate rates are          # decayed linearly.          lr = 0.0001          options.append(              {                  "params": self.pretrained_model.classifier.parameters(),                  "lr": lr,              }          )          final_lr = lr / 1000.0          diff_lr = final_lr - lr          lr_step = diff_lr / 44.0          for i in range(43, -1, -1):              options.append(                  {                      "params": self.pretrained_model.features[i].parameters(),                      "lr": lr + lr_step * (44 - i),                  }              )          # end for      elif self.backbone in ["resnet50", "resnet152"]:          # For the resnet class of models, we decay the LR exponentially and reduce          # it to a third of the previous value at each step.          layers = ["conv1", "bn1", "layer1", "layer2", "layer3", "layer4", "fc"]          lr = 0.0001          for layer_name in reversed(layers):              options.append(                  {                      "params": getattr(self.pretrained_model, layer_name).parameters(),                      "lr": lr,                  }              )              lr = lr / 3.0          # end for      # end if      return options      # end def  

Code snippet: Differential learning rates for each layer when fine-tuning the model.

Once we have the model parameters with their own LRs, we can pass them into the optimizer with a single line of code. A default LR of 1e-8 is used for parameters whose weights are not specified in the dictionary returned by get_optimizer_params().

optimizer = torch.optim.Adam(fc.get_optimizer_params(), lr=1e-8)

Code snippet: Pass in parameters with their own LRs into the Adam optimizer.

Now that we know how to perform transfer learning, let’s take a look at what other considerations we need to keep in mind before we fine tune our model. This includes steps that we need to take to prevent overfitting, and choosing the right train/val/test split.

Preventing overfitting

In our notebook, we use the following data augmentation techniques on the training data to prevent overfitting and allow the model to learn the features so that it can perform predictions on unseen data.

  1. Color Jitter
  2. Horizontal Flip
  3. Rotation
  4. Shear

There is no data augmentation applied to the validation split.

One should also explore weight decaying, which is a regularization technique to prevent overfitting by reducing the complexity of the model.

Train/Val/Test split

The authors of the Flowers 102 dataset recommend a train/val/test split that’s of size 1020/ 1020/6149. Many authors do things differently. For example,

  1. In the ResNet strikes back paper, the authors use the train+val (2040 images) split as the train set, and the test set as the test set. It isn’t clear if there’s a validation split.
  2. In this article on classification on Flowers 102, the authors use the test split of size 6149 as the train split.
  3. In this notebook, the author uses a train/val/test split of size 6552, 818, and 819 respectively.

The only way to know which author is doing what is to read the papers or the code.

In our notebook (in this article), we use the split of size 6149 as the train split and the split of size 2040 as the validation split. We don’t use a test split, since we aren’t really trying to compete here.

At this point in time, you should feel empowered to visit this notebook that performs all of the steps above and has their results presented for you to view. Please feel free to clone the notebook on Kaggle or Google Colab and run it yourself on a GPU. If you’re using Google Colab, you’ll need to fix up some of the paths where the datasets and pre-trained models are downloaded and where the best weights for the fine-tuned models are stored.

Below, we will look at the results of our transfer learning experiments!

Results

The results have some common themes that we’ll explore below.

  1. After the feature extraction step alone, almost all the networks have an accuracy between 91% and 94%
  2. Almost all networks do really well, achieving an accuracy of 96+% after the fine-tuning step. This shows that the fine tuning step really helps during transfer learning.

There’s a significant difference in the number of parameters in our network, with vgg16 at 135M parameters, ResNet50 at 23M parameters, and ResNet152 at 58M parameters. This suggests that we can probably find a smaller network with comparable accuracy and performance.
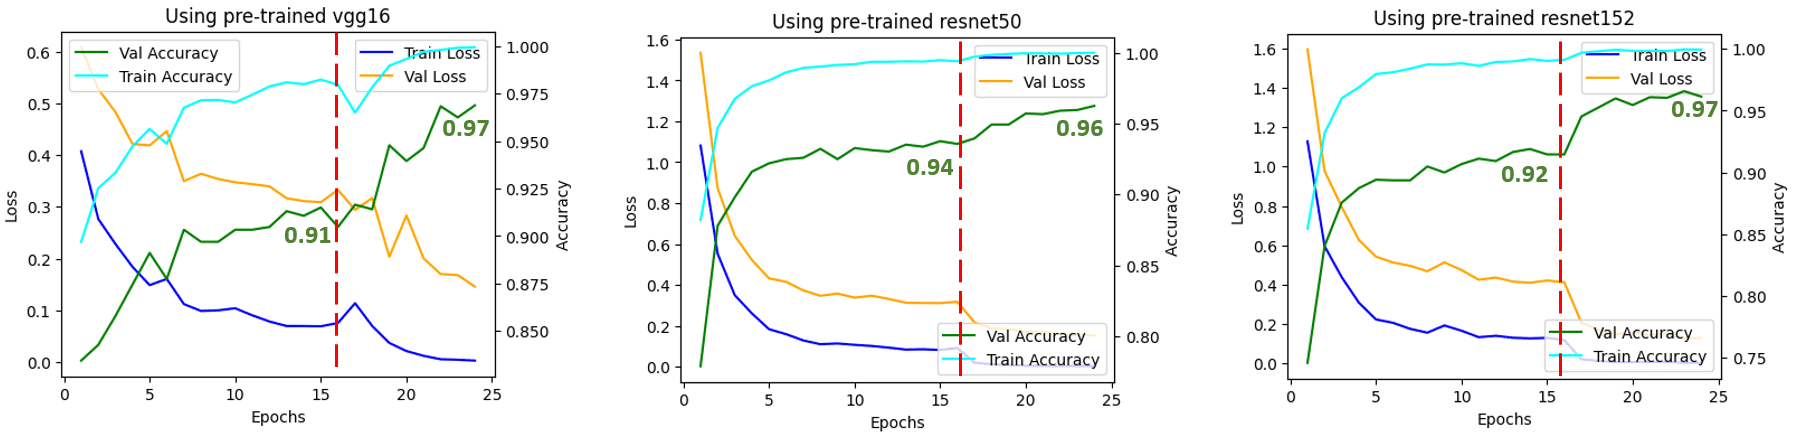
A Practical Guide to Transfer Learning using PyTorch
Figure 5: Train/Val Loss and Accuracy over the transfer learning process. Source: Author(s).

The vertical red line indicates the epoch when we switched from feature extraction (16 epochs) to fine-tuning (8 epochs). You can see that when we switched to fine-tuning, all the networks showed an increase in accuracy. This shows that fine-tuning after feature extraction is very effective.
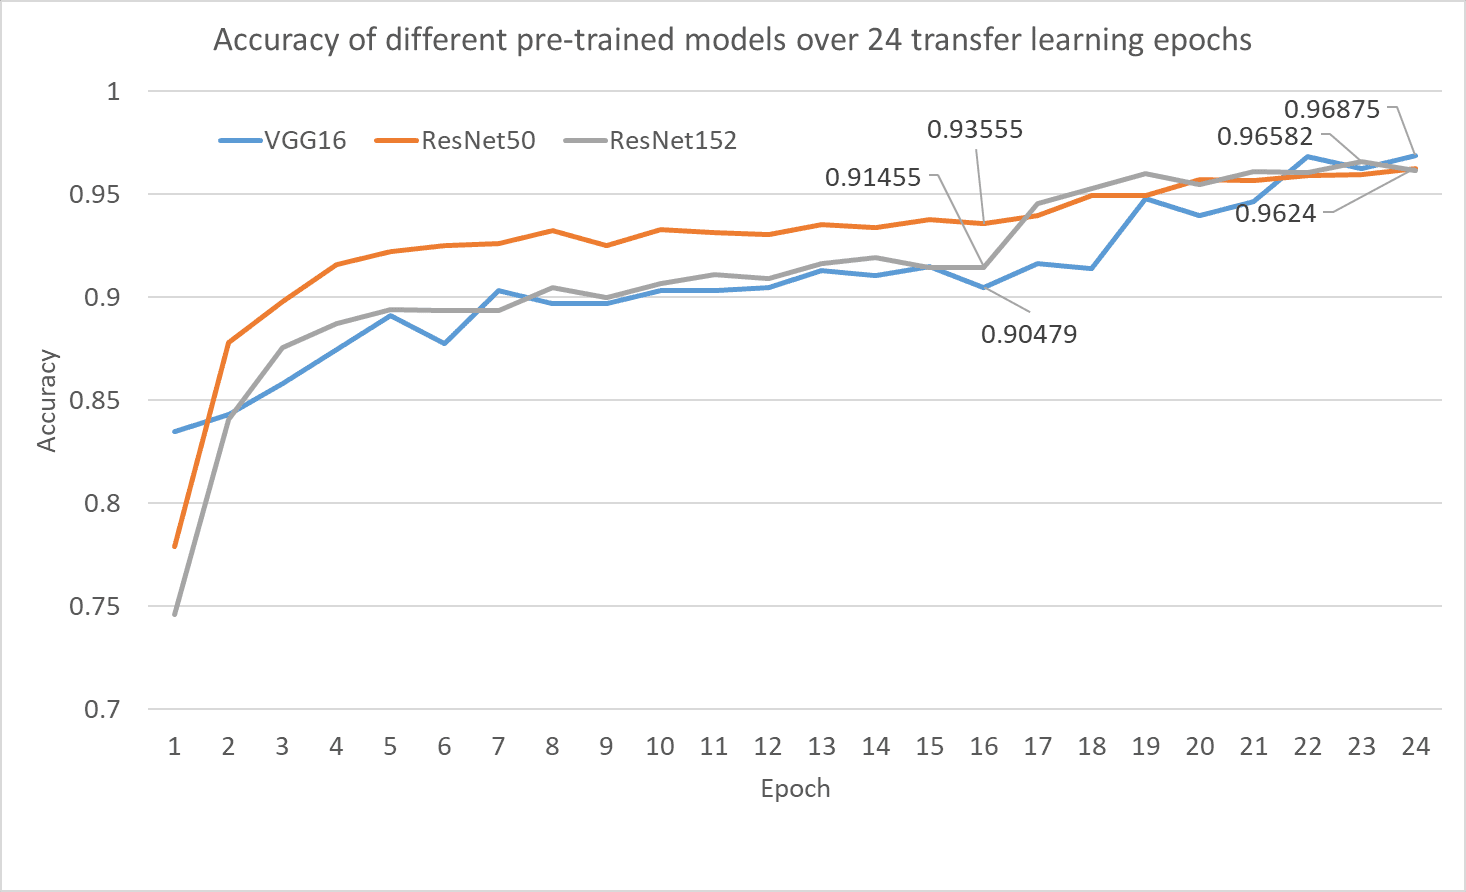
A Practical Guide to Transfer Learning using PyTorch
Figure 6: Validation accuracy of all the 3 pre-trained models after transfer learning on the flowers classification task. The validation accuracy after feature extraction at epoch 16 is shown along with the best validation accuracy for each model during the fine tuning phase. Source: author(s). Article Recap

  1. Transfer learning is a thrifty and effective way to train your network by starting from a pre-trained network on a similar but unrelated task
  2. Torchvision provides many models pre-trained on ImageNet for researchers to use during transfer learning
  3. Be careful when using pre-trained models in production to ensure that you don’t violate any licenses or terms of use for datasets on which models were pre-trained
  4. Transfer learning includes feature extraction and fine-tune, which must be performed in that specific order

Want to learn more?

Now that we know how to perform transfer learning for a custom task starting from a model that is pre-trained on a different dataset, wouldn’t it be great if we could avoid using a separate dataset for the pre-training (pretext task) and use our own dataset for this purpose? Turns out, this is becoming feasible!

Recently, researchers and practitioners have been using self-supervised learning as a way to perform model pre-training (learning the pretext task) which has a benefit of training the model on a dataset with the same distribution as the target dataset that the model is supposed to be consuming in production. If you are interested in learning more about self-supervised pre-training and hierarchical pretraining, please see this paper from 2021 titled self-supervised pretraining improves self-supervised pretraining.

If you own the data for your specific task, you can use self-supervised learning for pre-training your model and not worry about using the ImageNet dataset for the pre-training step, thus staying in the clear as far as use of the ImageNet dataset is concerned.

Glossary of Terms used

  • Classification head: In PyTorch, this is an nn.Linear layer that maps numerous input features to a set of output features
  • Freeze weights: Make the weights non-trainable. In PyTorch, this is done by setting requires_grad=False
  • Unfreeze (or thaw) weights: Make the weights trainable. In PyTorch, this is done by setting requires_grad=True
  • Self-supervised learning: A way to train an ML model so that it can be trained on data without any human generated labels. The labels could be automatically or machine generated though

References and Further Reading

  • Ideas on how to fine-tune a pre-trained model in PyTorch
  • Dive into deep learning: Fine tuning
  • Self-supervised learning and computer vision
  • A Gentle Introduction to Transfer Learning for Deep Learning
  • Notebook: Exploratory model analysis
  • Notebook: Flowers 102 classification using transfer learning

Dhruv Matani is a Machine Learning enthusiast focusing on PyTorch, CNNs, Vision, Speech, and Text AI. He is an expert on on-device AI, model optimization and quantization, ML and Data Infrastructure. Authoring a chapter on Efficient PyTorch in the Efficient Deep Learning Book at https://efficientdlbook.com/. His views are his own, not those of any of his employer(s); past, present, or future.

Naresh is deeply interested in the "learning" aspect of the Neural Network. His work is focussed on neural network architectures and how simple topological changes enhance their learning capabilities. He has held engineering roles at Microsoft, Amazon, and Citrix in his decade-long professional career. He has been involved in the deep learning field for the last 6-7 years. You can find him on medium at https://medium.com/u/1e659a80cffd.

Gaurav is a Staff Software Engineer at Google Research where he leads research projects geared towards optimizing large machine learning models for efficient training and inference on devices ranging from tiny microcontrollers to Tensor Processing Unit (TPU)-based servers. His work has positively impacted over 1 Billion of active users across YouTube, Cloud, Ads, Chrome, etc. He is also an author of an upcoming book with Manning Publication on Efficient Machine Learning. Before Google, Gaurav worked at Facebook for 4.5 years and has contributed significantly to Facebook’s Search system and large-scale distributed databases. He has an M.S. in Computer Science from Stony Brook University.

More On This Topic

  • eBook: A Practical Guide to Using Third-Party Data in the Cloud
  • The Most Complete Guide to PyTorch for Data Scientists
  • What is Transfer Learning?
  • TensorFlow for Computer Vision — Transfer Learning Made Easy
  • Transfer Learning for Image Recognition and Natural Language Processing
  • Practical Deep Learning from fast.ai is Back!

While My AI Gently Weeps – A New Beatles Finale! 

Soon after releasing a text-to-music model based on Transformer architecture, MusicGen, Meta recently introduced Voicebox that synthesises speech across six languages and performs noise removal, content editing, and audio style transfer.

Earlier this year, Google also unveiled MusicLM, a high-fidelity generative model that creates music from text prompts. It outperforms older systems, maintaining audio quality and fidelity. Microsoft entered this space pretty early with Transformer-based Museformer that improves attention mechanisms to efficiently model long sequences and generate music with better structures.

These advancements in music generation have matured to a level now where it has helped iconic British band The Beatles complete its last, unfinished song ‘Now and Then’, bringing John Lennon’s voice back to life.

“So when we came to make what will be the last Beatles’ record, it was a demo that John had [and] we were able to take John’s voice and get it pure through this AI,” said legendary musician Paul McCartney, in an interview with BBC Radio.

The last song by The Beatles is actually a demo given to McCartney by Lennon’s widow Yoko Ono, recorded on a cassette while Lennon played the piano. McCartney previously worked on Lennon’s compositions ‘Free As A Bird’ and ‘Real Love’ using AI. With AI assistance from the ‘Get Back’ documentary, McCartney mixed the song, allowing him to perform with Lennon during his recent tour.

From an early Cavern Club gig (Source: BBC)

How Did They Do It?

Well, this is not the first time that The Beatles have sought AI for music. Apparently, composer and machine learning engineer Emile de la Rey and a team at Wingnut Films, led by the ‘Lord of the Rings’ trilogy maker Peter Jackson, collaborated with machine learning researcher Paris Smaragdis to create a neural network called MAL for the making of the 2021 ‘Get Back’ documentary.

MAL used ML to isolate individual voices and instruments in The Beatles recordings, aiding enhancements and remixes and allowing Paul McCartney to virtually collaborate with John Lennon during a recent tour. Traditional methods of isolating voices and instruments from a mixed recording often result in reduced sound quality or interference from other elements.

However, MAL could identify and extract specific audio elements, recreating them realistically based on trained samples. This breakthrough facilitated the boosting of voices in noisy situations and the creation of surround sound remixes for the film.

Subsequently, the team leveraged the same technology to separate the original master tapes of The Beatles’ 1966 album ‘Revolver’, which producer Geoff Martin used for the album’s 2022 remix.

Although no official comments were received from Wingnut Films and Smaragdis, speculation suggests that similar technology may have been used for the new song, based on McCartney’s remarks. We reached out to Wingnut Films and Paris Smaragdis for more information but have yet to receive any input from them.

AI Music Leaves Everyone in Splits

This is not the first time that AI has made its way into the music industry. But musicians have given mixed responses towards AI-generated music. McCartney said in the interview, “It’s kind of scary but exciting because it’s the future.”

The Beatles’ first ever colour photograph (Source: The Telegraph)

Last month, the AI-generated song ‘Heart on My Sleeve’ went viral for having the voices of Drake and The Weeknd but was soon removed from Spotify, Apple Music, TikTok, and YouTube as Universal Music Group claimed copyright infringement. Although Drake did not react to this song, previously, he took to Instagram to express his displeasure over the AI-generated version of himself rapping to Ice Spice‘s popular track ‘Munch (Feelin’ U)’.

Other AI-generated songs, like ‘Winter’s Cold’ by AI Drake, have faced similar copyright issues. According to a report from Financial Times, Spotify has taken down approximately 7% of songs produced with the AI-generated music platform Boomy from its platform in response to a complaint by Universal Music Group, which accused Boomy of artificially inflating its streaming figures using automated accounts.

Echoing similar views, The Police frontman Gordon Sumner (Sting) warned everyone against AI-generated music calling it a “battle we all have to fight”.

However, on the other hand, we have pop singer and Elon Musk’s ex-girlfriend Grimes embracing it with open arms as long as she gets her royalties. She launched Elf.tech, user-friendly AI software that assists producers and songwriters in making it seem like she is singing their songs. The tool, called GrimesAI-1, has already been used for over 15,000 vocal transformations, resulting in more than 300 complete songs submitted for distribution on streaming platforms.

Final gig together (Source: Far Out Magazine)

“The music industry’s opposition makes it easier to reject things but a rebellious moment can benefit AI’s safety and cultural productivity. Early addressing of unpopular ideas is preferable, even if it involves Grimes,” she told The New York Times.

Additionally, popular DJ and producer David Guetta used AI to include Eminem‘s voice in one of his songs during a live performance, but did not release it commercially. In a BBC interview, Guetta said, “The future of music is in AI”.

Let me introduce you to… Emin-AI-em 👀 pic.twitter.com/48prbMIBtv

— David Guetta (@davidguetta) February 3, 2023

The whole conversation around copyright issues in AI generated music is messy and similar to what happened with the likes of Getty, Shutterstock, Adobe in regard to AI image generation. However, eventually, Getty Images partnered with Bria for ethical AI-powered image editing tools, while Midjourney and Shutterstock collaborated with OpenAI for generative AI tools. And now Adobe is killing it with its partnerships with Google, Nvidia and so on.

Like they say, all good things come to an end. But hardcore fans, having grown up on The Beatles music, are now in a puddle of emotions, slowly realising that the loop is finally going to close. They have to make peace with the fact that there is not going to be another song from these legends to fill the void.

While AI music creation is still emerging, it doesn’t surpass human artistry. As we await breakthroughs that challenge existing norms and hurdles, let’s revel in the timeless The Beatles classic ‘While My Guitar Gently Weeps’.

The post While My AI Gently Weeps – A New Beatles Finale! appeared first on Analytics India Magazine.