Forget Apple Vision Pro – rabbit r1 is 2024’s most exciting launch yet

Forget Apple Vision Pro – rabbit r1 is 2024’s most exciting launch yet

Apple is doing everything it can to make VR happen, but a tiny startup has a better vision of the future

Darrell Etherington @etherington / 9 hours

The year is off to a quick start in terms of new product launches and availability, even leaving aside the usual mid-tier smorgasbord that is CES. Apple just started pre-sales of its Vision Pro mixed reality headset, with shipments beginning in early February; meanwhile Samsung debuted the next generation of the only viable iPhone competitor out there, the Galaxy S-series. Despite these heavyweights trying to front-run the year, however, a startup’s oddball take on what the future of personal tech might look like is the most exciting thing to happen in gadgets in a long, long while.

I’m talking about the rabbit r1, the AI-powered hardware unveiled with a fairly impressive, if low-budget impression of an old-school Apple keynote in a small conference room deep within the rabbit’s warren of a Las Vegas casino during CES. The r1 deserves praise just for its physical design, which is a tidy bit of kit created in partnership with Teenage Engineering, the gadget ‘it’ brand of young millennials and Gen Z everywhere.

Unlike the Apple Vision Pro, which looks like the lavish, over-slick encumbered bit of technology’s past masquerading as technology’s future that it is, the rabbit r1 has a pared down, satisfying economy that I think comes much closer to what future generations want from their tech. On the functionality side, Vision Pro is a an exercise in UI over saturation; the r1 aims to be as close as you can currently get to having no UI at all.

The premise of the rabbit r1, in case you missed it, is that it does most, if not all, of what your smartphone can do, but it uses AI to accomplish all the tasks in response to natural language queries. So that could be playing music, booking airfare, providing directions, hailing a ride, ordering food, translating in real-time and much more.

There are tons of questions remaining regarding how the rabbit r1 will work in real-world situations, and how rabbit’s business model (which so far seems to only involve selling individual units at a flat price of $199 – without any recurring subscription fees) will work. But the rabbit r1 already has the kind of organic hype that would-be competitors like the Humane AI pin wished they’d been able to drum up with their carefully tuned, but massively overblown protracted promo campaign.

On the other hand, we know quite a lot about how Apple Vision Pro works and performs, thanks to a recently-expanded hands-on preview program that engaged the media and influencers to come and try out the headset in demos occurring in the run-up to today’s pre-order day, and everyone seems more than impressed with the device’s performance and visual prowess. Reactions are more mixed on everything from the complexity of setup, to user interface elements like the visual keyboard, to long-term wearability and comfort.

The rabbit r1, like the Humane AI pin and other AI-first devices starting to come to market doubtless have a ton of kinks to work out before they get to a place where they’re overall useful, but generative AI already shares something in common with the last major computing paradigm Apple revolutionized – the mobile phone. Specifically, it’s being used and appreciated everywhere by average consumers. I’ve lost count of how many people tell me they just use ChatGPT daily for their actual work, who have nothing to do with the technology industry. The reverse is also true: No one I know who isn’t someone professionally connected to tech owns or regularly uses a VR headset of any kind.

Apple made the iPhone when people were already in love with cell phones, and were beginning to fall in love with smartphones. Rabbit is introducing the r1 when people are already in love with AI, as the term applies to large language models like ChatGPT. Apple, meanwhile, is introducing the Vision Pro to a world where a decade or so of trying has utterly failed to create any kind of mass uptake of virtual, mixed or augmented reality headset use.

If Apple is right and ‘spatial computing’ becomes the next big platform shift, I suspect I’ll be too old to care that I was wrong by the time it does. But increasingly, I think companies like rabbit are working with a more realistic and viable version of computing’s future than some of the legacy players out there who are trying, and failing, to shot-call the next big thing.

How Single-View 3D Reconstruction Works?

Traditionally, models for single-view object reconstruction built on convolutional neural networks have shown remarkable performance in reconstruction tasks. In recent years, single-view 3D reconstruction has emerged as a popular research topic in the AI community. Irrespective of the specific methodology employed, all single-view 3D reconstruction models share the common approach of incorporating an encoder-decoder network within their framework. This network performs complex reasoning about the 3D structure in the output space.

In this article, we will explore how single-view 3D reconstruction operates in real-time and the current challenges these frameworks face in reconstruction tasks. We will discuss various key components and methods utilized by single-view 3D reconstruction models and explore strategies that could enhance the performance of these frameworks. Additionally, we will analyze the results produced by state-of-the-art frameworks that employ encoder-decoder methods. Let’s dive in.

Single-View 3D Object Reconstruction

Single-view 3D object reconstruction involves generating a 3D model of an object from a single viewpoint, or in simpler terms, from a single image. For instance, inferring the 3D structure of an object, such as a motorcycle from an image, is a complex process. It combines knowledge of the structural arrangement of parts, low-level image cues, and high-level semantic information. This spectrum encompasses two main aspects: reconstruction and recognition. The reconstruction process discerns the 3D structure of the input image using cues like shading, texture, and visual effects. In contrast, the recognition process classifies the input image and retrieves a suitable 3D model from a database.

Current single-view 3D object reconstruction models may vary in architecture, but they are unified by the inclusion of an encoder-decoder structure in their framework. In this structure, the encoder maps the input image to a latent representation, while the decoder makes complex inferences about the 3D structure of the output space. To successfully execute this task, the network must integrate both high-level and low-level information. Additionally, many state-of-the-art encoder-decoder methods rely on recognition for single-view 3D reconstruction tasks, which limits their reconstruction capabilities. Moreover, the performance of modern convolutional neural networks in single-view 3D object reconstruction can be surpassed without explicitly inferring the 3D object structure. However, the dominance of recognition in convolutional networks in single-view object reconstruction tasks is influenced by various experimental procedures, including evaluation protocols and dataset composition. Such factors enable the framework to find a shortcut solution, in this case, image recognition.

Traditionally, Single-view 3D object reconstruction frameworks approach the reconstruction tasks using the shape from shading approach, with texture and defocus serving as exotic views for the reconstruction tasks. Since these techniques use a single depth cue, they are capable of providing reasoning for the visible parts of a surface. Furthermore, a lot of single-view 3D reconstruction frameworks use multiple cues along with structural knowledge for estimating depth from a single monocular image, a combination that allows these frameworks to predict the depth of the visible surfaces. More recent depth estimation frameworks deploy convolutional neural network structures to extract depth in a monocular image.

However, for effective single-view 3D reconstruction, models not only have to reason about the 3D structure of the visible objects in the image, but they also need to hallucinate the invisible parts in the image using certain priors learned from the data. To achieve this, a majority of models currently deploy trained convolutional neural network structures to map 2D images into 3D shapes using direct 3D supervision, whereas a lot of other frameworks deployed a voxel-based representations of 3D shape, and used a latent representation to to generate 3D up-convolutions. Certain frameworks also partition the output space hierarchically to enhance computational and memory efficiency that enables the model to predict higher-resolution 3D shapes. Recent research is focusing on using weaker forms of supervision for single-view 3D shape predictions using convolutional neural networks, either comparing predicted shapes and their ground-truth predictions to train shape regressors or using multiple learning signals to train mean shapes that helps the model predict deformations. Another reason behind the limited advancements in single-view 3D reconstruction is the limited amount of training data available for the task.

Moving along, single view 3D reconstruction is a complex task as it not only interprets visual data geometrically, but also semantically. Although they are not completely different, they do span different spectrums from geometric reconstruction to semantic recognition. Reconstruction tasks per-pixel reasoning of the 3D structure of the object in the image. Reconstruction tasks do not require semantic understanding of the content of the image, and it can be achieved using low-level image cues including texture, color, shading, shadows, perspective, and focus. Recognition on the other hand is an extreme case of using image semantics because recognition tasks use whole objects and amounts to classify the object in the input, and retrieve the corresponding shape from the database. Although recognition tasks can provide robust reasoning about the parts of the object not visible in the images, the semantic solution is feasible only if it can be explained by an object present in the database.

Although recognition and reconstruction tasks might differ from one another significantly, they both tend to ignore valuable information contained in the input image. It is advisable to use both these tasks in unison with one another to obtain the best possible results, and accurate 3D shapes for object reconstruction i.e. for optimal single-view 3D reconstruction tasks, the model should employ structural knowledge, low-level image cues, and high-level understanding of the object.

Single-View 3D Reconstruction : Conventional Setup

To explain the conventional setup and analyze the setup of a single-view 3D reconstruction framework, we will deploy a standard setup for estimating the 3D shape using a single view or image of the object. The dataset used for training purposes is the ShapeNet dataset, and evaluates the performance across 13 classes that allows the model to understand how the number of classes in a dataset determines the shape estimation performance of the model.

A majority of modern convolutional neural networks use a single image to predict high-resolution 3D models, and these frameworks can be categorized on the basis of the representation of their output: depth maps, point clouds, and voxel grids. The model uses OGN or Octree Generating Networks as its representative method that historically has outperformed the voxel grid approach, and/or can cover the dominant output representations. In contrast with existing methods that utilize output representations, the OGN approach allows the model to predict high-resolution shapes, and uses octrees to efficiently represent the occupied space.

Baselines

To evaluate the results, the model deploys two baselines that consider the problem purely as a recognition task. The first baseline is based on clustering whereas the second baseline performs database retrieval.

Clustering

The the clustering baseline, the model uses the K-Means algorithm to cluster or bunch the training shapes in K sub-categories, and runs the algorithm on 32*32*32 voxelizations flattened into a vector. After determining the cluster assignments, the model switches back to working with models with higher resolution. The model then calculates the mean shape within each cluster, and thresholds the mean shapes where the optimal value is calculated by maximizing the average IoU or Intersection over Union over the models. Since the model knows the relation between the 3D shapes and the images within the training data, the model can readily match the image with its corresponding cluster.

Retrieval

The retrieval baseline learns to embed shapes and images in a joint space. The model considers the pairwise similarity of 3D matrix shapes in the training set to construct the embedding space. The model achieves this by using the Multi-Dimensional Scaling with Sammon mapping approach to compress each row in the matrix to a low-dimensional descriptor. Furthermore, to calculate the similarity between two arbitrary shapes, the model employs the light field descriptor. Additionally, the model trains a convolutional neural network to map images to a descriptor to embed the images in the space.

Analysis

Single-view 3D reconstruction models follow different strategies as a result of which they outperform other models in some areas whereas they fall short in others. To compare different frameworks, and evaluate their performance, we have different metrics, one of them being the mean IoU score.

As it can be seen in the above image, despite having different architectures, current state of the art 3D reconstruction models deliver almost similar performance. However, it is interesting to note that despite being a pure recognition method, the retrieval framework outperforms other models in terms of mean and median IoU scores. The Clustering framework delivers solid results outperforming the AtlasNet, the OGN and the Matryoshka frameworks. However, the most unexpected outcome of this analysis remains Oracle NN outperforming all other methods despite employing a perfect retrieval architecture. Although calculating the mean IoU score does help in the comparison, it does not provide a full picture since the variance in results is high irrespective of the model.

Common Evaluation Metrics

Single-View 3D Reconstruction models often employ different evaluation metrics to analyze their performance on a wide range of tasks. Following are some of the commonly used evaluation metrics.

Intersection Over Union

The Mean of Intersection Over Union is a metric commonly used as a quantitative measure to serve as a benchmark for single-view 3D reconstruction models. Although IoU does provide some insight into the model’s performance, it is not considered as the sole metric to evaluate a method since it indicates the quality of the shape predicted by the model only if the values are sufficiently high with a significant discrepancy being observed between the low and mid-range scores for two given shapes.

Chamfer Distance

Chamfer Distance is defined on point clouds, and it has been designed in a way that it can be applied to different 3D representations satisfactorily. However, the Chamfer Distance evaluation metric is highly sensitive to outliers that makes it a problematic measure to evaluate the model’s performance, with the distance of the outlier from the reference shape significantly determining the generation quality.

F-Score

The F-Score is a common evaluation metric actively used by a majority of multi-view 3D reconstruction models. The F-Score metric is defined as the harmonic mean between recall & precision, and it evaluates the distance between the surfaces of the objects explicitly. Precision counts the percentage of reconstructed points lying within a predefined distance to the ground truth, to measure the accuracy of the reconstruction. Recall on the other hand counts the percentage of points on the ground truth lying within a predefined distance to the reconstruction to measure the completeness of the reconstruction. Furthermore, by varying the distance threshold, developers can control the strictness of the F-Score metric.

Per-Class Analysis

The similarity in performance delivered by the above frameworks cannot be a result of methods running on different subset of classes, and the following figure demonstrates the consistent relative performance across different classes with the Oracle NN retrieval baseline achieving the best result of them all, and all methods observing high variance for all classes.

Furthermore, the number of training samples available for a class might lead one to assume it influences the per-class performance. However, as demonstrated in the following figure, the number of training samples available for a class does not influence the per-class performance, and the number of samples in a class and its mean IoU score are not correlated.

Qualitative Analysis

The quantitative results discussed in the section above are backed by qualitative results as shown in the following image.

For a majority of classes, there is no significant difference between the clustering baseline and the predictions made by decoder-based methods. The Clustering approach fails to deliver results when the distance between the sample and the mean cluster shape is high, or in situations when the mean shape itself cannot describe the cluster well enough. On the other hand, frameworks employing decoder-based methods and retrieval architecture deliver the most accurate and appealing results since they are able to include fine details in the generated 3D model.

Single View 3D Reconstruction : Final Thoughts

In this article, we have talked about Single View 3D Object Reconstruction, and talked about how it works, and talked about two baselines: Retrieval and Classification, with the retrieval baseline approach outperforming current state of the art models. Finally, although Single View 3D Object Reconstruction is one of the hottest topics and most researched topics in the AI community, and despite making significant advances in the past few years, Single View 3D Object Reconstruction is far from being perfect with significant roadblocks to overcome in the upcoming years.

Global tech spending expected to keep climbing on AI demand

global-data-gettyimages-1337196402

Companies worldwide are expected to spend 5.3% more on technology this year, fueled by higher investment in software and IT services, including generative artificial intelligence (GenAI). Businesses, though, will remain largely unprepared for the impact of AI.

Global tech spending will climb at a higher 5.3% growth this year compared to 3.5% in 2023, to hit $4.7 trillion, according to research and advisory firm Forrester. The higher expenditure will be driven by demand for software and IT services such as AI, cloud, and security, which collectively will grab 69% of overall tech spend by 2027.

Also: AI is transforming organizations everywhere. How these 6 companies are leading the way

Investments in GenAI software alone are expected to exceed $227 billion by 2030 on a 36% compound annual growth rate, Forrester said.

Apart from robust demand for software and IT services, another key driver of this year's global tech spend is Asia-Pacific, the research firm said.

The region, in fact, will see the highest growth in tech spending at 5.7%, followed by North America at 5.4% and Europe at 5.1%, Forrester said. IT exports by India, one of the world's biggest exporters of technology services, are estimated to hit $194 billion in 2023, while the nation's overall technology and services market will rake in revenue worth $350 billion by 2025.

India is among several Asian markets that will see the highest growth rates in tech spending this year, with the Philippines, Vietnam, Indonesia, and China also joining the club.

In North America, 60% of tech spending will go toward software and IT services in 2027, compared to 53% in 2018. The fastest overall tech spend will come from the financial services and healthcare sectors, according to Forrester.

Also: Finding the path toward success as organizations bring AI into the workplace

It added that the European economy will recover this year at almost double the rate of 2023, and is expected to see tech spend growth between 5.1% and 5.7% between 2024 and 2027. This will be fueled by higher digital maturity among businesses and more advanced cybersecurity adoption, Forrester said.

Enterprise adoption of AI, though, will come with some uncertainty, according to research from Kearney and Egon Zehnder. The consultancy and leadership advisory firms surveyed 100 executives across four countries.

The study revealed that 70% believed their organization will be disrupted by AI over the next five years, but just 21% agree it has the necessary capabilities to deal with the disruption. The technology's rapid growth is a key factor, with 73% citing time, people, and money as limitations in their level of readiness.

Some 51% pointed to their leadership team's lack of understanding in AI as a challenge. In comparison, among those who believed their organization is prepared for AI, 89% pointed to their business leaders' understanding of AI and its capabilities as a contributing factor.

Also: Business success and growth is dependent upon trust, data, and AI

The study noted that 85% saw AI as an opportunity for their company and 95% perceived the technology as an opportunity for their personal roles.

To prepare for AI, 49% said they are investing in infrastructure, while 44% are turning to external partnerships and 39% are hiring experts in the field.

"The prevailing sentiment among leaders when it comes to AI is optimism. The challenge now lies in translating this optimism into tangible action," said Arjun Sethi, Kearney's Asia-Pacific head and chairman.

Artificial Intelligence

Microsoft’s AI-powered reading tutor lets students choose their own adventures — and it’s free

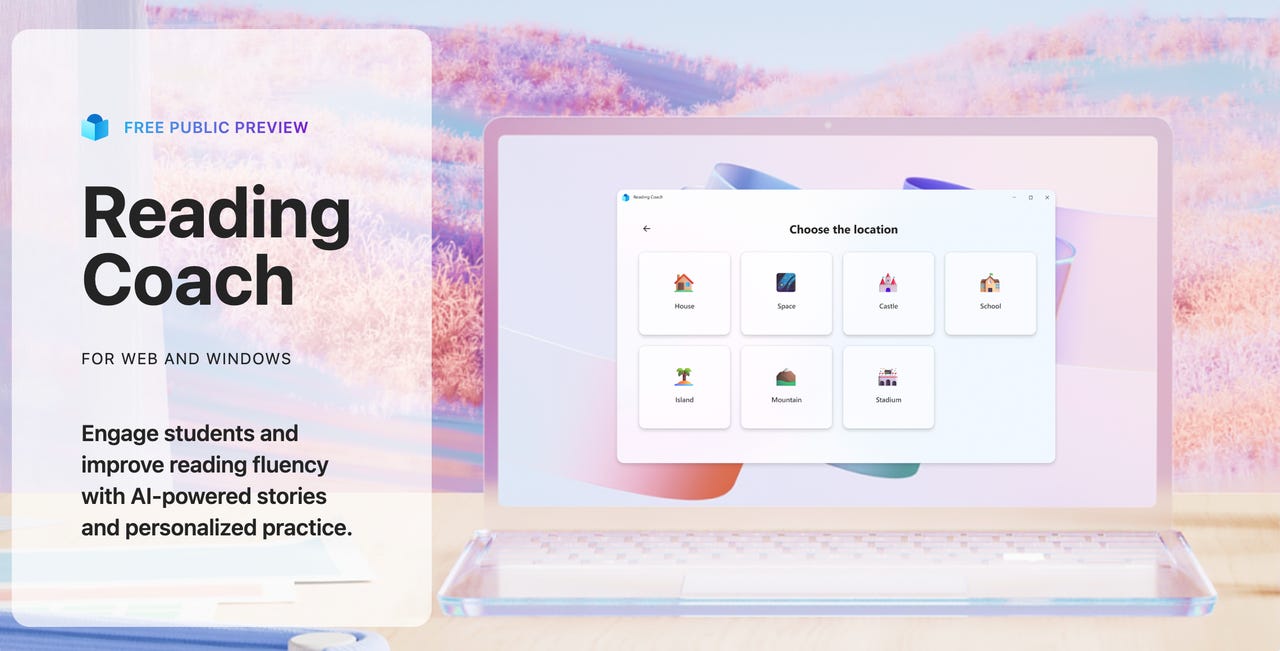
Microsoft Reading Coach

In the new year, Microsoft has been revamping its AI offerings, such as unveiling Copilot Pro, rebranding its AI image generator, and expanding availability. Now, the company is also expanding its AI tools for education.

On Thursday, Microsoft introduced an improved Reading Coach, leveraging generative AI to provide students with new personalized and engaging reading experiences.

Also: Microsoft just renamed Bing Image Creator, and gave Copilot Pro users extra perks

In addition to selecting from one of the prewritten stories, students can now use generative AI to create a story. The student will first pick a protagonist, genre, setting, and reading level to generate a story.

Then, once the story is generated, the user can start reading, and the microphone will pick up their audio for feedback on pronunciation and words to practice. As the students read, they also will be prompted to choose from different narrative paths to alter the story's progression.

Because generative AI is prone to hallucinations, and to keep the platform student-friendly, Microsoft implemented a set of guardrails, moderating the story for quality, safety, and age appropriateness, according to the release.

Also: Have Amazon product questions? Its new AI bot has answers, and poems

Reading Coach gamifies reading, allowing users to unlock new story settings, characters, and badges. Students also can access an achievement page to see their progression and accumulated badges.

If you want to try this AI-powered learning tool, you can preview Reading Coach for free today at coach.microsoft.com. I tried it for myself, and it was fun and interesting to see it in action.

Microsoft also introduced new features to Microsoft Teams for Education and Microsoft Reflect to help educators better serve their students' needs, including using AI to create assignments with rubrics, key content, learning objectives, and more.

Enroll in a Data Science Undergraduate Program For Free

Enroll in a Data Science Undergraduate Program For Free
Image by Author

I'm excited to share with you another degree program that is similar to the Computer Science Degree Program we discussed earlier. This program is offered by the Open Source Society University and is completely free.

The ossu/data-science curriculum is designed for learners who are self-motivated and interested in exploring the world of Data Science at their own pace. The program provides a comprehensive undergraduate curriculum in Data Science by using courses from some of the world's top universities. Best of all, there is no financial burden for learners who enroll in this program.

Enroll in a Data Science Undergraduate Program For Free Curriculum

The program curriculum includes all the necessary and optional courses that you need to master data science and prepare for your professional life. The data science program focuses on theory, mathematics, algorithms, statistics, and data science tools. Here is the complete list of the topics that we will be covering in this program:

  1. Introduction to Data Science: Understanding the basics and scope of Data Science.
  2. Introduction to Computer Science: Essential for beginners; those proficient in any programming language can skip this.
  3. Programming Courses:
    1. Python for Everybody
    2. Introduction to Computer Science and Programming Using Python
    3. Introduction to Computational Thinking and Data Science
  4. Data Structures and Algorithms: Taught in Java (Java Programming, Algorithms, Part I & II).
  5. Databases: From Database Management Essentials to MongoDB for Developers.
  6. Mathematics: Including Single Variable Calculus, Linear Algebra, and Multivariable Calculus.
  7. Statistics & Probability: Courses cover descriptive to inferential statistics.
  8. Data Science Tools & Methods: Tools for Data Science, Data Science Methodology, Data Wrangling.
  9. Machine Learning/Data Mining: Courses range from introductory to specialized topics like Process Mining.

⚠️Disclaimer

This program does not grant an official degree upon completion. It is a self-taught curriculum based on freely available resources, including videos, code examples, and quizzes. Participants do not need to enroll formally; all materials and guidelines are accessible through the designated GitHub repository https://github.com/ossu/data-science. This program is structured to provide an extensive learning experience similar to a Data Science degree; however, it is unofficial and does not grant academic accreditation or recognition from educational institutions.

How to Get Started

1. Duration and Planning

You can complete the program in 2 years if you allocate around 20 hours per week for studies. To help you plan, use this spreadsheet to estimate your end date. Simply input your start date and weekly study hours in the Timeline sheet. You can keep track of your progress by updating the Curriculum Data sheet with the completion date of each course.

2. Order of Classes

You need to understand that some courses can be tackled simultaneously, while others need to be done one after the other. You can view the provided graph to understand the sequence of topics and courses.

Enroll in a Data Science Undergraduate Program For Free
Image from ossu/data-science

3. Tracking Your Progress

Create a Trello account and copy the provided board to your account. You can find instructions on how to do this here. After that, move cards to the 'Doing' or 'Done' columns as you progress through your courses.

4. Choice of Programming Languages

Python, R, and SQL are the primary programming languages used in the data science community. The curriculum covers all three of these languages, but it is important to note that one should focus on understanding core concepts rather than just the language itself. These fundamental concepts need to be thoroughly understood so that they can be applied using any programming tool.

5. Prerequisites

A prerequisite for this course is a basic understanding of math and statistics at the high school level.

Conclusion

Enrolling in a free Data Science undergraduate program is an excellent starting point, but it's important to remember that this is just the beginning. Becoming the highly sought-after 'super data scientist' requires more than just coursework. It demands dedication to expanding your knowledge through specialized topics, actively engaging in projects, and gaining practical experience through internships. You must be willing to build your career step by step, laying a solid foundation with each new skill and experience.

By adhering to this structured and focused program, you are setting yourself on a path toward mastering Data Science. Remember, the journey towards becoming a proficient data scientist is as important as the destination. Embrace and enjoy your learning process as each step brings you closer to achieving your professional goals in this exciting and ever-evolving field.

Abid Ali Awan (@1abidaliawan) is a certified data scientist professional who loves building machine learning models. Currently, he is focusing on content creation and writing technical blogs on machine learning and data science technologies. Abid holds a Master's degree in Technology Management and a bachelor's degree in Telecommunication Engineering. His vision is to build an AI product using a graph neural network for students struggling with mental illness.

More On This Topic

  • Enroll in a 4-year Computer Science Degree Program For Free
  • Don't Miss Out! Enroll in FREE Courses Before 2023 Ends
  • 8 Best Data Science Courses to Enroll in 2022 For Steep Career Advancement
  • Maximize Your Value With The 3rd Best Online Master’s In Data…
  • Advance your Career with the 3rd Best Online Master's in Data…
  • Pursue A Master’s In Data Science With The 3rd Best Online Program

How SAP is Quenching Enterprises’ GenAI Thirst

German ERP solutions giant SAP recently introduced Joule, a generative AI assistant that allows access to the company’s extensive cloud enterprise suite across different apps and programs. It will provide real-time data insights and action recommendations. Going ahead, SAP Joule will serve as the foundation for providing generative AI services.

With a portfolio of over 350 applications ranging from CRM to cash management, the company is actively integrating generative AI into its business applications, focusing on creating AI that is ‘responsible, reliable, and relevant’. Currently, the firm is upgrading its Business Technology Platform (BTP) by adding a generative AI component.

AIM got in touch with Sudeep Singh, vice president and head of CX Business, SAP India, to understand the impact its generative AI services are creating for customers, complying with the growing laws around data privacy in the age of AI and more.

What Makes Joule Special

SAP Joule accommodates two types of models. “The first type involves generic learning at scale, similar to models seen in the market such as OpenAI’s ChatGPT or Google’s Bard. This type of learning is not specific to individuals but rather utilised on a broader scale. The model’s outcomes are then incorporated into processes. Joule does not derive knowledge from the internal processes or data within the SAP system, forming one aspect of the offering,” said Sudeep.

The second component involves a pilot program with selected companies. These companies collaborate with SAP to ensure that the learning process is confined to their specific environments, marking an early stage in this initiative.

“Still in the early stages of exploration, the direction we are heading in involves a focus on avoiding extensive interaction with personal data. Instead, our approach leans towards developing a general model that is conscious and well-informed. This model can streamline processes, enhancing overall efficiency,” he added.

Even though generative AI is still in the pilot phase, customers are using it for different purposes including how sales representatives can summarise complex email chains and give them clear next steps to take, making their communication better and helping them serve customers more effectively.

Beyond customer communication, SAP’s generative AI extends its capabilities to automate CRM processes. Recognising the tedious nature of manual entries stemming from various sources like documents, phone calls, and emails, the algorithms are designed to automate these processes.

These algorithms significantly reduce manual workload by analysing and inputting data into CRM systems, allowing sales representatives to focus more on strategic tasks and customer relationships.

“However, it’s important to note that we are still exploring the full range of business impacts of generative AI. Currently, I believe no organisation in the world has deployed generative AI on a large scale. But AI, in general, has been a part of SAP’s portfolio and is actively used in various applications,” added Sudeep.

“Keeping Data Privacy at the Heart of Our Operations”

Like the EU’s GDPR, the Union government came up with the Digital Personal Data Protection Bill in India in August 2023. In its fourth iteration, the Bill has changed, including an updated definition of ‘processing’ and modifications to the scope of profiling by foreign entities.

However, there have been sufficient arguments that the Bill grants too much power to the government, weakens the Right to Information Act, and raises concerns about state surveillance.

The DPDP Act has crucial implications for SAP and its customers, influencing the management and safeguarding of personal data in India. However, with the burgeoning rise of generative AI models, data privacy has become even more important.

Given that the company serves numerous enterprises through its ERP system, the inflow of organised data to SAP systems is substantial.

“Our approach involves providing limited access, specifically tailored to the organisations to which they subscribe, ensuring that data remains the exclusive property of our customers. We never access or delve into client data, and we certainly do not engage in any practices that involve monetising such information,” said Sudeep.

Building on their 3R mantra of responsible, reliable and relevant AI products and understanding the importance of data protection early on, the tech giant acquired Gigya company specialising in managing online properties and customer identities. Gigya has since then become a cornerstone in SAP’s portfolio, providing a robust solution for customers to ensure compliance with data protection laws.

“Engaging in conversations with our customers has provided valuable insights into their concerns and requirements regarding data privacy. These discussions have been instrumental in shaping our strategies and refining our offerings to meet the evolving needs of organisations operating in an increasingly regulated environment,” he concluded.

Read more: How AI is Navigating SAP’s Intelligent Enterprise

The post How SAP is Quenching Enterprises’ GenAI Thirst appeared first on Analytics India Magazine.

OpenAI signs up its first higher education customer, Arizona State

OpenAI signs up its first higher education customer, Arizona State Kyle Wiggers 8 hours

OpenAI has its first higher education customer: Arizona State University (ASU).

Today, ASU announced that it’s collaborating with OpenAI to bring ChatGPT, OpenAI’s AI-powered chatbot, to the university’s researchers, staff and faculty.

Starting in February, ASU will run an open challenge to invite faculty and staff to submit ideas for ways to use ChatGPT — focusing on student success. new avenues for research and streamlining organizational processes.

“As OpenAI begins to explore how to market or align a business for universities, they’re looking for a design partner, a thought partner, and I think that’s a significant measure of why we’ve come together today to make this announcement,” Lev Gonick, ASU’s chief information officer, told TechCrunch in an email interview. “The collaboration with OpenAI ensures ASU becomes an active participant in defining new uses of gen AI in higher education.”

The OpenAI-ASU deal illustrates the shifting opinions around AI in education as the tech advances faster than curriculums can keep up.

Last summer, schools and colleges rushed to ban ChatGPT over plagiarism and misinformation fears. Since then, some have reversed their bans, while others have begun hosting workshops on generative AI tools and their potential for learning.

ASU — unsurprisingly — is firmly in the camp of AI as a tool for educational good.

“The open call to faculty, staff and researchers ensures that we can provide ongoing and meaningful support that lays the foundations for our teams to harness the true potential of these technologies to augment human learning and creativity, not replace it,” Gonick said. “This approach is part of a strategic plan to pave the way for our students, ensuring that we expand the use of AI in a responsible and scalable manner across the university. We aim to foster an environment where AI resources are utilized effectively and ethically, setting a foundation for the broader integration of these technologies into our academic community.”

Concretely, ASU will provide ChatGPT Enterprise accounts to its full-time employees. Launched in August, ChatGPT Enterprise can perform the same tasks as ChatGPT, such as writing emails, debugging computer code and drafting essays. But it also adds privacy and data analysis capabilities on top of the vanilla ChatGPT, as well as enhanced performance and customization options.

For example, ChatGPT Enterprise offers an admin console with tools to manage how people within an organization use ChatGPT. Shareable conversation templates let users build internal workflows leveraging ChatGPT, while credits for OpenAI’s API platform let organizations create custom ChatGPT-powered solutions.

In addition, ChatGPT Enterprise comes with priority access to ChatGPT and unlimited access to Advanced Data Analysis, a ChatGPT feature that allows users to have the AI analyze data, create charts, solve math problems and more, including from uploaded files.

Gonick says that ASU will play a “dual role” in managing its ChatGPT Enterprise accounts and engaging in efforts pertaining to the AI’s support and “effective use.”

“In this inaugural phase, our focus is on providing faculty, staff, and researchers at ASU with priority access to our AI tools,” he added. “Right now, we’re hyper-focused on putting ChatGPT Enterprise into the hands of our knowledge core … to be at the forefront of discovery and implementation.”

Meet BharatGPT’s GPU Buddy

IIT Bombay is building BharatGPT in collaboration with many universities and institutions. With one of the focus areas being healthcare, it was important for the initiative to bring in expertise from organisations that are leveraging different technologies within the field of healthcare.

AIM got in touch with Vishnu Vardhan, the founder of Vizzhy, a healthcare-focused company that is partnering with the creators of BharatGPT to realise this dream of building generative AI solutions for this field. “We were looking for teams that are building generative AI,” said Vardhan, and that is when he met Ganesh Ramakrishnan, a professor at IIT Bombay who is leading the initiative.

“I met Ganesh at MIT in Boston, and we are one of the first companies that was bringing generative AI to healthcare,” said Vardhan. Vardhan’s team is now working on six research projects with different teams of IIT Bombay.

Along with Vizzhy, Vardhan is also the CEO of Seetha Mahalaxmi Healthcare (SML), which is one of the major providers of GPUs for the BharatGPT initiative. It was one of the first companies to acquire NVIDIA H100 GPUs, and helped the BharatGPT team to train its models, which also includes vision and speech models that the team is planning to come up with.

“We have to depend on English for a lot of things,” explained Vardhan that when it comes to science and healthcare, we are bound to look at it from an English lens, which becomes a huge barrier for research in India as 80% of the people are not proficient in the language. “People look at English just as another language, but they think in their native language.”

Vizzhy has been working on Indic languages for healthcare long before BharatGPT started. That is why Ramakrishnan and Vardhan decided to join hands and build a foundational model with both the expertise.

What sets BharatGPT apart

Tech Mahindra’s Project Indus is also headed in a similar direction as BharatGPT, but Vardhan said that after having several meetings with the Tech Mahindra team they realised that they are currently focused on developing models for several accents of Hindi, and not separate Indic languages. “Project Indus can be used as an add-on for BharatGPT,” he added.

Apart from healthcare, the team also wants to venture into fintech, as he believes this would be able to automate a lot of mundane tasks in the field so that people can focus on better and creative tasks. “Any job that is customer facing can be augmented with generative AI,” he added.

Vardhan highlighted the recent $1.5 billion partnership between Vodafone and Microsoft, as also BharatGPT’s partnership with Reliance Jio, which would power generative AI into the telecom industry. He also said that a lot of small companies and also IT companies would benefit from automation using BharatGPT’s models.

“Generative AI has a huge potential to prevent layoffs,” explained Vardhan. “A lot of the companies experimenting with generative AI do not have enough compute, but at the same time, they also want to adopt the technology. That is where BharatGPT would be able to help them by providing the solutions.”

He said that ChatGPT is super expensive and a lot of technologies are not open source, “We want everyone to use generative AI.” Vardhan added that the initiative would not just be about releasing weights, but making it available to everyone. He highlighted that the first model would be open source and wants developers to help them make it better. “The more people use it, the better it will become,” and eventually, they would release more versions of the model.

Indic LLMs should be built from the ground up

Vardhan emphasised that English models such as Llama and Mistral are good, but cannot address the complexity of Indian languages. Giving an analogy of adding drops into the ocean, Vardhan said that building Indic LLMs with a million tokens on top of English foundational models, which have trillions of token, won’t be enough to make them on par with GPT-4 for other languages such as Kannada or Tamil or Hindi.

He highlighted that Indic languages are very well connected with each other with their grammatical structure, which is very different from English. “That is why we decided that it would be easier to build models if they are originally in any Indic languages such as Hindi,” he explained, as it would be easier to mould them into other languages later.

The only problem he pointed out was that there are not enough available tokens in digital format that can be used to build the model from scratch, like there are in English. “We have lots of books, but they have to be digitised, which is an expensive but important project,” he added.

Similar to Bhashini, Vardhan has also funded another project that is doing OCR of 30,000 books and translating them into digital copies for trainable tokens. “What BharatGPT would come up with would be very authentic and thus powerful,” he added, also highlighting that a lot of people building models using synthetic tokens would not be able to deliver the same quality.

Most of the healthcare data is in English, but when it comes to talking to patients in India, the conversation between the doctor and the patient is mostly in local languages. He said that if most nurses at a hospital spoke Malayalam, it would become a problem for patients to interact with them and added that it is in cases like these that BharatGPT would come in handy.

The post Meet BharatGPT’s GPU Buddy appeared first on Analytics India Magazine.

5 Super Helpful SQL Cheat Sheets You Can’t Miss!

5 Super Helpful SQL Cheat Sheets You Can't Miss!
Image by Freepik

As a data professional, you’ll use SQL all the time. But even if you know SQL, it can be helpful to have a quick reference to look up certain syntaxes and use cases.

Here’s a collection of five super helpful SQL cheat sheets/references covering the following topics:

  • SQL basics
  • Data preparation with SQL
  • SQL joins
  • SQL window functions
  • SQL interview questions

So let's get started!

1. SQL Basics

You can learn SQL basics in a few hours. You only need to familiarize yourself with the syntax and then practice solving a few questions to apply the concepts you just learned. And if you need a refresher on topics like filtering using operators, the join types, group by and aggregate functions, you can refer to the SQL Basics cheat sheet by LearnSQL.

The topics covered include:

  • Querying a single table
  • Filtering the output
  • Querying multiple tables
  • Aggregation and grouping
  • Subqueries
  • Set operations

Link: SQL Basics Cheat Sheet – LearnSQL

2. Data Preparation with SQL

For any data science project, data preparation is super important. The Data Preparation with SQL cheat sheet by Stan Pugsley for KDnuggets will help you go over the key data preparation techniques with SQL.

You can review how to perform the following data prep tasks with SQL:

  • Profile datasets
  • Validate attributes
  • Standardize attributes
  • Create attributes
  • Derive attributes
  • Combine datasets
  • Split datasets

Link: Data Preparation with SQL Cheat Sheet – KDnuggets

3. SQL Joins

Joins in SQL are quite common when you have to use information from multiple database tables to answer the question at hand. But if you are a beginner, joins can seem quite difficult until you’ve practiced enough.

The SQL Joins cheat sheet by DataCamp is a quick reference that covers the following join types:

  • Inner join
  • Self join
  • Left join
  • Full join
  • Cross join

And the following set theory operators in SQL:

  • Union
  • Union all
  • intersect
  • Except

Link: SQL Joins Cheat Sheet – DataCamp

4. SQL Window Functions

If you’ve learned the basics of SQL, you should be comfortable using aggregate functions. Applying aggregate function on a column reduces the set of rows to the specific value such as the average, minimum, and maximum values.

Like aggregate functions, window functions also let you calculate quantities across values in a column, but the result is not reduced to a single value. Rather they return a set of rows. Examples include moving average, running sum, and the like.

Window functions are also extremely important if you’re preparing for interviews. The SQL Window Functions cheat sheet by DataCamp will help you quickly review SQL window functions. It first goes over the following:

  • Syntax of window functions
  • ORDER BY and PARTITION BY clauses
  • Window frame extent

The cheat sheet also covers the following categories of window functions:

  • Ranking window functions
  • Value window functions
  • Aggregate window functions
  • LEAD and LAG

Link: SQL Window Functions Cheat Sheet – DataCamp

5. SQL Interview Questions

Now this is not a cheat sheet but more of a helpful reference for commonly-asked interview questions. It’s meant to be a quick refresher to check your understanding of the foundational concepts.

This SQL Interview Questions collection from Edureka has several questions on the basics of databases such as relationships, schema, constraints, and more. Which you should definitely be familiar with if you have some experience working with relational databases.

In addition, you have some questions on the following topics as well:

  • Normalization
  • OLAP vs. OLTP systems
  • Types of database indexes
  • Query optimization
  • Database triggers
  • Subquery
  • Stored procedures
  • SQL Server and PostgreSQL-specific questions

Link: Top 115 SQL Interview Questions – Edureka

Wrapping Up

Whether you're using SQL at work, learning SQL, or need a quick refresher before your next interview, I'm sure these cheat sheets will help you review what you need.

But to become proficient in SQL, practice is just as necessary as learning. In fact, practice should be a part of the learning process. So if you're looking for good platforms to practice SQL, check out the compilation 7 Best Platforms to Practice SQL.

Bala Priya C is a developer and technical writer from India. She likes working at the intersection of math, programming, data science, and content creation. Her areas of interest and expertise include DevOps, data science, and natural language processing. She enjoys reading, writing, coding, and coffee! Currently, she's working on learning and sharing her knowledge with the developer community by authoring tutorials, how-to guides, opinion pieces, and more.

More On This Topic

  • 7 Super Cheat Sheets You Need To Ace Machine Learning Interview
  • 5 Super Cheat Sheets to Master Data Science
  • 7 Machine Learning Algorithms You Can't Miss
  • If You Can Write Functions, You Can Use Dask
  • Super Bard: The AI That Can Do It All and Better
  • DeepMind’s New Super Model: Perceiver IO is a Transformer that can…

5 Must-Watch AI Conversations from World Economic Forum 2024

AI conversations took center stage at the World Economic Forum for the first time with eminent leaders and industry experts discussing AI policies, regulations, impact on the job market, economy and more. At the event, over 30 talks and sessions revolved around AI, besides discussions on climate change (50), jobs (58), and security and cooperation (64).

Here’s a glimpse of the top conversions that took place at the 54th edition of the World Economic Forum (WEF) held between January 15 and 19, in Davos, Switzerland.

A Conversation with Satya Nadella

Microsoft CEO Satya Nadella captured the attention of many when he spoke about how AI is bringing accelerated change in the world for the better. In conversation with WEF chairperson Klaus Schwab, Nadella elaborated on his vision of generative AI impacting industries and jobs. He also shared insights on how he believes AI will transform the way we approach scientific exploration.

He also touched upon AI improving healthcare, education and products and services sectors. Nadella suggests that AI is capable of turning things around even in case of zero or negative economic growth.

Nadella feels there is a need for global coordination on AI, with an agreement on a set of standards and appropriate guardrails for the technology. “I think a global regulatory approach to AI is very desirable because we’re now at a point where these are global challenges that require global norms and standards,” Nadella said.

The Expanding Universe of Generative Models

Another interesting discussion was the panel on ‘The Expanding Universe of Generative Models’, featuring AI pioneers including Yann LeCun, Nicholas Thompson, Kai-Fu Lee, Daphne Koller, Andrew Ng, and Aidan Gomez discussing the growth of GenAI, future trends, opportunities, and engaging in candid conversations about open-sourcing and equality in AI.

During the roundtable discussion, LeCun advocated for open-source foundational models. “OpenAI does not have a monopoly on good ideas. They’re not going to get to AGI by themselves, in-fact they’re using PyTorch and Transformers, which was published by many of us. They’re profiting from the open research landscape,” said LeCun.

Further, he added, “All of our digital diet will be mediated by AI systems, you do not want this to be under the control of a small number of private companies. So, the basic foundation models will have to be open source. He also laid emphasis on the models built for particular cultures, languages, and values and what role they can play in the ecosystem.

LLM scaling was extensively discussed during the session. Andrew Ng shared his perspective, noting that while scaling gets progressively more challenging, the pace of innovation will continue to feel like it’s accelerating.

“This year we’ll see the image processing revolution, autonomous agents going off and doing work for us, edge AI on our own devices — all these vectors of innovation,” he said. Aiden Gomez, CEO of Cohere, echoed this sentiment, saying, “We’re not done with scaling LLMs, we still need to push up.”

Generative AI: Steam Engine of the Fourth Industrial Revolution?

According to the WEF, generative AI is considered the fourth industrial revolution. In this session, speakers from government and business discussed the implications of generative AI following its rapid emergence in 2023 and how they can manage the risks.

The panel consisted of Senator Mike Rounds from South Dakota, Minister Sultan Alama from the UAE, Julie Sweet (Accenture Chief), Arvind Krishna (chief and chairman of IBM), and Cristiano Amon (president and CEO of Qualcomm).

“Artificial intelligence, in today’s form, is projected to generate $4 trillion of annual productivity before the end of the decade,” said Krishna. Moreover, he believes that generative AI will enhance employee productivity. “We can anticipate a 20-30% to 40% increase in productivity for a programmer who embraces AI, as opposed to one who doesn’t,” he added.

On the other hand, Amon specifically focused on how Qualcomm is working to introduce generative AI capabilities within the car. He explained recent advancements in AI at CES 2024, such as the ability to have a conversation with your car.

Mike Rounds spoke about how AI will be transformational in healthcare, expressing optimism that the US public will appreciate AI after witnessing the improvements in quality of life.

Technology in a Turbulent World

In a key and highly anticipated Davos session, OpenAI CEO Sam Altman joined Marc Benioff, Chair and CEO of Salesforce, Julie Sweet, chair and CEO of Accenture, Jeremy Hunt, UK chancellor of the exchequer and Albert Bourla, CEO of Pfizer, to discuss questions of safety, trust, and human interaction as AI becomes increasingly important in our daily lives.

In this session, Altman addressed the recent case of The New York Times suing OpenAI, presenting his stance and thoughts on the matter.

“We wanted to pay The New York Times a lot of money to display their content. We were as surprised as anybody else to read that they were suing us in The New York Times. That was sort of a strange thing” said Altman.

Gen AI: Boon or Bane for Creativity?

The session extensively focused on the topics of copyright, intellectual property (IP), and the exploration of whether prompts should be copyrighted, along with discussions on distinguishing human-made content from machine-generated content.

The panel featured Neal Mohan, CEO YouTube, Daren Tang, director-general of the World Intellectual Property Organization (WIPO), Almar Latour, CEO and Publisher of the Wall Street Journal at Dow Jones & Company and contemporary Artist Krista Kim.

Latour shared his opinion on the ongoing NYT case and said that WSJ has 138 years of reporting which is high quality data and when that gets scraped and used in a different context, there needs to be compensation for it. “There are very classic models for that, licensing is an age-old business. Applying that forward into the AI era is where our focus is” he said.

“I would prefer to have a commercial solution rather than just going through the courts,” he added.

The post 5 Must-Watch AI Conversations from World Economic Forum 2024 appeared first on Analytics India Magazine.