Cognizant Partners with ServiceNow for Generative AI-Powered Digital Workspace

Cognizant to use Microsoft Azure OpenAI Service for Building Assistant for Employees

Indian IT firm Cognizant has teamed up with SaaS company ServiceNow to enhance the former’s modern workplace services solution with generative AI. The platform is designed to be user-friendly and immersive for enterprise users, aiming to enhance employee self-service, integrate consumer-grade AI technology, and foster efficiency and cost-effectiveness in the work environment.

The partnership addresses the common challenges faced by enterprise employees, such as non-intuitive support solutions and complex processes. Cognizant aims to shift from a transactional experience model to a ‘total experience’ model, emphasising experience engineering, execution, and engagement solutions with ServiceNow’s generative AI offerings. The platform integrates with ServiceNow’s Now Assist and employee endpoint experience technology, offering reduced lead time for deploying and training AI systems.

“With this (NOW Platform), we are enabling enterprises to increase process efficiency, minimise risk by avoiding human mistakes, optimise workforce productivity to focus on higher value tasks​, leverage automated workflows to drive standardisation and empower users to self-solve with augmented intelligence,” Sumeet Mathur, vice president and managing director of ServiceNow’s India Technology and Business Center, told AIM in an earlier conversation.

The key features of the enhanced platform include pre-configured solutions, reusable generative AI configurations, and multi-tool integrations. The platform offers AI-driven conversations for a human-like interaction experience, proactive detection and resolution of service disruptions, contextual knowledge for rapid response, and ease of adoption with swift deployment and simplified integration with existing tools.

The post Cognizant Partners with ServiceNow for Generative AI-Powered Digital Workspace appeared first on Analytics India Magazine.

OpenAI Uses Technique Created By Indian Developers

OpenAI recently released new embedding models and API updates, introducing two additions to its lineup: a smaller and highly efficient text-embedding-3-small model, and a larger and more powerful text-embedding-3-large model.

Interestingly, the technique behind the embedding has been developed by Indian developers Aditya Kusupati, a researcher at Google and Pratik Jain, a Senior Staff Research Scientist at Google who recently published a paper titled ‘Matryoshka Representation Learning.’

🤯WOW🪆Matryoshka Representation Learning enables "native support for shortening embs" &"very flexible usage"
Jokes aside, excited that @OpenAI serves MRL by default in v3 embedding API for retrieval & RAG!
Other models & services should catch-up soon😄https://t.co/JcmTH8w8mh pic.twitter.com/omVe2qkW2t

— Aditya Kusupati 🪆 (@adityakusupati) January 26, 2024

“Wish OpenAI had referred to Matryoshka embeddings (or nested embeddings, as we call them in the paper and presentations) instead of avoiding any of the names we have mentioned in the paper,” expressed Prateek Jain, one of the authors of the paper on X.

Later on, Owen Campbell-Moore, APIs PM at OpenAI, acknowledged that OpenAI did train on MRL. ‘Hey Prateek! We did train this based on MRL – I was responsible for the blog post, and it’s my mistake for not thinking or remembering to cite. We’re updating the blog post to add a citation now!’ Moore wrote on X.”

OpenAI edited the blog post mentioning the contribution of Prateek Jain and Aditya Kusupati’s paper.

🪆Matryoshka Representation Learning (MRL) 🪆
Hidden behind @OpenAI’s new embedding updates* is a cool embedding representation technique by @adityakusupati et al. that encodes information at coarse-to-fine granularities in a single vector. Short 🧵 on how it works.
Different… pic.twitter.com/74nIFEt7Hb

— Jerry Liu (@jerryjliu0) January 26, 2024

What is MRL?

MRL is a cool embedding representation technique that encodes information at coarse-to-fine granularities in a single vector. MRL trains a single high-dimensional vector to encapsulate information at different granularities, akin to nesting dolls. It draws inspiration from the Russian nesting dolls, Matryoshka, where smaller dolls are encased within larger ones.

MRL adapts to various downstream tasks without modifying the original representation, saving computational resources and avoiding the need for separate models for each task.

The post OpenAI Uses Technique Created By Indian Developers appeared first on Analytics India Magazine.

LLM Search Engine Shamelessly Spins Fluff

LLM Search Engine Shamelessly Spins Fluff

Google searching the internet with Bard and giving summarised information is sad. Now, there are startups, such as Perplexity, that are selling their bots with this as the primary offering – making it even more depressing.

Recently, Bard, powered by Gemini Pro, overtook OpenAI’s GPT-4 on the Hugging Face Chat Bot Arena Leaderboard. Interestingly, Gemini Pro is only the second-best model by Google in the Gemini series, which increases expectations from the upcoming Gemini Ultra. Adding to this news, a discussion on X questioned if it was right to benchmark LLMs with search engines against raw LLMs.

LLMs for search, really?

Undoubtedly, the problems with LLMs and their hallucinations is something that has been brought up a thousand times earlier, as it hinders the ability of LLM outputs from being taken seriously and can be a major case for misinformation. Connecting them with the web makes sense to retrieve real-time information while also giving proper attribution to the source of information for credibility.

But, this approach also takes away from the main reason that LLMs were built for. “Perplexity is the classic case of misunderstanding what LLMs are made for,” said Subbarao Khambhampathi, AI professor at Arizona State University while speaking with AIM. “I am against LLMs as search engines,” he explained that these search engines basically search a couple of links and try to summarise them, but originally they did not start like that.

“AI-based search engines are like prompting LLMs to hallucinate till they give the correct answer. But that depends on whether you know what the correct answer is,” Khambhampati laughed that sometimes even after getting the results, it is important to go back and check whether the answer is correct or not, which negates the whole purpose of the summary in the first place.

Khambhampati makes the case that there is very little information that is left out of models such as GPT-4, barring the recent news of yesterday, he says. “It’s still a useful thing [AI search engines], but it is just a RAG on Google Search and you don’t know where the tokens are coming from,” he added, saying that not every page on Google is prioritised the same way as one would expect.

“Essentially, LLM search is searching by imagination, which is a pretty bad way of searching,” Khambhampati said, while acknowledging that though searching reduces hallucinations in LLMs, relying on the information generated by the LLM connected to search might be risky.

To add another caveat, the NYT and OpenAI lawsuit also highlights the problem with retrieving information from the web as the model makers can be sued for diverting traffic from the original website.

Can’t replace Google Search

The problem that several people point out is that LLM search is basically conversational search with just reference to some blue links. “Conversational search actually relies on results from search engines in the first place. It will augment, but NOT REPLACE, old search engines. RAG is a lot of R and a bit of G,” said Yangqing Jia, founder of Lepton.AI, in a post on X.

However, when it comes to Google, it is arguably going through “the innovator’s dilemma”, which means that alternatives to Google Search are increasing, and though the company is trying to push through, it might be moving away from what it actually offers, which is providing accurate responses to questions with reference.

Dare Obasanjo points out on X that web search is great when you want links to the websites, but LLMs are for answering questions. “LLM search doesn’t replace Google Search, it replaces your need to go to Google for answers,” he added, also adding a joke that if your query could be easily answered by an ad, go to Google, which honestly sounds like a pretty good business idea for Google.

At the end of the day, who knows search better than Google? That explains why it is still running its AI features like an experiment, and not a full fledged search product. It even has the potential to kill startups like Perplexity and alike coming up with LLM search engines with the click of a button – by simply adding an LLM search in its browser, which it did recently on Chrome.

The post LLM Search Engine Shamelessly Spins Fluff appeared first on Analytics India Magazine.

Centralising Data Governance through a Data Catalog

Centralising Data Governance through a Data Catalog

Data governance is the linchpin of effective data management, encompassing practices for quality, security, and utility. It establishes order, transparency, and trust, defining roles, implementing standardised processes, and leveraging technology. Essential in today’s data-driven landscape, it safeguards against risks, fosters collaboration, and supports confident, innovative decision-making.

In a recent conversation with Elliot Huebler, manager of data engineering and governance at Tredence, we delved into the intricate world of data governance and how data cataloguing plays a pivotal role in centralising and streamlining these efforts.

“I love governance and cataloguing because it’s the intersection of human and data,” Huebler, who brings a wealth of experience from his background in Galactic Evolution Astrophysics at the University of Michigan, sheds light on the challenges faced by organisations and the innovative solutions Tredence employs to overcome them.

Huebler provides insights into Tredence’s journey, highlighting their evolution from an AI ML solutions firm to a focus on data engineering. With a strong emphasis on data governance, Huebler describes the diverse pillars that constitute effective governance, ranging from data cataloguing to data quality, lineage, master data management, security, privacy policy, and organisational structure.

The Role of Data Catalogues in Governance

As Huebler explains, data cataloguing emerged as one of the first governance programs at Tredence. Recognising the complexity of implementing various niche solutions across different pillars, Tredence identified the need for a centralised approach.

The data catalogue, a tool designed not just for democratising data but also for centralising governance initiatives, became a key player in their strategy. “Data cataloguing, data quality, data lineage, master data management, security, privacy policy are all the pillars of data governance,” he said. “We needed a niche and centralised solution for all of this.”

Acknowledging the diversity of governance needs, Huebler provides an overview of the multitude of tools used by Tredence for different governance pillars. “From data catalogue tools like Alation, Collibra, and Microsoft Purview to enterprise data catalogues like Databricks’ Unity catalogues, the landscape is vast,” he explained. Custom solutions and vendor tools for data quality, security, and master data management also play crucial roles in their approach.

Huebler elaborates on Tredence’s approach to building custom data catalogues. “By starting small and focusing on a specific use case or domain, we create a robust data user journey, incorporating data quality checks, lineage, and other relevant metadata,” he said. This iterative process allows them to demonstrate the holistic value of a customised catalogue, paving the way for further scaling.

Improving Accessibility and Transparency with Data Catalogues

Comparing data catalogues to the Dewey Decimal System in libraries, Huebler emphasises the fundamental role of catalogues in making data easily navigable. “One of the beautiful things about a data catalogue is it. It hardly ever actually looks at data. It’s just looking at metadata,” said Huebler. The metadata-centric approach ensures scalability and adaptability, allowing the catalogue to automatically pick up changes and additions without impacting data quality or security.

For security, Huebler clarifies that while data catalogues focus on metadata, tools or solutions analysing the actual data are necessary for assessing and improving data quality and security. The catalogue can, however, capture and display the results of these assessments, contributing to a comprehensive governance overview.

For scalability, Huebler said that “if new tables were to be added, old tables were to be deleted. It would automatically pick those up, scan them, and then once it’s scanned, you get a page in the catalogue for that asset. And that page in the catalogue has a wide range of different fields which you can fill in about the metadata. And those fields could be the description of the table,” Huebler explained.

Huebler also said that Tredence is experimenting with a lot of generative AI capabilities such as LLMs for making the data catalogue easier, and more interactive. This would drive more adoption across customers.

Challenges and Solutions in Data Catalog Adoption

“One of the most common things we see is that users just don’t engage with the catalogue,” explained Huebler. A common challenge faced by Tredence’s clients is the adoption of data catalogues. Huebler identifies the lack of user engagement as a significant hurdle, attributing it to factors such as bandwidth constraints, absence of executive sponsorship, and a perceived lack of value.

To address this, Tredence employs creative strategies, including curation competitions and gamified approaches, to make the data experience enjoyable and rewarding. “We make a bunch of materials, demos, to really just socialise our initiative across the enterprise. And hopefully we see that that leads to a higher level of stewardship engagement,” Hubler explained.

With a data catalogue you can build a layer of visualisation on top of it. “You can get the user base engagement of the catalogue and a Power BI dashboard, and also the catalogue curation process progress. So, for that user based engagement piece, we want to hold stewards accountable,” he added.

Tredence just spent the last three months onboarding 20 users into the catalogue. “That’s likely because of our webinar session, and also there’s the other monitoring piece which is the catalogue curation progress,” he added. Apart from the user base, Tredence also wants to measure the success of our governance goals, for this the company is working on new methods.

Huebler highlights the importance of executive buy-in for driving adoption and emphasises the need for monitoring tools. Success metrics include user engagement, content growth, and progress towards governance goals. Looking to the future, Huebler envisions data catalogues evolving to take on more governance features and anticipates exciting developments in AI, particularly in the realm of language models, making data interactions more intuitive and user-friendly.

The post Centralising Data Governance through a Data Catalog appeared first on Analytics India Magazine.

Microsoft, ETH Zurich Introduce SliceGPT For Compressing LLMs

Microsoft, ETH Zurich Introduce SliceGPT For Compressing LLMs

Researchers from Microsoft and ETH Zurich have unveiled SliceGPT, a post-training sparsification scheme aimed at addressing the substantial computational and memory costs associated with large language models.

Click here to read the research paper.

The research demonstrates how SliceGPT efficiently reduces the size of language models by eliminating up to 25% of model parameters, including embeddings, while maintaining impressive zero-shot task performance.

The study focuses on three prominent models: LLAMA2-70B, OPT 66B, and Phi-2. For LLAMA2-70B, SliceGPT achieves a remarkable reduction to 64% of the dense model’s total compute for inference on 24GB consumer GPUs.

Similarly, on 40GB A100 GPUs, SliceGPT decreases total compute to 66% for LLAMA2-70B. The research also showcases that SliceGPT requires fewer GPUs to operate, resulting in enhanced speed and efficiency without the need for additional code optimisation.

The key innovation behind SliceGPT lies in its ability to replace each weight matrix with a smaller, dense matrix, effectively reducing the embedding dimension of the network.

The sparsification technique offers a compelling solution to resource constraints associated with large language models, showcasing its potential to pave the way for future advancements in reducing memory and computation demands for pre-trained models.

Microsoft’s SliceGPT not only proves its efficiency in model size reduction but also introduces a new perspective—computational invariance in transformer networks. This insight is expected to inspire and unlock new avenues for further developments in the realm of pre-trained models.

The post Microsoft, ETH Zurich Introduce SliceGPT For Compressing LLMs appeared first on Analytics India Magazine.

Apple, Samsung expose Microsoft’s real AI challenge (Hint: It rhymes with bust)

trust-dial-gettyimages-480798202

We're all wandering through the world searching for something to rely on.

Someone, too.

People and things let us down and so often it's the people who made the things inciting most of the disappointment.

Also: Microsoft accidentally revealed why people don't trust tech companies

So we're touchingly committed when we find people (or things) who somehow keep their promises and deliver.

I'm driven to such depths of consideration because I've just read a treatise on loyalty. Well, less of a treatise and more of a rather large research project that examined the concept of brand loyalty.

Marketing consultancy Brand Keys performs this research every year, to examine which brands inspire emotional commitment from the harrassed and the forlorn and which, well, don't.

The loyal prerogative

This year's version offers some stimulating insights.

Robert Passikoff, Brand Keys founder and president, put it this way: "This year's roster proves meeting or exceeding consumers' expectations allows brands to transmute market-share and loyalty into category and market dominance. Those brands are 'Loyalty Juggernauts' – brands of such overwhelming economic force that their ability to meet expectations makes them far more powerful than universal awareness alone."

It's hard to meet expectations on a regular basis. People are so demanding these days. And, thanks to the glories of social media, everyone is so emotional. Update: People were always so emotional, but these days they have more outlets in which to vent and more choices among competing brands.

Please, then, waft with me among some of the juggernauts, the brands that your parents would want you to marry.

Which brand is the number-one loyalty object among smartphones? Apple. What about headphones? Apple, too. And which brand inspires the deepest fidelity when it comes to laptops? Why, not Apple. It's Samsung.

Also: The best Samsung TVs you can buy

And in tablets it's, oh, Apple again. What about flatscreen TVs? Welcome again, Samsung.

Whither Microsoft and I?

I scanned the list of winners and couldn't find one name: Microsoft.

At first, I couldn't decide whether this struck me as odd or not. Over the last few years, Microsoft has performed relative wonders in changing its image from the slightly contemptible to the surprisingly likable.

Also: 4 Zoom alternatives with better video conferencing privacy policies

Yet when I look at the brand that inspires most consumer loyalty in video chat I see Zoom, not Microsoft Teams. And did I even need to look at the brand that wins hearts in search? I did, but really shouldn't have. It's Google.

Naturally, this made me think about artificial intelligence.

Microsoft has leaped upon AI like a starving tiger leaps upon anything containing flesh. It's taken OpenAI in an almost unseemly loving embrace.

But as the future unfolds — very rapidly — will there exist a concept such as brand loyalty in AI? Will humans choose to trust one company's AI more than another's?

Also: What are Microsoft's different Copilots? Here's what they are and how you can use them

Will, in fact, Microsoft incite the most AI loyalty, much as the likes of Apple and Samsung have come to dominate so many categories in which Microsoft faltered?

The likes of Apple and Samsung did a few things right — right? They created products that lifted spirits. They presented them in ways that appealed to feelings, rather than swamped with features.

Can Microsoft do the same with AI? Can it get people to make an active choice and stick with it?

A tiny element of this question may revolve around whether the company's partnership with Sam Altman and his band of brothers and sisters enhances Bing's market share.

It seems that this may not be the case — yet — though Microsoft isn't enamored with the data proferred.

AI Inside?

But as Samsung touts AI in its latest Galaxy phones and Apple begins to muse about AI in, well — who knows? — will Google's constant search dominance transfer to AI offerings?

Or has, perhaps, Microsoft's almost unseemly aggression in AI made inquiring minds believe that the company isn't merely leading the way, but is already the most trustworthy?

What matters most, perhaps, is whether people will care where their AI comes from. In AI, will any one brand be the equivalent of Intel Inside? I write this as word emerges that most reputable news sites actually block AI scrapers.

Also: How to block OpenAI's AI-training web crawler from ingesting your data

It remains to be seen if this makes a difference to anyone at all — or, indeed, how it might affect the way we consider the world and live our lives.

I can barely wait for the next Brand Keys research that attempts to search for consumer loyalty in AI.

I wonder where it might lie.

Artificial Intelligence

Anthropic Confirms Data Leak Amid FTC Probe

OpenAI-Anthropic Merger No More

Two days after the Federal Trade Commission launched an inquiry into generative AI investments of five leading firms including Anthropic, the AI startup valued at $18 billion has confirmed a data leak.

The year 2024 has proven to be quite eventful as of not for the company founded by ex-OpenAI siblings Dario and Daniela Amodei. Earlier this week on January 22, the company realised that one of their contractors inadvertently shared a file containing customer information with a third party. While the company said the information leaked was “non-sensitive” the file detailed a subset of customer names and open credit balances of 2023.

An Anthropic spokesperson confirmed that the incident was caused due to human error and not related to their in-house AI systems. The affected customers have been notified and provided with the relevant guidance, they told VentureBeat. While they highlighted that the breach had nothing to do with the FTC investigation, they declined to comment on the probe.

Anthropic received $4 billion from Amazon in September 2023 which will be investigated by the FTC. The inquiry by the Commission will detail the specifics of this and similar investments between Alphabet, Microsoft, and OpenAI, seeking information on agreements, strategic rationales, and the practical implications of these partnerships, including decisions on product releases, governance, and oversight rights.

The news of the leak confirmed one of fears of enterprises that have just begun to deploy third-party large language models with their proprietary data, in this instance the LLM being Anthropic’s Claude. The startup founded in 2021 has previously assured its users that it made Claude available “to safety- and societal impacts-minded researchers via a special research access program and has done so in select cases since 2022 – before Claude was commercially available – in line with Anthropic’s public benefit mission.

The post Anthropic Confirms Data Leak Amid FTC Probe appeared first on Analytics India Magazine.

5 Best Courses on Vector Database 

Vector databases form the backbone of generative AI, using embeddings to capture data meaning and assess vector similarities. They are vital in fields like natural language processing, image recognition, recommender systems, and semantic search. With the rising use of LLMs, vector databases offer real-time proprietary data access, facilitating the creation of Retrieval Augmented Generation (RAG) applications.

Given the importance of vector databases, we have curated a set of courses for your learning journey.

Vector Databases: from Embeddings to Applications

Andrew Ng led DeepLearning.AI’s “Vector Databases: from Embeddings to Applications” is a free course on vector databases, their applications, and how they can be used to develop generative AI applications without training or fine-tuning an LLM. The course aims to help learners gain the knowledge to make informed decisions about when to apply vector databases to their applications.

The key topics that will be covered in this course include using vector databases and LLMs to gain deeper insights into data, building labs that demonstrate how to form embeddings using various search techniques to find similar embeddings and exploring algorithms for fast searches through vast datasets and building applications ranging from RAG to multilingual search.

Master Vector Database with Python for AI & LLM Use Cases

In this course by Udemy, you will learn to work with Vector Databases using Python with a focus on AI and LLM applications. The course covers techniques for vector data embedding, indexing, and retrieval, including practical exercises with semantic search and named entity recognition. You will also explore Pinecone vector database, LangChain, and transformer models for vector embedding, along with generative AI and OpenAI API usage.

At Rs 449, the course provides insights into the fundamentals of vector databases and their role in AI workflows, enabling similarity search and nearest neighbor retrieval. This course is suitable for data professionals, AI researchers, machine learning engineers, and anyone with a technical background interested in cutting-edge AI technologies.

A basic understanding of programming concepts and proficiency in at least one language, like Python or Java, is essential. Additionally, a basic understanding of data analysis and machine learning, familiarity with databases, encompassing tables, queries, and data manipulation principles, and knowledge of NumPy and Pandas for data manipulation is advantageous.

Learn Embeddings and Vector Database

The curriculum covers understanding and creating embeddings, using vector databases, and implementing advanced AI solutions. The skills one can learn from this free course include proficiency in AI, online databases, AI development, AIOps (AI for IT Operations), and AI systems. With a flexible schedule and an intermediate level, this subscription-based two-hour course requires no previous experience and is designed for self-paced learning.

The course focuses on embeddings and their role in interpretative processes, covering practical exercises with tools like Supabase. Participants engage in challenges in text pairing, semantic searches, and similarity searches, mastering tasks such as creating conversational responses with OpenAI and handling text chunking. The course combines theoretical understanding with practical skills, ensuring learners not only understand the technical aspects but also develop a proof of concept for an AI chatbot, prepared for real-world challenges.

Master Vector Databases

This course, priced at Rs 449, includes seven hours of on-demand video, five articles, and 12 other resources. The instructor emphasizes practical learning through code-along exercises, providing skills to build and optimize vector indexing systems for real-world applications.

The course explores the fundamentals of vector databases and their applications in AI, generative AI, and language models. Topics covered include vector basics, embedding techniques, SQLite as a Vector Database, ChromaDB, Pinecone DB, Qdrant Vector Database, and applications of Langchain and OpenAI Embeddings.

LangChain & Vector Databases in Production

Gen AI 360, a collaboration between Activeloop, Towards AI, and Intel Disruptor Initiative, provides foundational model certification for generative AI professionals, executives, and enthusiasts. This free certification is a comprehensive three-course series that provides essential skills for mastering LLMs, covering everything from training to implementation in production.

The first course, featuring over 50 lessons and 10 practical projects, focuses on LangChain and introduces Deep Lake, a cutting-edge vector database for AI data. It also covers prompt engineering, knowledge organization with indexes, and building applications such as automated sales agents and recommendation engines. The course is designed for individuals with intermediate Python knowledge, basic understanding of Jupyter Notebooks, and familiarity with GitHub.

Read more: How Redis Finds Moat in the Indian Market

.

The post 5 Best Courses on Vector Database appeared first on Analytics India Magazine.

Can AI do ugly?

Can AI do ugly? Anna Heim 9 hours

W
elcome to the TechCrunch Exchange, a weekly startups-and-markets newsletter. It’s inspired by the daily TechCrunch+ column where it gets its name. Want it in your inbox every Saturday? Sign up here.

This week, some thoughts on AI aesthetics, the challenge of uninsurability, and how to pitch a biotech startup to non-experts. — Anna

Too good to be true

Most tools claiming to detect AI-generated text fail spectacularly, my colleague Kyle Wiggers reported. That’s a paradox. I’m only human, but a lot of the AI-written pitches I receive don’t pass the sniff test yet; their style and wordiness feel off.

Then again, it is probably too early to expect machines to detect a je ne sais quoi, even if we can see it. As fellow TechCrunch writer Ron Miller observed recently, “it’s really like AI-generated art, which has a certain look and feel.”

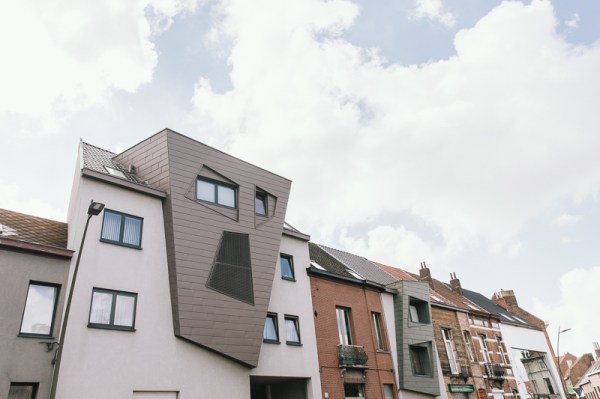
That look and feel was made funnily obvious in a recent experiment conducted on one of my favorite social media accounts, Ugly Belgian Houses.

Equinix Launches Private Cloud Service for NVIDIA AI Supercomputing

Equinix, Inc., a leader in digital infrastructure services, has introduced a fully managed private cloud service for enterprises to acquire and manage their NVIDIA DGX AI supercomputing infrastructure for developing and deploying custom generative AI models. The service, available immediately, integrates NVIDIA DGX systems, NVIDIA networking and the NVIDIA AI Enterprise software platform, providing a solution for enterprises seeking advanced AI capabilities.

The fully managed private cloud service allows Equinix to install and operate each customer’s privately owned NVIDIA infrastructure, with the flexibility to deploy services on their behalf in key International Business Exchange (IBX) data centers across the globe. This strategic move positions Equinix as a key player in the digital infrastructure landscape, offering adaptable and scalable hybrid infrastructure solutions to meet the evolving needs of enterprises.

Charles Meyers, President and CEO of Equinix, emphasized the importance of adaptable and scalable hybrid infrastructure for enterprises looking to harness the potential of generative AI. He stated, “Our new service provides customers a fast and cost-effective way to adopt advanced AI infrastructure that’s operated and managed by experts globally.”

The service caters to the growing demand for generative AI across various industries, including biopharma, financial services, software, automotive, and retail. Early access companies using the service are already establishing AI Centers of Excellence to accelerate innovation in areas such as developing new medications, creating AI copilots for customer service agents, and building virtual productivity assistants.

Jensen Huang, Founder and CEO of NVIDIA, highlighted the transformative impact of generative AI across industries. He said, “Now, enterprises can own NVIDIA AI supercomputing and software, paired with the operational efficiency of Equinix management, in hundreds of data centers worldwide.”

Enterprises using the private cloud service can scale their infrastructure operations to achieve the necessary level of AI performance for developing and running massive models. Equinix’s offering facilitates high-speed private network access to global network service providers, enabling quick generative AI information retrieval across corporate wide area networks. Additionally, it provides private, high-bandwidth interconnections to cloud services and enterprise service providers, meeting data security and compliance requirements.

The service also grants easy access to the NVIDIA AI Enterprise software, streamlining the development and deployment of production-grade AI applications, including generative AI. With pretrained models, optimized frameworks, and accelerated data science software libraries, Equinix’s solution ensures that enterprises can leverage the full potential of NVIDIA’s AI ecosystem.

Furthermore, the cloud service includes enterprise-level support and security, featuring Equinix’s IBX data center professionals to assist customers in rapidly building and deploying custom AI models. Customers also gain access to NVIDIA AI experts, ensuring a robust support system for their AI initiatives.

The post Equinix Launches Private Cloud Service for NVIDIA AI Supercomputing appeared first on Analytics India Magazine.