The nature of work for AI scientists is changing. In some ways, it has made it better. The repetitive, tedious tasks can be automated. Rishi Swami, Head of Data Science at Nirvana Insurance, explained how the transformation of this breed of scientists is taking place at MLDS 2024. Driven by the swift advances in artificial intelligence, he said, “We have seen a lot of innovation in the field of AI, and the pace at which it is coming is immense.”
The acceleration, he noted, is not only introducing efficiencies but is also demanding rapid adaptation from data scientists to stay abreast of emerging technologies.
Rishi emphasised the practical applications of specific AI tools, stating, “We are seeing a huge impact in practical applications of this.” This observation shows the need for data professionals to broaden their skill sets, moving beyond traditional data science roles.
The shift in AI applications, now accessible through open-source APIs and Foundation Models, has dramatically reduced the time and resources needed for AI tasks. This evolution from the traditional data science roles to the new generation AI Engineers can be attributed to the rapid innovation in AI.
This evolution is marked by the evolution of data science techniques over time. Rishi traced this progression from early analytical methods to the complex AI models used today. The engineers are also required to tackle business problems, Rishi pointed out, “As a data scientist you’re asked to look at the data and create value out of it.” This shift from technical roles to more solution-oriented positions reflects the increasing demand for data scientists to integrate their skills with business acumen.
Addressing the future of work, the talk highlighted potential changes due to AI advancements. It emphasised the importance of understanding the entire data science process, from data collection to model application, in this new landscape. He also discussed the use of AI in automating repetitive tasks like data cleaning and the application of AI tools in feature selection for models, indicating a shift in the skill sets required for future job roles.
The post The Evolving Role of Data Scientists appeared first on Analytics India Magazine.
The most recent (and likely final) version of the impending European Union’s AI Act was recently leaked. This is the world’s first comprehensive law designed to regulate the use and application of artificial intelligence, and history shows that, when the EU regulates something, the rest of the world tends to adopt it.
For example, companies doing business in Australia are typically GDPR-compliant, simply because European law requires them to be. The same will likely happen when the EU AI Act comes into power.
Despite the Australian government’s recommendations to be compliant with the EU AI Act, there are no mandatory regulations governing AI use in Australia. That said, Australian businesses will need to start implementing the rules proposed by the EU law if they want to continue scaling and doing business with companies in the EU or even local businesses with EU partnerships.
Australian government advice is to be compliant with the EU
Much as with GDPR, the advice from Australian officials is to be compliant. For example, as noted by the Australian British Chamber of Commerce as guidance to Australian organisations:
“The EU AI Act applies to all businesses that deploy AI systems in the EU market or make them available within the EU, regardless of location. Accordingly, Australian businesses conducting any of the following will have to comply with the legislation:
developing and marketing AI systems;
deploying AI systems; and
using AI systems in their products or services.”
With that in mind, Australian IT pros should watch the EU regulation around AI closely. It is likely to become standardised as best practice even in the absence of local regulation.
The benefit to Australian businesses meeting the requirements of the EU AI regulations is, much as with GDPR, that once they’ve done so, they’re already essentially ready and compliant when the Australian government introduces local regulations.
5 things Australians need to know about the EU AI Act
Currently, Australia does have legislation that covers components of AI, such as data protection, privacy and copyright laws. There is also an Australian AI Ethics Framework, which is voluntary but covers much of what the EU laws aim to legislate.
PREMIUM: Businesses should consider drafting an AI ethics policy.
The eight principles at the heart of the AI Ethics Framework provide Australian organisations with a “best practices” way of thinking about how AI should be created and used, particularly in regards to human safety, benefit and fairness.
The EU approach is essentially taking these philosophical ideas and turning them into specific regulations for organisations to follow. For example, the five key areas that the EU laws will regulate are:
Risk classification system for AI systems: These will range from “minimal” to “unacceptable,” and as the AI application is considered to become “higher” risk, it is subjected to greater levels of regulation.
Obligations for high-risk AI systems: Most of the regulation is focused on commitments related to ensuring data quality, transparency, human oversight and accountability.
Ban on certain uses of AI: Uses of AI that pose an unacceptable risk to human dignity, safety or fundamental rights, including social scoring, subliminal manipulation or indiscriminate surveillance, will be banned.
Notification and labelling system for AI systems: For the sake of transparency and accountability, there will also be a notification and labelling system for AI systems that interact with humans, generate content or categorise biometric data.
Governance structure: This will involve national authorities, a European AI Board and a European AI Office to oversee the implementation and enforcement of the AI Act.
Outside of those “high risk” AI models — and that will be a small percentage localised to specific verticals like defence and law enforcement — most AI models used by consumer-facing businesses will have light regulatory requirements. Furthermore, for the most part, Australian organisations that had embraced the full scope of the ethical guidelines that the Australian government had proposed should find no difficulty in meeting the requirements of the EU laws.
Lack of mandatory regulation may leave Australian data and AI pros unprepared to meet compliance
However, the nature of voluntary obligations and a lack of a cohesive regulatory agenda mean that not all Australian AI has been done with the full scope of the ethical guidelines in mind.
SEE: Australia isn’t the only country that developed a voluntary AI code of conduct.
This could cause challenges later on if the organisation decides it wants to scale and has already embedded AI processes that breach EU regulation into its business. For this reason, forward-thinking organisations will likely default to following the strictest set of guidelines.
Non-compliance will limit Australian businesses locally and globally
Once these EU laws come into force in June, anyone who has baked AI into any of their products and processes is going to need to move quickly to achieve compliance. According to Boston Consulting Group, the requirements for compliance will be staggered, with the highest-risk applications having the shortest deadline. Most organisations will need to be compliant in 6-12 months, however.
Those that aren’t won’t be able to bring their AI models to Europe. Not only will this have a direct impact if they want to do business there, but it also means that partnerships around AI with other organisations that are doing business in Europe become complicated, if not impossible.
This is why it will be particularly important for Australian organisations to ensure the AI models being used are compliant with the EU AI Act — to not potentially shut themselves out of business opportunities locally in Australia.
The standard version of ChatGPT has proven to be a very capable tool with the ability to do tasks such as coding, writing, and explaining complex topics.
Naturally, companies wanted to leverage the technology for their own use cases to optimize their business operations. As a result, OpenAI introduced two options for businesses: ChatGPT Enterprise and ChatGPT Team.
Also: ChatGPT vs ChatGPT Plus: Is it worth the subscription fee?
ChatGPT for Enterprise launched in August 2023, nine months after the initial launch of ChatGPT. The model offered businesses enterprise-grade security and additional features tailored for business use cases.
In January 2024, OpenAI added yet another model for businesses that boasts the same security protocols with additional nuances. To help you decide between the two, we highlighted the differences below.
You should use ChatGPT Enterprise if…
1. Your team has a minimum of 150 people
The biggest difference between both models is that ChatGPT Enterprise is geared towards larger-scale deployment and, as a result, has a minimum seat cap of 150 people. This means that to take advantage of this plan, your company has to be large enough to have at least 150 employees, disqualifying smaller businesses and teams.
However, if your team happens to be on the smaller side, lucky for you. OpenAI recently added the ChatGPT Team plan. With this plan, the minimum is only two users. It is easy to enroll and costs a flat fee of $25 per user per month.
2. You want the best OpenAI has to offer
ChatGPT Enterprise offers access to the most advanced features and models, as well as the greatest model quality. With ChatGPT Team, you can already access advanced features such as GPT-4 with vision, voice input and output, the ability to create and share GPTs, image generation, and browsing.
Also: What does GPT stand for? Understanding GPT 3.5, GPT 4, and more
However, with ChatGPT Enterprise, users also have unlimited access to Advanced Data Analysis, the fastest response rate out of all models, and a context window that is four times bigger. This plan also offers the best customer service that OpenAI has to offer, including priority support, dedicated onboarding, ongoing account management, and customer security review.
3. You need the best administration tools
Since ChatGPT Enterprise is meant for implementation in larger organizations, OpenAI has a series of administration features that ChatGPT Team lacks, including sharing controls, Workspace GPT Controls, and an analytics dashboard. All of these features combined help you better understand and control how your employees are interacting with ChatGPT.
Also: ChatGPT Plus users can now add relevant GPTs to their chats — here's how
In addition, ChatGPT for Enterprise offers two security offerings that ChatGPT does not: SAML SSO and domain verification. From an administration standpoint, those security features give you less to worry about in terms of company safety, and they allow you to further limit risks on the team.
You should use ChatGPT Team if…
1. You want a self-serve package
ChatGPT Team has a simple onboarding process. Instead of contacting a sales team the way you would with ChatGPT Enterprise and getting a custom rate, with ChatGPT Team, all you have to do is select it from the "upgrade plan" tab and checkout.
Also: Most organizations fear AI failure, but those that implement AI do report benefits
The process is nearly the same as upgrading to ChatGPT Plus. Because it is self-serve, the price of $25 per person per month is set.
2. You don't need all of the extra bells and whistles
Even though ChatGPT Team is offered as a service for businesses, if you have a family, club, or any team of people who could benefit from the technology, you could use it for that purpose, too. Having said that, many of those groups won't have a need for all of the extra offerings the Enterprise plan offers, such as unlimited access to OpenAI's most advanced models or priority customer service support. In that case, this plan is the best fit.
Amazon debuts ‘Rufus,’ an AI shopping assistant in its mobile app Sarah Perez @sarahintampa / 9 hours
Amazon announced today the launch of an AI-powered shopping assistant it’s calling Rufus that’s been trained on the e-commerce giant’s product catalog as well as information from around the web. The company says the new tool will launch to a subset of U.S. customers in beta, starting today, before expanding to more users in the weeks ahead. Customers will be able to chat with Rufus inside Amazon’s mobile app to get help with finding products, performing product comparisons, and getting recommendations on what to buy.
The launch of the AI chatbot comes on the heels of other AI-powered additions across Amazon.com aimed at improving the shopping experience for consumers, ranging from tools that help customers find clothes that fit to those that enhance product reviews with summaries of product highlights and customer sentiment, as well as others aimed at advertisers and sellers.
Rufus, meanwhile, is a generative AI experience that’s been trained on the product catalog, customer reviews, community Q&As, and information from around the web, so it can answer customers’ questions related to their shopping needs, whether they’re at the start of their shopping journey, trying to narrow down choices, or when they have more specific questions.
The company tells TechCrunch it built a new, internal LLM specialized for shopping to power this experience and then trained it on its data and “publicly available data from across the web.” It did not say if that data included other publicly available retail websites, however.
For example, Amazon suggests a customer in the market for running shoes could ask Rufus questions like “what to consider when buying a running shoe?”, “what are the differences between trail and road running shoes?,” or “are these durable?”
Customers researching other products could also ask things like “what to consider when buying headphones?,” “what to consider when detailing my car at home?,” “what are clean beauty products?,” “what do I need for cold weather golf?,” and more. Or you can simply tell Rufus something you want to do, like: “I want to start an indoor garden.”
The AI can also help with product comparisons or make recommendations if you ask things like “what are good gifts for Valentine’s Day?” or what are the “best dinosaur toys for a 5-year-old?” After Rufus answers, the customer can continue to browse through more refined results.
In other words, you can chat with the AI assistant much as you do with other consumer-facing AI chatbots like OpenAI’s ChatGPT or Google’s Bard — the latter of which also includes shopping integrations.
Rufus will initially be available in beta to select customers in the U.S. within the Amazon mobile app, where it’s launched by tapping on a new button in the bottom navigation bar. Customers can both type or speak their questions into the AI’s chat dialog box that appears at the bottom of the screen.
When finished, customers can return to the Amazon app by swiping down on their screen to dismiss the chat dialog box back to the bottom of the screen.
Amazon says the beta will help it to improve the product and its generative AI initiatives over time.
“It’s still early days for generative AI, and the technology won’t always get it exactly right,” the company said in a blog post. “We will keep improving our AI models and fine-tune responses to continuously make Rufus more helpful over time. Customers are encouraged to leave feedback by rating their answers with a thumbs up or thumbs down, and they have the option to provide freeform feedback as well,” it read.
The company tells us the chatbot won’t feature advertising at launch, but additional elements will be added to the Rufus experience over time if they add value for customers.
As the bot was not made available for testing, we can’t speak to its efficiency. But it’s worth pointing out that Amazon’s AI chatbot Q for businesses has struggled, producing hallucinations (false information) and revealing confidential data.
Rufus will roll out to other U.S. customers in the “coming weeks.”
When OpenAI, significantly funded by Microsoft, launched public access to ChatGPT in November 2022, it entered into competition with Google, among others, for generative AI leadership. A little more than a year later, Google announced that Gemini, its most advanced AI system to date, would be rolled out starting in December 2023.
OpenAI and Google are iterating rapidly. This article covers the key features and pricing details for OpenAI’s ChatGPT and Google’s Gemini, so you will have the information you need to determine whether Gemini is better than ChatGPT for your business needs.
Gemini vs. ChatGPT: Comparison table
Feature
Gemini
ChatGPT
Notable editions and availability
Gemini Ultra, Announced for 2024 Gemini Pro, Dec. 2023 Gemini Nano, Dec. 2023
GPT-4, March 2023 GPT-3.5, Nov. 2022
Free chatbot access
Google Bard (use to access Gemini Pro)
ChatGPT (access to GPT-3.5)
Paid chatbot access
None (as of early February 2024)
ChatGPT Plus, $20/month (access to GPT-4 with DALL-E, browsing and analysis); ChatGPT Team, $30/month ($25/month, paid annually); ChatGPT Enterprise (contact sales
Both AI systems offer chatbot and API options; the various free and paid alternatives are detailed below.
Gemini chatbot pricing
Free: Try Gemini Pro for free when you use Google Bard in countries where Bard is available. Using Bard requires you to log in with a Google account.
Some Google materials have mentioned a future release of Bard Advanced, but few details have been released.
ChatGPT chatbot pricing
Free: Use ChatGPT with GPT-3.5 for free when you sign up for an OpenAI account.
Paid: ChatGPT Plus, a paid option that costs $20/month, adds access to GPT-4 with browsing and analysis features. It also includes access to DALL-E, which allows you to enter a prompt to generate an image.
Third-party: Several third-party apps rely on ChatGPT or offer it as an option. Often, a limited number of prompts per hour may be made at no charge; in some cases, a paid upgrade offers access to more accurate models and more prompts. Such services include Bing Chat, Microsoft Copilot, Perplexity.ai and Poe.
Google Gemini developer pricing
Free, with limits: Developers may use Google AI Studio to access Gemini Pro for free, with up to 60 requests per minute.
Free now, paid upon general availability: Vertex AI developers may also access Gemini Pro for free, but once Gemini Pro status changes to general availability in 2024, then pricing will be:
$0.00025 per 1,000 characters for input ($0.0025 per image).
$0.0005 per 1,000 characters for output.
No pricing details have been announced for Gemini Ultra.
ChatGPT developer pricing
Paid: Sign up for OpenAI API to access various AI models; pricing for these varies by model and usage. According to OpenAI’s pricing page, “You can think of tokens as pieces of words, where 1,000 tokens is about 750 words.” Three popular models include:
GPT-4 Turbo (AKA gpt-4-1106-preview): $0.01 per 1,000 tokens for input and $0.03 per 1,000 tokens for output.
gpt-4-32k model: $0.06 per 1,000 tokens for input and $0.12 per 1,000 tokens for output.
gpt-3.5-turbo-1106 model: $0.0010 per 1,000 tokens for input and $0.0020 per 1,000 tokens for output.
Feature comparison: Gemini vs. ChatGPT
The best way to get a sense of the basic capabilities of Gemini and ChatGPT is to sign in with an account and experiment with a free system. Engage with Google Bard since Gemini Pro drives that offering, or try OpenAI’s ChatGPT to learn what GPT-3.5 can do.
Chat: Gemini Pro in Google Bard
Google Bard is available in a web browser. As of early 2024, when you use Bard (Figure A) in most countries, the system relies on Gemini Pro.
Figure A
For many people, entering prompts in Google Bard will be the easiest way to access Gemini. Image: Andy Wolber/TechRepublic
Google Bard allows you to prompt with text, code, data or uploaded images; the system can respond with text, code, an image or content obtained by browsing the internet. You may choose to enter a prompt by speaking (select the microphone) or have the system read a response (select the speaker symbol next to a response). Responses may be double-checked by selecting the Google logo to compare content to trusted search data.
Bard with Gemini Pro is designed to be multimodal, meaning the system can accept input in a variety of formats without the need to expressly “switch” to a different mode. For example, you might upload a picture along with a prompt asking the system to describe the picture.
When using Google Bard with a personal (not an organizational) account, you may optionally enable extensions. These extensions allow Bard to access information from Google Flights, Google Hotels, Google Maps, Google Workspace (Gmail, Drive and Docs) or YouTube. For example, this lets you ask the system about information from a YouTube video or Google Drive document.
Chat: OpenAI ChatGPT features
ChatGPT is available on the web and within the ChatGPT app on Android, iPhone or iPad.
ChatGPT Plus with GPT-4 (Figure B) allows you to prompt with text, code, data or uploaded images or documents. The system can respond with text, code, an image or content obtained by browsing the internet. On mobile devices, you may choose to talk to ChatGPT, and the system will similarly read responses aloud. ChatGPT Plus also lets you create images with a text prompt, thanks to the system’s connection to DALL-E.
Figure B
ChatGPT Plus, a paid upgrade, offers access to GPT-4, with web browsing and image creation, among other features. Image: Andy Wolber/TechRepublic
ChatGPT Plus also supports custom instructions, which allow you to enter text to guide ChatGPT toward better responses for your intended use. For example, custom instructions might be different when you want ChatGPT to help with code than when you seek marketing ideas.
Note that the free option, ChatGPT with GPT-3.5, essentially limits you to text prompts and responses, which tend not to be as useful as those provided by GPT-4.
API: Gemini
Google announced on Dec. 13, 2023 that Gemini Pro may be accessed in preview either in Google AI Studio (Figure C), a developer prototyping tool; or Vertex AI, a comprehensive AI platform, or via API. Google has plans to leverage Gemini in other products, such as Duet AI, the Google Workspace paid add-on and in Chrome and Search. Additionally, Duet AI for Developers will transition to Gemini.
Figure C
Google AI Studio lets developers try Gemini Pro for free. Image: Andy Wolber/TechRepublic
API: OpenAI options
OpenAI offers a variety of API model access options, including GPT-4, GPT-4 Turbo and GPT-3.5 (Figure D). (Subscribers to ChatGPT Plus, Teams and Enterprise may switch between GPT-4 and GPT-3.5 in prompts.) In general, GPT-4 options provide higher quality responses than GPT-3.5. Additionally, OpenAI offers image and audio APIs (e.g., DALL-E, TTS and Whisper), among others. All of these are available for use with an OpenAI API account.
Figure D
Developers may select from a variety of AI models from OpenAI. Image: Andy Wolber/TechRepublic
Gemini: Pros and cons
Gemini pros
Available in three sizes: Nano (on-device), Pro and Ultra (most capable).
Google’s most advanced system to date.
Designed to be multimodal.
Free options to experiment in Google Bard and Google AI Studio.
Planned use of Gemini in various Google services and products.
Gemini cons
Of the three Gemini sizes, only Gemini Pro is initially widely available for use.
Compared to ChatGPT, the public and developers are less familiar with Gemini.
Lack of transparency of source data.
Visit Gemini
ChatGPT: Pros and cons
ChatGPT pros
Historically, GPT-4 often ranked strongest in various benchmarks.
ChatGPT and ChatGPT Plus are widely used, so there are many resources and guides available.
API access to several ChatGPT models has been available for some time.
There is a free option to experiment (ChatGPT with GPT-3.5).
ChatGPT cons
OpenAI’s leadership drama in late 2023 may prompt people to seek secondary or alternative solutions.
Lack of transparency of source data.
Visit ChatGPT
What are the key areas that OpenAI and Google are competing in AI?
Fundamentally, OpenAI and Google are vying for AI leadership in three areas.
First, this is a tech race. Since its launch in March 2023, OpenAI’s GPT-4 has consistently outperformed other AI models. Google claims Gemini Ultra, its most capable version, matches or outperforms GPT-4 on select benchmarks. Regardless of technical differences between the systems, this competition benefits customers.
Second, it is a quest for a sustainable business model for AI systems. To date, OpenAI, with Microsoft, has made massive investments, as has Google. OpenAI offers access to a variety of models — GPT-3.5, GPT-4 and GPT-4 Turbo — for different uses, while Google has optimized Gemini for three sizes: Nano, Pro and Ultra. Both organizations seek to balance AI performance, features and cost, since these systems must be economically sustainable at some point.
Third, there’s a competition for mindshare among the public and developers. Public interest in ChatGPT has been rapid and sustained. Financial firm UBS reported that ChatGPT gained more than one million users within a week of launch; Google Trends indicates greater interest in ChatGPT than competitors; and The Economist recognized ChatGPT as its 2023 word of the year.
Developer mindshare, though, may be more malleable. Leadership struggles at OpenAI in late 2023 prompted some developers to rethink their reliance on both ChatGPT as a coding assistant and OpenAI as a single-source AI provider.
SEE: The Complete ChatGPT Artificial Intelligence OpenAI Training Bundle (TechRepublic Academy)
Should your organization use Gemini or ChatGPT?
If you need to implement a widely used AI solution, OpenAI’s ChatGPT and API offerings may be your best choice, since Google made Gemini Pro access available to developers only on December 13, 2023. Longer term, the choice is less obvious.
OpenAI’s leadership struggles in late 2023 prompted at least some developers to explore a wider range of AI alternatives, including options from OpenAI’s close partner, Microsoft. Google has an excellent track record of research achievements in AI, and the company seems to have a sense of urgency to deliver solid AI solutions.
A prudent practice for leaders in most enterprise environments will be to monitor and experiment with both options, as OpenAI and Google strive to build useful and sustainable AI platforms.
Methodology
This December 2023 comparison relied on public information from each vendor and experimentation, specifically with ChatGPT (GPT-3.5 and GPT-4) and Bard. Both companies make regular updates, so look to Google or OpenAI to learn about the latest features.
A few hours after Google’s Gemini took the Center stage at MLDS 2024, the tech giant announced the release of Gemini Pro globally. Gemini Pro in Bard will be available in over 40+ languages and 230+ countries. The double-check feature on Bard that is currently being used by millions in English, will expand to 40+ languages.
The upgraded Bard will also allow text-to-image generation that will be powered by the latest Imagen-2 model which is said to be better than OpenAI’s Dall.E2. Continuing on its AI responsible bit, to maintain a clear differentiation between visuals generated with Bard and authentic human-created artwork, Bard utilizes SynthID to incorporate digitally recognizable watermarks into the pixels of the generated images.
OpenAI Slowly Losing Out?
OpenAI’s integration of GPTs in ChatGPT Pro directly, can be considered similar to Gemini’s integration on Bard. However, Google seems to be sorted with a number of other releases.
The announcements come at a time when Google seems to be steadily cruising past OpenAI. Recently, Google’s Bard clinched the second position on the HuggingFace Chat Bot Arena Leaderboard, surpassing OpenAI’s GPT-4.
With the latest Gemini Pro’s global rollout, the race between the two tech giants have gained steam. Google has been on a roll with a number of generative AI feature releases, with the latest being enhancements on Google Chrome. With the new ‘Help me Write’ feature, users can prompt Google’s AI to assist with writing requirements, thus, perhaps making ChatGPT slowly redundant.
Interestingly, Gemini capabilities have also been integrated onto hardware devices. Last month, Samsung’s new Galaxy AI smartphones were announced with Gemini capabilities. Furthermore, Google also released Lumiere, their text-to-video generation model- something OpenAI has not yet cracked.
With a lot of catching up left to do, OpenAI’s next big bet would probably be the release of GPT-5. If not, it won’t be long before Google emerges as the winner in the generative AI race too!
The post Google’s Gemini Pro Global Rollout on Bard Set to Surpass GPT-4 Soon appeared first on Analytics India Magazine.
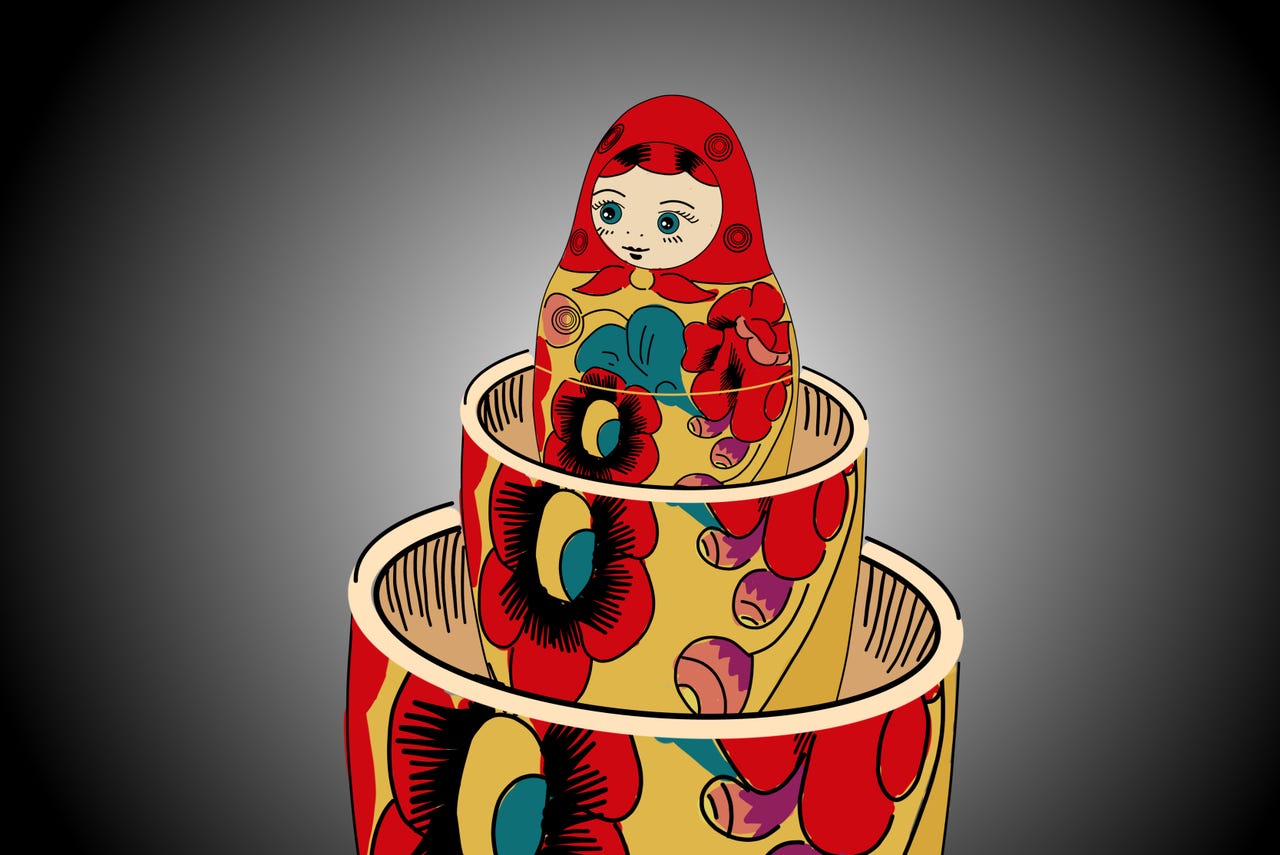
The famous "matryoshka" dolls, where every doll has another doll nested inside of it, and another and another, is a classic example of the principle of recursion, where the thing contains itself. People instantly recognize such examples of recursion, but generative artificial intelligence has no concept of it.
Among the sublime concepts that humans grasp intuitively is the concept of recursion, where something contains a kind of repetition of itself stretching out to infinity. Any "movie within a movie" could be an example of recursion. The famous Matryoshka "nesting dolls" from Russia, where each wooden doll opens to reveal a smaller doll, is an endearing example of recursion.
A picture of yourself holding a picture of yourself in which you are holding a picture of yourself, ad infinitum, is a classic recursive visual fantasy that creates delight in anyone.
But artificial intelligence programs, including generative AI programs such as ChatGPT, cannot deal with recursion, at least, not consistently, according to scholars at the University of Illinois Urbana-Champaign. The inability to handle recursion hampers AI's performance in tasks. In particular, AI can fail in programming tasks where some bit of code repeats a smaller, atomic version of the same code.
"For example, models trained for programming tasks may misunderstand programs with nested blocks or produce imbalanced brackets," according to lead author Shizhuo Dylan Zhang of U of Illinois and colleagues in the paper, "Transformer-Based Models Are Not Yet Perfect At Learning to Emulate Structural Recursion," posted on the arXiv pre-print server this month.
To examine how Gen AI gets stuck by recursion, the authors devised a simple test for large language models (LLMs). Given a piece of code — such as adding numbers recursively — can an LLM produce a description of the pattern of recursion in the code?
Zhang and team choose a classic programming task, called a tree traversal. A data type in computing is called a tree type if it has branching parts that lead to further branches — kind of tree that contains more trees. To "traverse" the tree means to inspect each part of the tree in a certain order.
Also: OpenAI unveils a 'less lazy' GPT-4 Turbo, price drops, plus new and updated models
Into the language model — in this case, GPT-3.5 "Turbo" and GPT-4 (OpenAI's most powerful models) — they enter a prompt that has the problem statement and an example of the tree traversal and an instruction to perform tree traversal. The output from the GPTs should be the solution to the tree traversal and also an explanation of the rule used to perform that traversal.
What they find is the programs start to fail in solving the traversal as the tree gets bigger, or — in computing terms — has greater depth. "The performance of large language models exhibits a significant decline as the tree depth increases, correlating with a rise in the complexity and number of reduction steps required," they write.
A qualitative analysis, they write, reveals that the language models cannot carry out the right "reduction," meaning, replacing some element in the tree with the recursive element it contains, to successfully continue the traversal. "This type of error underscores the challenges LLMs face in maintaining algorithmic consistency over extended sequences, particularly when the task requires adherence to a precise order of operations," they write.
Not only do the LLMs fail to properly solve some traversals, but the programs fail to explain, given an example in the prompt, what the rule is that might be used for a successful traversal.
"LLMs struggle to find the correct rules from in-context examples," write Zhang and team, "and fail in interesting ways when performing in-context step-wise reduction."
What does it mean that the programs can't handle recursion?
Also: For the age of the AI PC, here comes a new test of speed
At one level, lacking the ability to work with recursion speaks to a lack of logic, write Zhang and team. "Performing each reduction step in a tree traversal requires more sophisticated logical reasoning," and that's just not in the programs.
However, even humans who don't have a very good grasp of formal logic can instantly appreciate the kind of recursion that occurs in the "movie within a movie" type and other examples.
On a much simpler level, the design of the GPTs needs to be reconsidered by their creators, the authors suggest.
"We hypothesize the fundamental cause [of failures] is that the model has not been optimized to represent recursive patterns well enough," they write. "Our in-context learning experiments revealed the lack of ability for LLMs to 'think recursively' as it tends to mine non-recursive rules from data.
"Also, the models lack accuracy when performing step-wise reduction, where they may get lost in the middle or fail to apply the stopping condition."
Left out of the study are all the ways that the inability to handle recursion may hamper the performance of Gen AI on various tasks, from essay writing to computer programming. It's true that, as Zhang and team note, the programs can compensate, up to a point, with little tricks they pick up.
And yet, recursion is such a fundamental phenomenon that at some point, its absence is bound to have consequences for the programs.
AI2 open sources text-generating AI models — and the data used to train them Kyle Wiggers 13 hours
The Allen Institute for AI (AI2), the nonprofit AI research institute founded by late Microsoft co-founder Paul Allen, is releasing several GenAI language models it claims are more “open” than others — and, importantly, licensed in such a way that developers can use them unfettered for training, experimentation and even commercialization
Called OLMo, an acronym for “Open Language Models,” the models and the dataset used to train them, Dolma — one of the largest public datasets of its kind — were designed to study the high-level science behind text-generating AI, according to AI2 senior software engineer Dirk Groeneveld.
“‘Open’ is an overloaded term when it comes to [text-generating models],” Groeneveld told TechCrunch in an email interview. “We expect researchers and practitioners will seize the OLMo framework as an opportunity to analyze a model trained on one of the largest public data sets released to date, along with all the components necessary for building the models.”
Open source text-generating models are becoming a dime a dozen, with organizations from Meta to Mistral releasing highly capable models for any developer to use and fine-tune. But Groeneveld makes the case that many of these models can’t really be considered open because they were trained “behind closed doors” and on proprietary, opaque sets of data.
By contrast, the OLMo models, which were created with the help of partners including Harvard, AMD and Databricks, ship with the code that was used to produce their training data as well as training and evaluation metrics and logs.
In terms of performance, the most capable OLMo model, OLMo 7B, is a “compelling and strong” alternative to Meta’s Llama 2, Groeneveld asserts — depending on the application. On certain benchmarks, particularly those touching on reading comprehension, OLMo 7B edges out Llama 2. But in others, particularly question-answering tests, OLMo 7B is slightly behind.
The OLMo models have other limitations, like low-quality outputs in languages that aren’t English (Dolma contains mostly English-language content) and weak code-generating capabilities. But Groeneveld stressed that it’s early days.
“OLMo is not designed to be multilingual — yet,” he said. “[And while] at this stage, the primary focus of the OLMo framework [wasn’t] code generation, to give a head start to future code-based fine-turning projects, OLMo’s data mix currently contains about 15% code.”
I asked Groeneveld whether he was concerned that the OLMo models, which can be used commercially and are performant enough to run on consumer GPUs like the Nvidia 3090, might be leveraged in unintended, possibly malicious ways by bad actors. A recent study by Democracy Reporting International’s Disinfo Radar project, which aims to identify and address disinformation trends and technologies, found that two popular open text-generating models, Hugging Face’s Zephyr and Databricks’ Dolly, reliably generate toxic content — responding to malevolent prompts with “imaginative” harmful content.
Groeneveld believes that the benefits outweigh the harms in the end.
“[B]uilding this open platform will actually facilitate more research on how these models can be dangerous and what we can do to fix them,” he said. “Yes, it’s possible open models may be used inappropriately or for unintended purposes. [However, this] approach also promotes technical advancements that lead to more ethical models; is a prerequisite for verification and reproducibility, as these can only be achieved with access to the full stack; and reduces a growing concentration of power, creating more equitable access.”
In the coming months, AI2 plans to release larger and more capable OLMo models, including multimodal models (i.e. models that understand modalities beyond text), and additional datasets for training and fine-tuning. As with the initial OLMo and Dolma release, all resources will be made available for free on GitHub and the AI project hosting platform Hugging Face.
The medical community agrees that, for children with developmental delays such as autism, early is everything. Early diagnosis and early interventions have been shown to make life-changing differences. With as many as 25% of children at risk for a developmental delay in the U.S. alone, there is no debate that it is our duty as a nation to provide early, accessible, and equitable care for all children and their families.
Yet, as demonstrated in a recent report, entitled “The State of Pediatric Autism Diagnosis in the U.S.: Gridlocks, Inequities, and Missed Opportunities Persist”, long wait times and barriers to care in pediatric specialty centers across the U.S. have reached crisis level. The survey – designed and conducted by Scott Badesch, Former President of the Autism Society of America, and sponsored by my company, Cognoa – reveals the inefficiencies and inequities in the status quo processes for evaluating and diagnosing developmental delays and autism. From unnecessarily complex and lengthy diagnostic processes and a dwindling specialist workforce to inadequate reimbursement and access, the report's findings confirm an unfortunate reality: we, as a nation, are failing our children.
While the current state of affairs appears grim, technological innovations can offer a significant and immediate reprieve from a number of these significant barriers.
The healthcare community, along with payors, policymakers, and technologists, need to act swiftly to ensure such technology is made available, and affordable, to address these dire issues and ensure no more children are left behind.
Early is Everything – The Lifelong Effects of Diagnostic Delays
The CDC estimates that autism affects 1 in 36 children in the U.S. today.
Although autism can be reliably diagnosed as early as 18 months, the average age of diagnosis has remained stagnant at over 4 years of age. Non-white children, females, and those from rural areas or disadvantaged socio-economic backgrounds are often diagnosed even later or missed altogether.
Early interventions during the critical early neurodevelopmental period, before the age of 3, have been shown to dramatically improve lifelong outcomes for children. In fact, studies have even shown that 4 out of 10 children diagnosed with autism at age 2-3 have such significant improvements with early intervention that the diagnosis loses relevance by age 6. In contrast, lack of or delayed treatment increases the likelihood of lifelong, comorbid mental health conditions, while all-cause medical costs are approximately double for children who experience a longer time to diagnosis compared with a shorter time to diagnosis.
Process Paralysis
As highlighted in the survey report, long wait times for autism diagnosis at pediatric specialty care centers across the U.S. are unacceptably common. According to the study, some 61% of specialty centers surveyed report wait times of over 4 months between the initial request for an autism evaluation and the evaluation itself. Disturbingly, 25% reported waitlists stretching to over half a year, and 21% reported waitlists extending beyond a year or were so inundated with requests that they could no longer accept new referrals.
One of the primary factors exacerbating this issue, as identified by 77% of clinics in the study, is the extreme length of assessment processes and heavy documentation burdens that clinicians must shoulder. 69% of clinics also identified staffing issues, including clinician and administrator shortages, and an alarming 43% cited burdensome reimbursement processes, lack of reimbursement, and a refusal to accept Medicaid and commercial insurance as significant barriers.
Accessibility to diagnostic centers is another constraint compounding the problem. Over 80% of counties in the U.S. do not have diagnostic centers for autism within commuting distance, making it even more challenging for families living in these areas to receive timely interventions.
A lack of standardization in the diagnostic process presents further challenges. More than 30 different tools are used across the country with the types of assessment and provider required for the autism diagnosis to be recognized varying from state-to-state and payer-to-payer. Additionally, 83% of centers report that autism evaluations take over 3 hours, with 25% reporting completion times of over 8 hours. This lack of efficiency and standardization only serves to keep children and their families in limbo for longer.
AI Busting Barriers
Rather than referring all children for specialist evaluations, the American Academy of Pediatrics (AAP) has stressed that pediatricians in primary care “can significantly affect the outcome of children with autism by making an early diagnosis and providing referral for evidenced-based behavioral treatment” in the primary care setting – rather than referring all children for specialist evaluations. As the first line of care for children, pediatricians are well positioned to play a significant role in tackling diagnostic delays and ensuring early interventions when they matter most.
Harnessing the power of AI and technological innovations can empower pediatricians to evaluate, diagnose, and manage children with developmental delays and autism accurately and rapidly. AI has the immense potential to help streamline and standardize the autism evaluation and diagnostic process, address physician shortages by expanding the pool of providers who can evaluate and diagnose children, and ensure wider, more equitable and timely access to care across primary and specialty care settings.
AI is able to assess thousands of human traits and features – including a variety of verbal and movement indicators – to identify the most predictive traits that point toward autism. AI can make the diagnosis journey more efficient and equitable by reducing time-intensive evaluations that are often unnecessary for many children and ensure a more consistent approach to diagnosis across all demographics.
AI can therefore make healthcare more accessible, affordable, and effective, but only if it is developed responsibly – AI systems are only as good as the data they are built upon. Diversity is crucial to account for differences in gender, race, ethnicity and socio-economic backgrounds. Programmers should constantly test and correct algorithms to ensure data is up-to-date and truly representative of all demographics. In practical terms, that means employing coders from a diverse range of backgrounds, and encouraging them to feed new, diverse samples into their code. This is extremely important in the diagnosis of autism for many reasons, not the least of which is that girls with autism show different traits than boys and on average are diagnosed 1.5 years later than boys.
While AI can undoubtedly address inherent limitations, create efficient, safe and life altering solutions, it must also go hand in hand with the human touch. AI serves to support physicians so they can provide answers faster and more effectively based on massive amounts of data and allows them to spend their time more productively with their patients.
The Road Ahead
Emerging innovations reveal a promising future in the diagnosis of autism, but only if optimized and utilized across appropriate settings. Policies that support reimbursement and access to AI-driven solutions approved by the FDA must be adopted. When responsibly trained on unbiased, population representative data, AI can empower more providers to confidently evaluate, diagnose, and manage children within primary care.
The goal is clear – we need to provide every child with the opportunity for early intervention. The medical community is in unanimous agreement. The data is unequivocal. The technology exists. It’s time to buck the status quo and call on our policymakers, healthcare leaders, insurers, and technologists to prioritize and address the issues surrounding the diagnosis of children with developmental delay and autism. We can actively do better.
Google was quick to join the AI race, rushing to get its own AI chatbot, Google Bard, on the market. However, the company took an entirely different approach in the AI image generator space, declining to launch its capable Imagen model to the public — until now.
On Thursday, Google announced a series of AI updates. The biggest highlights were in the image-generating space, including a brand new image generator, as well as the ability to generate images in Bard.
Also: The best AI chatbots
ImageFX is a new image-generation tool that users can use to generate images from text the same way they would with any other AI model, such as DALL-E 3.
However, Google's spin on the AI image generator features a prompt interface that includes "expressive chips," which furthers user creativity by allowing them to experiment with "adjacent dimensions of your creation and ideas," according to Google.
Users can access the tool in Google Labs, the company's experimental platform in which users can test out the company's early ideas for features and products, such as the Search Generative Experience (SGE).
Also: Microsoft's big bet on AI seems to be paying off
The tool is powered by Imagen 2, Google's most advanced text-to-image model, developed by Google DeepMind and released last month. Google claims it can generate its highest quality images, even rendering challenging tasks such as human faces and hands realistically.
Imagen 2 will also be found in Google Bard, giving the chatbot the ability to generate images for the first time. All you need to do is ask Bard to generate a photo using a conversational prompt, and Bard will be able to generate a high-quality image. The feature is available starting today in most countries in English.
Google is also infusing Imagen 2 across its offerings, including Ads, Duet AI in Workspace, SGE, and Google Cloud's Vertex AI.
To address concerns regarding the misuse of AI image generators, Google reassured users that it has implemented the necessary guardrails to prevent generating violent, offensive, and sexually explicit content.
Also: Microsoft adds new Designer protections following Taylor Swift deepfake debacle
Additionally, all images generated with Imagen 2 will be watermarked with SynthID, a tool developed by Google DeepMind that watermarks photos in a way that is imperceptible to the human eye but can be used for identification.
When you look at the "About this image" insights in Search and Chrome, it will show whether the photo was generated using Google's AI tools.