Cohere Releases Command-R, a Model Focused on Scalability and RAG

Cohere recently introduced Command-R, a language learning model focused on enterprise applications. The language learning model is designed to understand, interpret, and generate human-like text based on the data it’s been trained on.

This model can perform tasks like Retrieval Augmented Generation (RAG) and tool integration, to improve efficiency and accuracy at a large scale. It targets businesses seeking to deploy AI solutions broadly, offering capabilities like a 128k context window, fluency in 10 languages, enhanced performance metrics, and adherence to privacy and security standards.

“Compared to the last Command, Command-R is smarter, longer context, cheaper (same as the latest gpt3.5t), and you can access the weights directly,” Aiden Gomez the CEO of the company posted on X.

Command-R is now available on Cohere’s hosted API and will be on major cloud platforms soon. Its model weights are also accessible on Hugging Face for research.

The model is optimised for RAG, enabling better information retrieval and ranking with Cohere’s Embed and Rerank models. It supports automation of complex tasks through tool integration and is versatile across 10 major languages, expanding its utility globally.

Cohere released Command-R Amidst a potential $1 billion fundraising round. This is a major advancement in AI for enterprise use, highlighting the market’s appetite for functional AI solutions.

In contrast to OpenAI’s broader, consumer-oriented ChatGPT, Cohere’s Command-R launch directly targets the enterprise market. The company recently partnered with Accenture which will be one of the companies it offers features like improved RAG performance and a competitive pricing for businesses, emphasising privacy, data security, and avoiding vendor lock-in.

The post Cohere Releases Command-R, a Model Focused on Scalability and RAG appeared first on Analytics India Magazine.

AI is Now Killing Prompt Engineering Jobs

How many times have we heard that prompt engineering is the job of the future? Ever since ChatGPT was launched, everyone started experimenting with different ways of prompting the chatbot and called it a job. Others were scared of losing their jobs, thanks to this new role. Well, it now turns out that AI can do it and do it better than humans.

“Did anybody, but the most desperate climbers, ever honestly believe that ‘typing prompts into ChatGPT’ was ever going to be a high-paying full-time job?” asked a user on HackerNews.

In a recent study, VMware researchers found that LLMs become more unpredictable when humans start experimenting with weird prompts. Even more interesting was another research team’s finding that concluded that “no human should manually optimise prompts ever again”. The best prompt engineering is done by the AI model itself.

Problems Aplenty with Manual Prompting

Rick Battle and Teja Gollapudi from VMware experimented with big and small language models and tried different prompting techniques to figure out the most optimal and efficient way to do it. “It’s both surprising and irritating that trivial modifications to the prompt can exhibit such dramatic swings in performance,” read the conclusion of the paper.

They even highlighted that there is no obvious methodology that could improve performance, and the effects would be very trivial. For example, the research concluded that practitioners do not even need GPT-4 or PaLM-2 size models to use effective prompts. In their experiment Llama 13B and Mistral-7B were able to produce “superior prompts”, which they found shocking.

“It’s undeniable that the automatically generated prompts perform better and generalise better than hand-tuned ‘positive thinking’ prompts,” the paper concluded, saying that even after giving positive affirmation to chatbots, automatic prompts perform better – also called auto prompting.

“I literally could not believe some of the stuff that it generated,” Battle said in an interview, talking about how no human could ever generate the prompt that the system generated itself, as it was bizarre.

Bias in ML systems can come from bias in the training data. But that's only one possible source of bias among many. Arguably, prompt engineering can be an even worse source of bias.
Literally any part of your system can introduce biases. Even non-model parts, like your…

— François Chollet (@fchollet) February 23, 2024

Another aspect of prompt engineering is that it creates bias in the output of the model, which observers can attribute to the AI model itself. “Arguably, prompt engineering can be an even worse source of bias,” said François Chollet.

People are confusing prompt engineering with just giving prompts to a chatbot in English language, while what the model does is actually a lot of maths, English is just the frontend of the model. Therefore, the AI models can do it better.

It only makes sense. “In LLMs, the need for prompt engineering is a sign of *lack* of robust language understanding,” said Melanie Mitchell in a post on X last year. That seems to be the case even now, even after a year of development and scaling of language models.

Was Prompting Just a Passing Fad?

Just like C++ was considered a “dying language”, prompt engineering is regarded as a passing fad. Logging onto ChatGPT or Codex and just typing in what you want does not work that easily. It’s a skill to learn. And now, with AI doing it better than humans, it is a matter of time that it vanishes. But will it?

Most of prompt engineering is just about trial and error, and now with AI, that is not needed anymore. Now that companies are hiring for roles such as LLMOps, they might be labelled as the new prompt engineers, but as a job, it won’t die.

Douglas Crockford, one of the developers of JavaScript and the brain behind the JSON format, is worried about English as a programming language “because it’s so ambiguous,” he said in an interview with AIM.

He clarified that the fundamental law of programming is that the program has to be perfect. “It has to be perfect in every aspect, in every detail, for all states for all time”. He further elaborated that if it isn’t, the computer is licensed to do the worst possible thing at the worst possible time. “It’s not the computer’s fault, it is the programmers’ fault,” he noted.

Another important aspect to note about prompt engineering is that it changes as people experiment with different data sources and different AI models. And as companies are adapting different open source and closed source models, what is the best combination of prompts for each model might still be a job that someone needs to do.

We’re calling them prompt engineers today, maybe as AI improves, we will call them something else. That is not to say that prompt engineering holds no value. It has already found its niche and is probably going to stay here for a while, but not too long.

The post AI is Now Killing Prompt Engineering Jobs appeared first on Analytics India Magazine.

When to RAG, and When (Not) to XGBoost 

When to RAG, and When (Not) to XGBoost

“If you had asked AI experts what an LLM was before [the launch of ChatGPT in] 2022, many probably would have answered that it’s a law degree,” quipped Oliver Molander in his post on LinkedIn, adding how many find it extremely difficult to accept that AI is much more than just LLMs and text-to-video models.

And the real winner, when it comes to tabular data and making sense of sheets, is XGBoost (aka Extreme Gradient Boosting). It excels on all fronts, amid all the hype around other deep learning techniques, even LLMs, or the recent one Retrieval Augment Generation (RAG). XGBoost 2.0, launched in October last year, made it perform even better on several new classifications.

Though techniques like XGBoost and deep learning are not directly comparable, their functions are the same – to retrieve, make sense of information, and generate outputs.

Many such cases.
Reject FOMO, embrace tradition. https://t.co/1b3rW5kRVK

— Bojan Tunguz (@tunguz) March 10, 2024

Heard of the New XGBoost LLM?

Despite the advancements in generative AI and the proliferation of LLMs, the practical utility of XGBoost remains unparalleled, particularly in domains reliant on tabular datasets. XGBoost’s interpretability, efficiency, and robustness make it indispensable for applications ranging from finance to healthcare.

The hype around LLMs has made people forget about the importance of other ML techniques, such as XGBoost. VCs are so hell-bent on hopping onto the GenAI and LLM bandwagon that every new terminology is often mislabelled as a new type of LLM.

But in reality, a huge chunk of the return of investment is concentrated around predictive ML techniques and techniques such as XGBoost and Random Forest. The majority of business use cases out there for AI/ML are done with proprietary tabular business data.

When dealing with tabular datasets, efficiency is paramount. XGBoost’s versatility extends beyond classification to regression and ranking tasks. Whether you need to predict a continuous target variable, rank items by relevance, or classify data into multiple categories, XGBoost can handle it with ease.

However, the deployment of RAG is not without its challenges, particularly those concerning data privacy and security. Instances of prompt injection vulnerabilities underscore the need for robust safeguards in leveraging RAG-enabled models.

XGBoost’s interpretability, efficiency, and versatility make it the preferred choice for many predictive modelling endeavours, particularly those reliant on tabular data. Conversely, the evolving capabilities of LLMs and the augmentative potential of RAG offer tantalising prospects for knowledge-intensive applications.

RAG is Too Good, But Not so Much

A study conducted in July 2022, analysing 45 mid-sized datasets, revealed that tree-based models such as XGBoost and Random Forests continued to exhibit superior performance compared to deep neural networks when applied to tabular datasets.

RAG burst onto the scene in 2020 when the brainiacs at Meta AI decided to jazz up the world of LLMs. It’s a game-changer. Designed to give LLMs the much-needed information techniques, RAG swooped in to fix the problems that haunted its predecessors – the dreaded hallucinations.

With RAG, customers can add another dataset, and give the LLM fresh information to generate the answer from. Some call this “fancier prompt engineering”. This is what enterprises need to generate insights from their own data. But even then, this technique has not completely fixed the hallucination issue within LLMs, but arguably made it even worse since people started trusting these models even more.

Traditionally, there have been two distinct groups in the ML ecosystem: the tabular-data-focused data scientists who use XGBoost, lightBGM, and similar tools, and the LLM group. Both these groups have used separate techniques and models. “I have always been a big fan of XGBoost! There was a time, I was more of an XGBoost modeller than an ML modeller,” said Damein Benveniste from The AiEdge on LinkedIn.

Everyone is focussed on developing LLMs.

— Marc (@marccodess) August 29, 2023

The LLMs produce textual output, but the focus here is on using the internal embeddings (latent structure embeddings) generated by LLMs, which can be passed to traditional tabular models like XGBoost. While Transformers have undoubtedly revolutionised generative AI, their strengths lie in unstructured data, sequential data, and tasks that involve complex patterns.

Krishna Rastogi, CTO of MachineHack said, “Transformers are like the H-bombs of machine learning, and XGBoost is the reliable sniper rifle. When it comes to tabular data, XGBoost proves to be the sharpshooter of choice.”

The post When to RAG, and When (Not) to XGBoost appeared first on Analytics India Magazine.

Why Are Data Centres in India Moving to Tier 2, 3 and 4 Cities?

Of late, several giants, including AdaniConnex, Reliance, Sify, Atlassian, Yotta, AWS, and Lenovo, have announced substantial investments in data centres across India. With the growth of India’s data centre market, the capacity is projected to surpass 1,300 MW by the end of 2024, a notable increase from 1,048 MW at the end of 2023 and 880 MW as of June 2023.

However, the concentration of data centres remains prominent in seven cities like Mumbai-Navi Mumbai, Chennai, Delhi-NCR, Bengaluru, Pune, Hyderabad, and Kolkata.

These cities accounted for a 35% year-on-year growth, reaching 884 MW capacity and spanning over 13 million sqft by the end of 2023. Mumbai-Navi Mumbai leads with a 52% share of the total data centre capacity, followed by Chennai (16%), Delhi-NCR (11%), Bengaluru (9%), Pune (7%), Hyderabad (4%), and Kolkata (1%).

Despite the concentration in the top-four locations, the emergence of co-location and edge computing facilities is expected to shift the dynamics, with edge data centres expanding into Tier 2 cities in 2024.

Overall, the data centre occupancy level in India stood at about 75-80% in 2023 and is likely to improve by the end of 2024. This expansion is driven by the need for edge computing and the desire to be closer to customers in these areas, offering a faster response time and lower latency for time-sensitive applications.

Who’s Moving and Where?

Nxtra and CtrlS are among the leading data centre players actively expanding their edge computing infrastructure in Tier 2 and 3 cities to meet the burgeoning demand.

Nxtra, Airtel’s data centre arm, operates 120 edge data centres in 65 cities, like Bhopal, Nagpur, Cuttack, Ranchi, Patna, Raipur, Kanpur, Madurai, and Leh. These facilities have capacities ranging from 1 to 5 megawatts, and the company plans to expand its edge data centre infrastructure further.

CtrlS, on the other hand, envisions creating over 20 edge data centres across Tier 2 and Tier 3 cities in the coming years. It currently has edge data centres in Lucknow and Patna. It further plans to expand its capacity this year and open a new facility in Kolkata.

Yotta Data Services, backed by the Hiranandani Group, is expanding its operations in Greater Noida and Guwahati, tapping into the burgeoning demand for edge facilities in Tier 2 markets. These operations are expected to be completed and operational by the end of 2024.

With Yotta-D1 nearing full capacity at 85%, the company is moving forward with the construction of its D2 and D3 facilities

STT GDC India, a subsidiary of Singapore’s STT GDC, has announced its plans to invest $1 billion in the next 3-4 years to expand its data centre footprint across India, including Tier 2 cities. The company aims to build at least two data centres in Tier 2 cities this year and about eight in the next three years.

These expansions are part of a broader trend towards decentralising data centre infrastructure to better serve a distributed user base across India. The move towards Tier 2, 3, and 4 cities is expected to support the low-latency requirements of 5G and support AI applications that require real-time processing and analysis for faster decision-making.

Benefits of This Move

Building data centres in Tier 2 and Tier 3 cities in India offers several advantages over their establishment in larger cities. Positioning data centres closer to users in these cities can significantly reduce latency, enhancing the digital experience for services that demand quick data processing. These could be for online gaming, streaming, and financial transactions.

This proximity is crucial for the emerging needs driven by 5G, OTT streaming, online gaming, and AI technologies.

Secondly, Tier 2 and Tier 3 cities may provide more opportunities for constructing green data centres. More available space and less stringent regulations can facilitate the adoption of sustainable practices, including using renewable energy sources and advanced cooling technologies. This aligns with the broader industry trend towards sustainability.

Furthermore, these cities represent untapped markets with considerable growth potential. As the digital economy expands, the demand for digital services in these areas increases, offering data centre operators new markets to explore and support regional development.

This expansion can also drive improvements in connectivity infrastructure and lead to the creation of modern office spaces and tech parks, attracting more business and talent to these regions.

Additionally, both central and state governments in India have recognised the potential of the data centre industry and have introduced policies and incentives to support its growth. These include draft data centre policies, infrastructure status for the industry, and the inclusion of data centres in the harmonised list of infrastructure.

States like Karnataka, Tamil Nadu, Uttar Pradesh, Odisha, Telangana, and West Bengal have announced data centre policies to facilitate investments in the last two years.

Conclusively, developing data centres in Tier 2 and Tier 3 cities contributes to more balanced regional development, creates job opportunities, and supports government initiatives to digitise the nation’s economy. It also meets the country’s growing digital needs by decentralising the data centre industry to serve a distributed user base better.

Delayed, But Rewarding

In conversation with AIM, industry luminaries like Saandeep Dandekarr and Rachit Mohan, emphasised that while there is a definite trend towards this shift, it will take time to mature, estimating about two to five years for a significant footprint in Tier 2 and 3 cities.

“It will take time to mature, but that’s the way forward for sure,” Dandekarr said, while Mohan was of the opinion that the move, “Will take a couple of years to mature.”

This timeline, he said, accounts for the various stages involved, from acquiring land to designing, constructing, and commissioning data centres, considering the current infrastructure penetration in these areas.

Dandekarr highlighted that cities like Hyderabad and Pune, previously considered Tier 2, are already witnessing the emergence of data centres, driven by universal demand for services such as OTT and gaming. He also reiterated the role of incentives provided to the data centre industry and other sectors, in determining the location of these new facilities.

The move would also add a bunch of jobs, which Dandekarr categorised as the construction phase, which would see a temporary spike in employment, and the operational phase, promising more sustainable job opportunities, albeit with a smaller workforce due to advancements in automation and AI.

“So, in a three lakh square feet data centre, instead of 4,000 people, we will have maybe 200 to 50 people actually in the operations,” he elaborated.

He also discussed the impact of AI on automating processes within data centres, moving from a reactive to a predictive approach to enhance efficiency and reduce the workforce.

“So, right from security access, PCs, and TVs, to let’s say, temperature and battery maintenance, everything is becoming predictive from reaction or response base to predictive, right? And that is where AI is coming,” he mentioned

Conclusively, he opined that there will be indirect job creation through the vendor ecosystem required for maintenance and service support, indicating a broader impact on employment in the regions hosting new data centres.

The post Why Are Data Centres in India Moving to Tier 2, 3 and 4 Cities? appeared first on Analytics India Magazine.

This AI Horror Movie Will Chill Your Spine 

‘Another’, a short film unique for its blend of live-action with AI VFX techniques, was released on Monday, March 11, 2024. This film in the horror genre is touted to be the first of its kind and is available on YouTube.

Writer and director Dave Clark, along with VFX Supervisor Rob Nederhorst, said they would discuss making this hybrid film in a behind-the-scenes feature following the premiere.

Dave Clark, known for ‘Afraid2Sleep,’ ​has millions of views for his work directing movies using AI. He was featured several times on Forbes, NBC, and No Film School. He has experience creating commercials and immersive engagements for Snapchat, Hewlett-Packard, Pepsi, Intel, etc. Robert Nederhost has 18 years of experience in commercial/TV/feature filmmaking and is currently the CTO of Narrate Inc.

Window Seat, a feature film released in July last year was completely created by AI. Filmmaker Hooroo Jackson, directed the movie but the script, animation, vocals were all created using AI tools.

YouTube allows the monetisation of AI content with the added caveat of requiring creators to label AI content. This has encouraged more artists to embrace AI, and there are an increasing number of short films and even feature-length movies.

A collective of fifty filmmakers and artists in the AI space have released ‘Our T2 Remake,’ created entirely with AI. This project parodies the classic Terminator 2, providing satirical commentary on modern AI technology and its societal implications.

Contrary to the notion that AI filmmaking is merely a push of a button, the creators invested three months in this endeavour, using advanced technology to make the film meticulously.

The filmmaking landscape is witnessing a transformative shift with the advent of AI, notably embraced by both independent filmmakers and major studios. The Runway AI Film Festival, established in 2022, encourages this movement by celebrating the fusion of AI technology with artistic expression.

The post This AI Horror Movie Will Chill Your Spine appeared first on Analytics India Magazine.

Midjourney Unveils New Feature to Create Consistent Characters

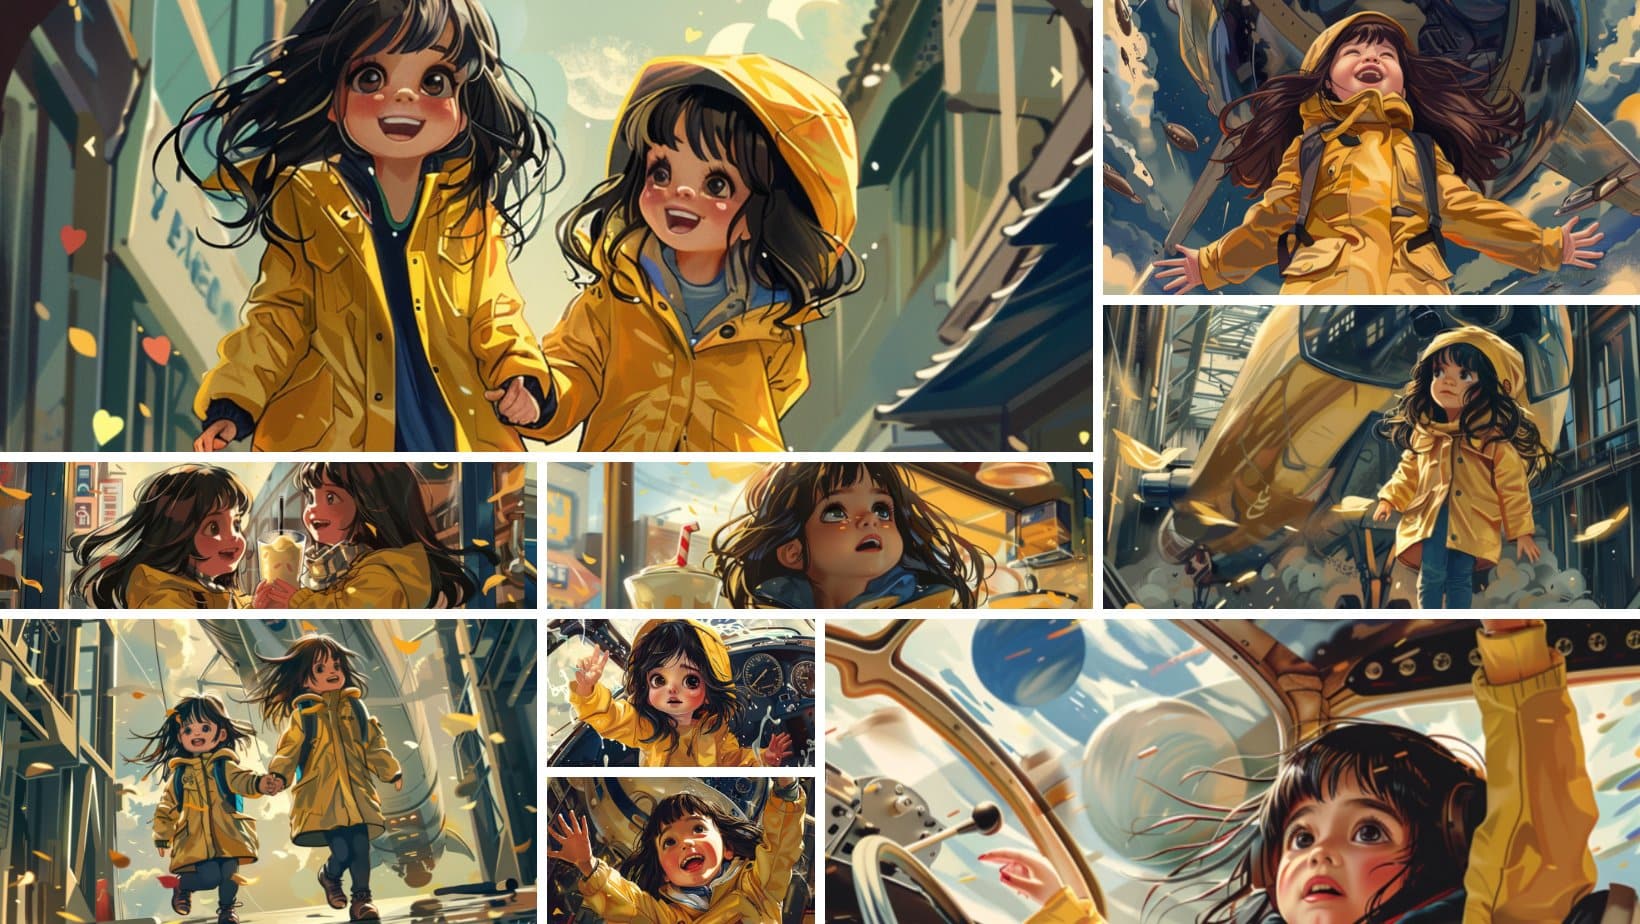
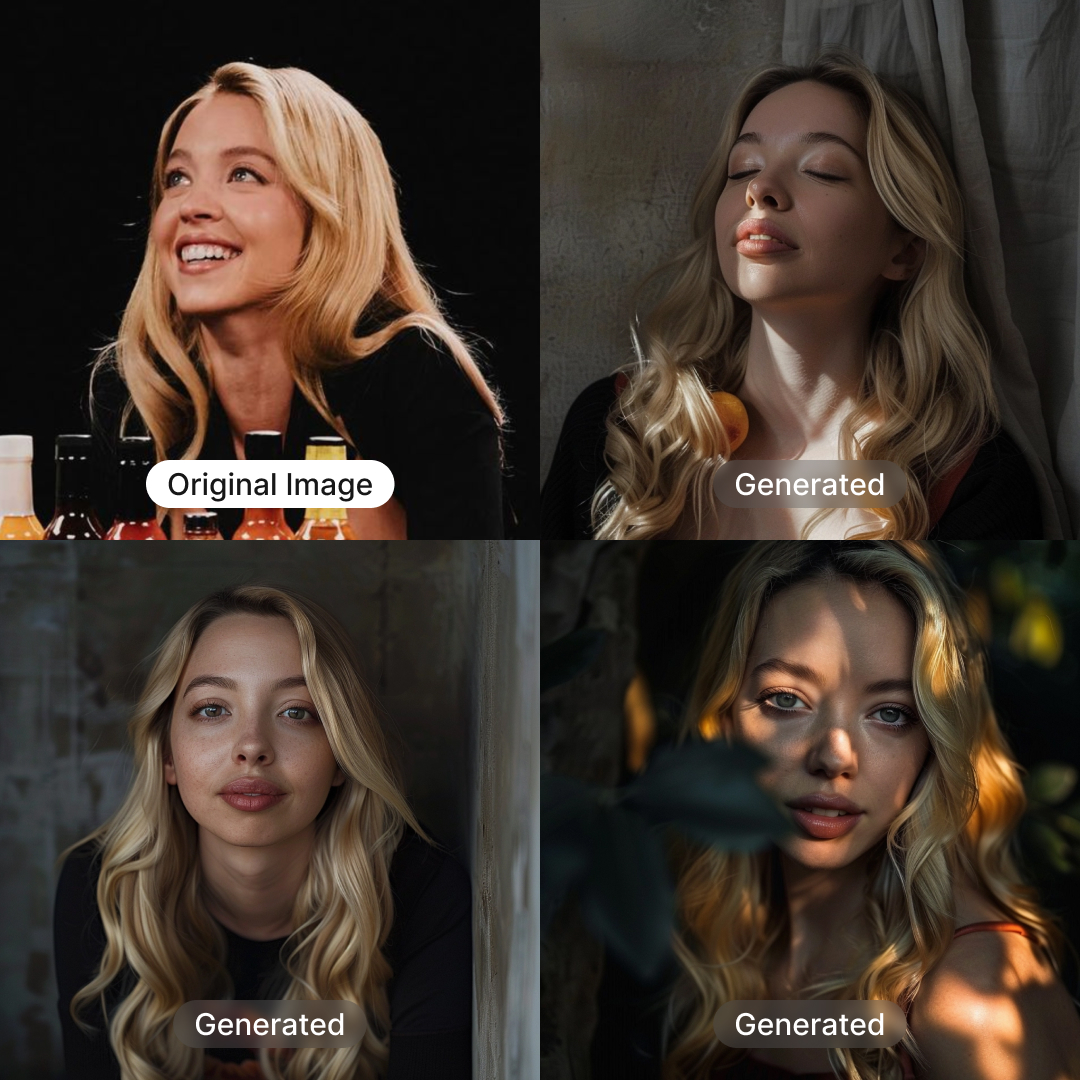
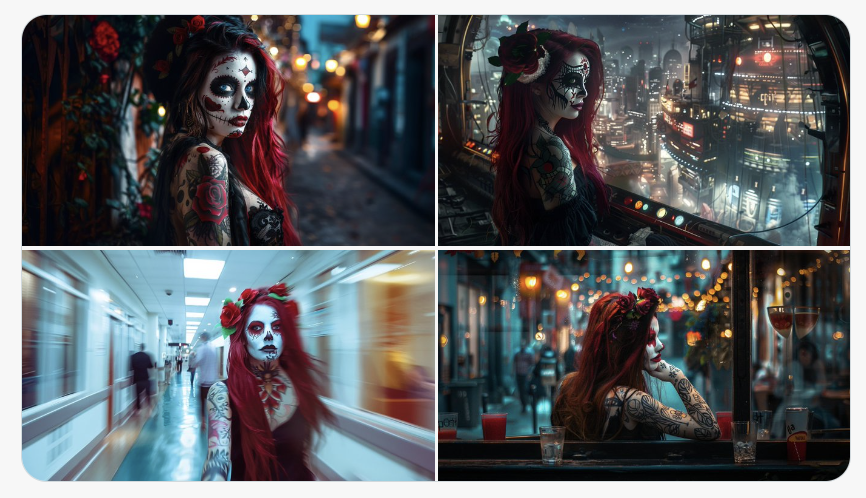
San Francisco based generative AI research lab Midjourney has released the new feature called “Character Reference” that claims to generate consistent characters across multiple reference images, a struggle users have been going through for a while now.

Source: Dogan Ural on X

How it Works

  • Type “–cref URL” after your prompt with a character image URL.
  • Modify reference ‘strength’ using “–cw” from 100 to 0.
    • Default strength 100 (–cw 100) considers face, hair, and clothes.
    • Strength 0 (–cw 0) focuses only on the face (ideal for changing outfits/hair).
  • Blend information from multiple images using “–cref URL1 URL2” (similar to multiple image or style prompts).

Generate Character Image

  • Retrieve or generate the character image URL through Midjourney.
  • Use “–cref” followed by the URL to generate the character in various settings.

Adjust Image Variance

  • Control how closely the new image reproduces the original character.
  • Use “–cw” followed by a number (1 to 100) to adjust the variance.
    • Lower numbers provide more variation.
    • Higher numbers closely follow the original reference.

Advanced Options and Considerations

  • Use multiple “–cref” tags with respective URLs to blend information from multiple images.
  • In Midjourney’s web alpha version, users can drag or paste an image, selecting it as a prompt, style reference, or character reference.

Several users have taken to social media to appreciate the new feature.

Source: Deedy (X)

The post Midjourney Unveils New Feature to Create Consistent Characters appeared first on Analytics India Magazine.
You can refine your Pinterest search results by body type now. Here’s how it works

Pinterest body type ranges

People rely on Pinterest to get inspiration for everyday projects, including event planning and day-to-day outfits. The search results typically show the most relevant pins, even if the models look nothing like the user. With the help of AI, however, Pinterest's search results are about to get much more personalized.

Pinterest today announced body type ranges, a new AI-enabled tool that lets women choose what body type they would like featured in their search results when they're looking for outfits or wedding items.

Also: AI image classification errors could ruin your life. Here's one way to reduce them

To get started, open the Pinterest app, click the search icon, type a query related to outfits or weddings into the search bar, click body types at the top of the search results, and select the body range that best represents you.

Pinterest's patent-pending body type technology will then sort through the over 3.5 billion images on the platform for shape, size, and form to deliver personalized results.

"Pinterest is a visual discovery platform and we want users to be able to see themselves reflected in their search results," Pinterest Chief Product Officer Sabrina Ellis said.

Ellis added that the company has already seen positive user engagement with the feature. People who use body type ranges have a 66% higher engagement rate per session on Pinterest than those who haven't used the tool.

While the feature is currently limited to women's wedding and outfit inspiration, Pinterest plans to roll it out more widely later this year, including to encompass men's fashion.

The feature builds on Pinterest's other inclusive tools, such as skin tone ranges and hair pattern search, which let users pick their skin tone and hair texture when searching for beauty inspiration such as makeup and hairstyles.

Artificial Intelligence

Should artists be paid for training data? OpenAI VP wouldn’t say

Should artists be paid for training data? OpenAI VP wouldn’t say Kyle Wiggers 11 hours

Should artists whose work was used to train generative AI like ChatGPT be compensated for their contributions? Peter Deng, VP of consumer product at OpenAI — the maker of ChatGPT — was loath to give an answer when asked on SXSW’s main stage this afternoon.

“That’s a great question,” he said when SignalFire venture partner (and former TechCrunch writer) Josh Constine, who interviewed Deng in a wide-ranging fireside, asked the question. Some in the crowd of onlookers shouted “yes” in response, which Deng acknowledged. “I’m hearing from the audience that they do. I’m hearing from the audience they do.”

That Deng dodged the question isn’t surprising. OpenAI is in a delicate legal position where it concerns the ways in which it uses data to train generative AI systems like the art-creating tool DALL-E 3, which is incorporated into ChatGPT.

Systems like DALL-E 3 are trained on an enormous number of examples — artwork, illustrations, photos and so on — usually sourced from public sites and datasets around the web. OpenAI and other generative AI vendors argue that fair use, the legal doctrine that allows for the use of copyrighted works to make a secondary creation as long as it’s transformative, shields their practice of scraping public data and using it for training without compensating or even crediting artists.

OpenAI, in fact, recently argued that it would be impossible to create useful AI models absent copyrighted material. “Training AI models using publicly available internet materials is fair use, as supported by long-standing and widely accepted precedents,” writes the company in a January blog post. “We view this principle as fair to creators, necessary for innovators, and critical for U.S. competitiveness.”

Creators, unsurprisingly, disagree.

A class action lawsuit brought by artists including Grzegorz Rutkowski, known for his work on Dungeons & Dragons and Magic: The Gathering, against OpenAI and several of its rivals (Midjourney and DeviantArt) is making its way through the courts. The defendants argue that tools like DALL-E 3 and Midjourney replicate artists’ styles without the artists’ explicit permission, allowing users to generate new works resembling the artists’ originals for which the artists receive no payment.

OpenAI has licensing agreements in place with some content providers, like Shutterstock, and allows webmasters to block its web crawler from scraping their site for training data. In addition, like some of its rivals, OpenAI lets artists “opt out” of and remove their work from the datasets that the company uses to train its image-generating models. (Some artists have described the opt-out tool, which requires submitting an individual copy of each image to be removed along with a description, as onerous, however.)

Deng said that he believes artists should have more agency in the creation and use of generative AI tools like DALL-E, but isn’t sure, exactly, what form that might take.

“[A]rtists need to be a part of [the] ecosystem as much as possible,” Deng said. “I believe that if we can find a way to make the flywheel of creating art faster, we’ll really help the industry out a bit more … In a sense, every artist has been inspired by artists who’ve come before them, and I wonder how much of that will be accelerated by this.”

Four things we learned when US spy chiefs testified to Congress

Four things we learned when US spy chiefs testified to Congress

US intelligence leaders gave their most recent — and frank — assessment of global cyber threats

Zack Whittaker Lorenzo Franceschi-Bicchierai 7 hours

Cyberattacks, regional conflict, weapons of mass destruction, terrorism, commercial spyware, AI, misinformation, disinformation, deepfakes, and TikTok. These are just some of the top perceived threats that the United States faces, according to the U.S. government’s intelligence agency’s latest global risk assessment.

The unclassified report published Monday — sanitized for public release — gave a frank annual window into the U.S. intelligence community’s collective hive mind about the threats it sees facing the U.S. homeland based on its massive banks of gathered intelligence. Now in an election year, the top U.S. spies increasingly cite emerging technology and cybersecurity as playing a factor in assessing its national security posture.

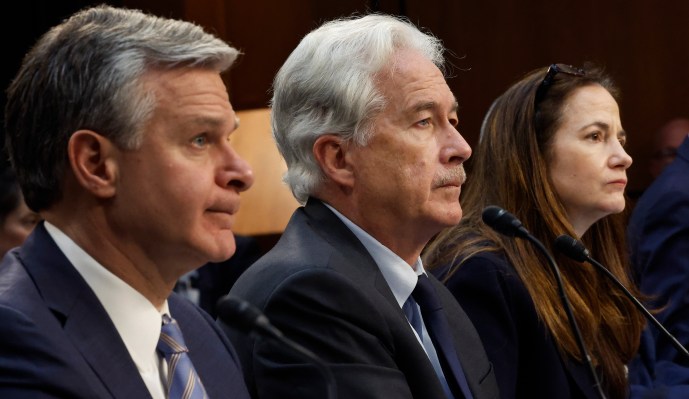
In an unclassified session with the Senate Intelligence Committee on Monday, the top leaders across the U.S. government’s intelligence agencies — including the FBI, NSA, CIA, and others — testified to lawmakers largely to answer their questions about the current state of global affairs.

Here’s what we learned from the hearing.

At least 74 countries use commercial spyware

In the last few years, the U.S. government turned its attention to the government spyware industry, currently made of companies like NSO Group and Intellexa, and previously Hacking Team and FinFisher. In its annual report, the intelligence community wrote that, “from 2011 to 2023, at least 74 countries contracted with private companies to obtain commercial spyware, which governments are increasingly using to target dissidents and journalists.”

The report does not clarify where the intelligence community got that number from, and the Office of the Director of National Intelligence did not respond to a request for comment asking to clarity

But last year, the Carnegie Endowment for International Peace, a Washington D.C. think-tank, released a report on the global spyware industry that included the same number of countries as well as the same dates as the new intelligence community report. The Carnegie report, written by Steven Feldstein and Brian Kot, referenced data that the two collected, which they said came from sources such as digital rights groups and security researchers that have studied the spyware industry like Citizen Lab, the Electronic Frontier Foundation, and Privacy International, as well as news reports.

It’s important to note that the Carnegie dataset, as the authors explained last year, includes what we refer to as government or commercial spyware, meaning tools to remotely hack and surveil targets remotely, such as those that NSO and Intellexa make. But it also includes digital forensic software used to extract data from phones and computers that are physically in the possession of the authorities. Two of the most well known makers of this type of tools are Cellebrite and Grayshift, both of which are widely used in the United States as well as in other countries.

U.S. says it’s struggling to counter ransomware

The U.S. says ransomware is an ongoing risk to U.S. public services and critical infrastructure because cybercriminals associated with ransomware are “improving their attacks, extorting funds, disrupting critical services, and exposing sensitive data.”

Ransomware has become a global problem, with hacking gangs extorting companies in some cases millions in ransom payments to get their stolen files back. Some cybersecurity experts have called on governments to outright ban ransom payments as necessary to stop hackers profiteering from cybercrime.

But the U.S. has shunned that view and takes a different approach, opting to systematically disrupt, dismantle and sanction some of the worst offenders, who are based in Russia and outside of the reach of U.S. justice.

“Absent cooperative law enforcement from Russia or other countries that provide cyber criminals a safe haven or permissive environment, mitigation efforts will remain limited,” the threat assessment reads. In other words, until Russia — and a few other hostile states — give up their criminals, expect ransomware to continue to be the modern-day snow day.

U.S. warns of growing use of AI in influence operations

The use of generative AI in digital influence operations isn’t new, but the wide availability of AI tools is lowering the bar for malicious actors engaging in online influence operations, like election interference and generating deepfakes.

The rise of detailed and convincing deepfake imagery and video is playing its role in information warfare by deliberately sowing confusion and discord, citing Russia’s use of deepfake imagery against Ukraine on the battlefield.

“Russia’s influence actors have adapted their efforts to better hide their hand, and may use new technologies, such as generative AI, to improve their capabilities and reach into Western audiences,” warned the report.

This was something echoed by NSA cybersecurity director Rob Joyce earlier in January about how foreign hackers are using chatbot tools to generate more convincing phishing emails, but that AI is also useful for digital defense.

The report also noted that China is increasingly experimenting with generative AI, noting that TikTok accounts run by a Chinese military propaganda arm “reportedly targeted candidates from both political parties during the U.S. midterm election cycle in 2022.”

There are no laws limiting U.S. spies from buying Americans’ data

U.S. spy agencies have caught on to a popular practice: Why get a warrant for data when they can just buy it online? Given how much data we share from our phone apps (which many don’t give a second thought), U.S. spy agencies are simply buying up vast troves of Americans’ commercially available location data and internet traffic from the data brokers.

How is that legal? After a brief exchange with the head of the Defense Intelligence Agency — one of the agencies confirmed to have bought access to a database containing Americans’ location data — Sen. Ron Wyden noted that the practice was allowed because there is no constitutional or statutory limit on buying commercially available data.

In other words, U.S. spy agencies can keep buying data on Americans that is readily available for purchase until Congress puts a stop to the practice — even if the root of the problem is that data brokers shouldn’t have our data to begin with.

You can now make your own custom Copilot GPT. Here’s how

Custom Copilot GPTs

In the era of AI chatbots, there are plenty of ready-to-use chatbots on the market that offer a range of functions. However, if the particular task you want to use a chatbot for isn't available, you can now easily create your own chatbot in Copilot Pro.

As first spotted by X user Paul Couvert, Microsoft quietly added a new "Custom Copilot GPTs" feature in preview for Copilot Pro users. With the feature, Pro users can create a custom Copilot GPT with personalized instructions that can be kept private or shared so that both free and paying Copilot users can use it.

Also: I tried Copilot Notebook: Microsoft's new AI tool offers two handy prompt features

Getting started is simple. Go to your Copilot Pro homepage and click on the "See all Copilot GPTs" option on the right-hand side of the page, under all of Microsoft's custom Copilots.

The first option at the top is "Create a new Copilot GPT" with a preview designation that reads "Use the configure or create tool to create a custom Copilot GPT that you can keep private or share."

After that, the next steps for creating the chatbot are very similar to the steps for creating a custom chatbot on ChatGPT, which also requires no coding or technical savviness — as you can see in ZDNET's step-by-step instructions. On ChatGPT, the feature is also limited to its premium tier ChatGPT Plus subscribers.

If you have never created a custom GPT, no worries. Microsoft includes a thorough list of tips for creating a quality Copilot GPT with notes such as keeping the name short and catchy, using clear language, making prompts specific and actionable, and more.

As you follow the tips, the builder will continue to ask you follow-up questions that make creating your chatbot an intuitive process.

Also: How to use Copilot Pro AI to finetune your presentations in PowerPoint

A good first step is to name your chatbot and then follow up by describing the chatbot's purpose. For this article, I decided to create a chatbot that automatically transforms all of your text into the tone of a Shakespearean play.

As a result, I named the chatbot "Shakespeare tone" and followed it up with the description, "Your job is to transform all user input text to have the tone and language of a Shakespearean play."

As seen in the screenshot above, the builder understood the task immediately and followed up with more questions about how I wanted the chatbot to behave, including what topics it should emphasize or avoid. To facilitate the creation process, Microsoft even includes sample prompts you can click on to continue the process.

Once I had answered all of the basic follow-up questions for setting up the chatbot, the builder let me know the chatbot was completed and that I could preview it by clicking the "Preview Copilot GPT" button in the top right corner.

I tested it by entering the sentence, "The Yorkie puppy stood by the door anxiously awaiting for his owner to return from his errands." The chatbot responded with an intricate three-paragraph passage in the tone of Shakespeare, as instructed, as seen in the image below.

Once you preview it, you can go back and tweak the chatbot further or publish it. When publishing, you have the option to share the link with everyone or keep it for yourself. It's that easy.

Also: I fell under the spell of an AI psychologist. Then things got a little weird

The perk of having a custom chatbot is that it circumvents having to enter elaborate instructions every time you want a specific function done. For example, I was able to bypass instructing ChatGPT with the exact parameters I wanted and instead could simply type the sentence I wanted transformed.

Therefore, if you use Copilot Pro or ChatGPT for a repetitive task in your personal life or workflow, it will save you time — in the long run — to take a few minutes to set up your custom GPT.

Artificial Intelligence