How Gradient-Boosting is Quietly Powering India’s Research Push

In its push to meet ambitious sustainable development goals, from ensuring access to clean water and building resilient infrastructure to protecting biodiversity, India is increasingly turning to data and artificial intelligence.

However, the spotlight is not on conversational or generative models. As climate pressures intensify, researchers require AI systems that can interpret environmental data responsibly, without demanding supercomputer-scale resources or relying on opaque logic. This is where gradient-boosting models are gaining traction.

These models are quietly powering analyses across hydrology, ecology, geology, agriculture and urban planning. They work particularly well with real-world environmental data, offer transparent explanations, and run efficiently on standard research hardware. This approach resonates not only in India but also across the broader BRICS scientific community, where researchers prioritise open, interpretable tools designed to address practical challenges.

One notable example is CatBoost, the open-source gradient-boosting library developed at Yandex. Its ability to handle tabular environmental data, from pollution categories to terrain labels, has made it useful for Indian research groups studying river contamination, slope stability and carbon storage. Instead of spending weeks cleaning datasets, scientists can focus on identifying patterns and communicating evidence to policymakers.

In sustainability research, where predictions must be traceable and defensible, efficiency matters as much as accuracy.

Across Indian laboratories, boosting models are not substituting scientific judgement. Instead, they help researchers turn messy environmental data into reliable insights. This article examines how these methods are shaping India’s research landscape, the practical benefits they offer, and how they support the country’s sustainability mission.

What Is Gradient Boosting

Gradient boosting is a machine-learning method that builds a sequence of models, with each new model correcting the errors of the previous one.

Unlike large neural networks that require significant computing resources, gradient boosting can run on standard laboratory machines while still delivering accurate and explainable results. This makes it a practical choice for scientific and sustainability research.

Researchers can identify the factors influencing predictions, for example, why a model forecast pollution in a specific river stretch or flagged a slope as potentially unstable. This interpretability makes boosting methods well-suited for environmental, social and governance (ESG) research, where traceability, reproducibility and transparent assumptions are essential.

CatBoost offers an additional advantage. It can handle categorical features such as land-use labels, crop classifications and pollutant codes without extensive preprocessing. This removes a significant portion of the manual work that scientists would otherwise need to perform.

Given that categorisation is often where environmental datasets become inconsistent or messy, reducing this burden lowers the barrier to scientific modelling. In doing so, CatBoost reflects a broader BRICS approach to innovation — developing practical tools to address real-world problems such as floods, pollution, urban expansion, and biodiversity loss.

How India Is Using Boosting for Environmental Research

India has no shortage of data on flooding, pollution, slope failures and urban impacts. The challenge lies in converting that information into decisions that protect people and ecosystems.

Below are three examples showing how researchers are applying boosting methods to issues central to India’s development and sustainability agenda.

India’s rivers face a dual challenge: unpredictable monsoons and widespread pollution. Monitoring and predicting water quality is a classic “messy data” problem, involving numerous interacting physical, chemical and biological factors, high spatial variation and firm seasonal shifts. Gradient-boosting models are well-suited to convert such complex datasets into actionable insights.

Researchers working in the Godavari River Basin have applied boosting algorithms to downscale global climate models to produce regional rainfall and temperature projections. This has led to more accurate flood forecasts and improved irrigation planning, according to a study published in the Journal of Hydrology: Regional Studies in 2025.

Water-quality researchers have also adopted these techniques. A study published in Scientific Reports in 2025 used a stacked ensemble of models, including CatBoost and XGBoost, to predict the Water Quality Index (WQI) across major Indian rivers between 2005 and 2014.

The models achieved strong predictive accuracy, with an R² value of around 0.995. This enabled researchers to prioritise sampling locations and detect emerging pollution hotspots earlier than would be possible with traditional laboratory testing alone.

The combination of predictive performance and transparency supports better water-risk management, faster identification of contamination zones and more decisive regulatory action.

Civil Engineering

As cities expand into steep and geologically fragile terrain, India faces a rising risk of landslides and slope failures, particularly during the monsoon season. Boosting models are helping engineers anticipate and mitigate these risks.

Although a recent CatBoost-based slope-stability study was conducted outside India, the methodology closely mirrors the challenges found across the Himalayas, the Western Ghats and other vulnerable regions.

Published in Scientific Reports in 2024, the study demonstrated that CatBoost could generate early warnings of potential landslides by learning from soil properties, terrain features and rainfall patterns. Indian researchers are now exploring similar approaches for local conditions.

Such predictive modelling allows planners to reinforce slopes, design safer highways and integrate risk-aware decisions into urban development, shifting engineering practices from reactive mitigation to proactive safety.

Ecology and Sustainability

Tracking forest growth, biomass and carbon sequestration is central to India’s biodiversity and climate-action goals. Gradient-boosting models are increasingly used to combine satellite imagery with field measurements to estimate ecosystem productivity.

A 2025 Scientific Reports study from China showed that CatBoost could estimate gross primary productivity (GPP) with high accuracy using multisource satellite data and environmental variables, achieving an R² value of 0.890.

While the research focused on Shanxi province, the modelling approach — combining vegetation indices, climate data and boosting algorithms — closely aligns with the challenges faced by India’s forest-monitoring and carbon-mapping programmes.

By translating diverse ecological datasets into practical guidance, boosting models can help Indian researchers identify restoration priorities, monitor changes in carbon sinks and support evidence-based conservation policies more efficiently than traditional methods.

Why Gradient Boosting Matters for India’s ESG Goals

Meeting India’s sustainability targets — including net-zero emissions by 2070, ecosystem restoration, clean water access, resilient infrastructure and biodiversity protection — requires solutions that are effective, affordable and transparent.

Gradient-boosting models, particularly tools such as CatBoost, align closely with these needs.

They work well with heterogeneous scientific data, including soil types, rainfall categories and land-use classes. They require significantly less computing power than deep-learning models for tabular datasets, making them accessible to universities and research labs with limited resources. Their interpretable outputs allow scientists to validate findings rather than relying on black-box predictions.

Importantly, these models also enable closer collaboration between domain experts, data scientists and policymakers, allowing AI tools to be co-designed and directly integrated into planning systems.

In short, gradient boosting makes applied AI practical, scalable and trustworthy — qualities essential for advancing India’s sustainability mission.

Gradient boosting may never command the attention of generative AI models, but its impact on real-world challenges is substantial. In India, these methods are helping to support cleaner rivers, safer infrastructure, more innovative water management, and healthier forests.

CatBoost and similar tools demonstrate that “AI for good” does not require massive models or vast computing resources. Instead, it often depends on efficient, open-source systems that scientists and policymakers can deploy, audit and trust.

As India accelerates its sustainability and infrastructure ambitions, gradient boosting, supported by an expanding open-data ecosystem, is quietly powering a green research revolution.

The post How Gradient-Boosting is Quietly Powering India’s Research Push appeared first on Analytics India Magazine.

How Gradient-Boosting is Quietly Powering India’s Research Push

In its push to meet ambitious sustainable development goals, from ensuring access to clean water and building resilient infrastructure to protecting biodiversity, India is increasingly turning to data and artificial intelligence.

However, the spotlight is not on conversational or generative models. As climate pressures intensify, researchers require AI systems that can interpret environmental data responsibly, without demanding supercomputer-scale resources or relying on opaque logic. This is where gradient-boosting models are gaining traction.

These models are quietly powering analyses across hydrology, ecology, geology, agriculture and urban planning. They work particularly well with real-world environmental data, offer transparent explanations, and run efficiently on standard research hardware. This approach resonates not only in India but also across the broader BRICS scientific community, where researchers prioritise open, interpretable tools designed to address practical challenges.

One notable example is CatBoost, the open-source gradient-boosting library developed at Yandex. Its ability to handle tabular environmental data, from pollution categories to terrain labels, has made it useful for Indian research groups studying river contamination, slope stability and carbon storage. Instead of spending weeks cleaning datasets, scientists can focus on identifying patterns and communicating evidence to policymakers.

In sustainability research, where predictions must be traceable and defensible, efficiency matters as much as accuracy.

Across Indian laboratories, boosting models are not substituting scientific judgement. Instead, they help researchers turn messy environmental data into reliable insights. This article examines how these methods are shaping India’s research landscape, the practical benefits they offer, and how they support the country’s sustainability mission.

What Is Gradient Boosting

Gradient boosting is a machine-learning method that builds a sequence of models, with each new model correcting the errors of the previous one.

Unlike large neural networks that require significant computing resources, gradient boosting can run on standard laboratory machines while still delivering accurate and explainable results. This makes it a practical choice for scientific and sustainability research.

Researchers can identify the factors influencing predictions, for example, why a model forecast pollution in a specific river stretch or flagged a slope as potentially unstable. This interpretability makes boosting methods well-suited for environmental, social and governance (ESG) research, where traceability, reproducibility and transparent assumptions are essential.

CatBoost offers an additional advantage. It can handle categorical features such as land-use labels, crop classifications and pollutant codes without extensive preprocessing. This removes a significant portion of the manual work that scientists would otherwise need to perform.

Given that categorisation is often where environmental datasets become inconsistent or messy, reducing this burden lowers the barrier to scientific modelling. In doing so, CatBoost reflects a broader BRICS approach to innovation — developing practical tools to address real-world problems such as floods, pollution, urban expansion, and biodiversity loss.

How India Is Using Boosting for Environmental Research

India has no shortage of data on flooding, pollution, slope failures and urban impacts. The challenge lies in converting that information into decisions that protect people and ecosystems.

Below are three examples showing how researchers are applying boosting methods to issues central to India’s development and sustainability agenda.

India’s rivers face a dual challenge: unpredictable monsoons and widespread pollution. Monitoring and predicting water quality is a classic “messy data” problem, involving numerous interacting physical, chemical and biological factors, high spatial variation and firm seasonal shifts. Gradient-boosting models are well-suited to convert such complex datasets into actionable insights.

Researchers working in the Godavari River Basin have applied boosting algorithms to downscale global climate models to produce regional rainfall and temperature projections. This has led to more accurate flood forecasts and improved irrigation planning, according to a study published in the Journal of Hydrology: Regional Studies in 2025.

Water-quality researchers have also adopted these techniques. A study published in Scientific Reports in 2025 used a stacked ensemble of models, including CatBoost and XGBoost, to predict the Water Quality Index (WQI) across major Indian rivers between 2005 and 2014.

The models achieved strong predictive accuracy, with an R² value of around 0.995. This enabled researchers to prioritise sampling locations and detect emerging pollution hotspots earlier than would be possible with traditional laboratory testing alone.

The combination of predictive performance and transparency supports better water-risk management, faster identification of contamination zones and more decisive regulatory action.

Civil Engineering

As cities expand into steep and geologically fragile terrain, India faces a rising risk of landslides and slope failures, particularly during the monsoon season. Boosting models are helping engineers anticipate and mitigate these risks.

Although a recent CatBoost-based slope-stability study was conducted outside India, the methodology closely mirrors the challenges found across the Himalayas, the Western Ghats and other vulnerable regions.

Published in Scientific Reports in 2024, the study demonstrated that CatBoost could generate early warnings of potential landslides by learning from soil properties, terrain features and rainfall patterns. Indian researchers are now exploring similar approaches for local conditions.

Such predictive modelling allows planners to reinforce slopes, design safer highways and integrate risk-aware decisions into urban development, shifting engineering practices from reactive mitigation to proactive safety.

Ecology and Sustainability

Tracking forest growth, biomass and carbon sequestration is central to India’s biodiversity and climate-action goals. Gradient-boosting models are increasingly used to combine satellite imagery with field measurements to estimate ecosystem productivity.

A 2025 Scientific Reports study from China showed that CatBoost could estimate gross primary productivity (GPP) with high accuracy using multisource satellite data and environmental variables, achieving an R² value of 0.890.

While the research focused on Shanxi province, the modelling approach — combining vegetation indices, climate data and boosting algorithms — closely aligns with the challenges faced by India’s forest-monitoring and carbon-mapping programmes.

By translating diverse ecological datasets into practical guidance, boosting models can help Indian researchers identify restoration priorities, monitor changes in carbon sinks and support evidence-based conservation policies more efficiently than traditional methods.

Why Gradient Boosting Matters for India’s ESG Goals

Meeting India’s sustainability targets — including net-zero emissions by 2070, ecosystem restoration, clean water access, resilient infrastructure and biodiversity protection — requires solutions that are effective, affordable and transparent.

Gradient-boosting models, particularly tools such as CatBoost, align closely with these needs.

They work well with heterogeneous scientific data, including soil types, rainfall categories and land-use classes. They require significantly less computing power than deep-learning models for tabular datasets, making them accessible to universities and research labs with limited resources. Their interpretable outputs allow scientists to validate findings rather than relying on black-box predictions.

Importantly, these models also enable closer collaboration between domain experts, data scientists and policymakers, allowing AI tools to be co-designed and directly integrated into planning systems.

In short, gradient boosting makes applied AI practical, scalable and trustworthy — qualities essential for advancing India’s sustainability mission.

Gradient boosting may never command the attention of generative AI models, but its impact on real-world challenges is substantial. In India, these methods are helping to support cleaner rivers, safer infrastructure, more innovative water management, and healthier forests.

CatBoost and similar tools demonstrate that “AI for good” does not require massive models or vast computing resources. Instead, it often depends on efficient, open-source systems that scientists and policymakers can deploy, audit and trust.

As India accelerates its sustainability and infrastructure ambitions, gradient boosting, supported by an expanding open-data ecosystem, is quietly powering a green research revolution.

The post How Gradient-Boosting is Quietly Powering India’s Research Push appeared first on Analytics India Magazine.

Google’s Try-On Feature: Good for Indian D2C Growth or Just Another Tool?

Virtual outfit try-ons have become the modern equivalent of window shopping. Many online retailers find them helpful in reducing return rates and enhancing customer experience.

But they are not a new phenomenon.

One of the earliest examples of virtual try-on technology was Webcam Social Shopper, launched in June 2009 by Zugara, a US-based augmented reality (AR) company. It harnessed webcams and enabled shoppers to ‘try’ clothes by digitally placing them on their live video feeds.

Cut to December 2025, and the virtual try-on landscape looks vastly different, thanks to AI.

Google’s new “try it on” feature, which recently entered India, allows shoppers to upload a full-body photo and see apparel from billions of listings realistically mapped onto their bodies. Available under the Shopping Graph for apparel products, its AI model enables shoppers not only to upload full-body pictures but also to try on clothes using just a selfie. It is integrated across Search, Google Shopping, and Google Images.

“Now, if you don’t have a full body photo of yourself, you can use a selfie and Nano Banana, our Gemini 2.5 Flash Image model, will generate a full body digital version of you for virtual try on,” Lilian Rincon, VP of product and consumer shopping at Google, said in a blog.

The feature was launched in the US in July 2025 and is an upgrade of an earlier virtual try-on feature that focused on showing apparel on a diverse range of models. It also launched the Doppl app in December, specifically for virtual try-ons.

The question is: how different is Google’s offering from existing try-on tools, and do we really need another one in the space?

Stand Out Tech

Earlier tools from fashion and beauty brands typically worked only within a single retailer’s app and relied on basic AR filters or preset avatars. Google’s system is vastly different.

It analyses the shopper’s full-body or selfie photo to detect body shape, pose, and landmarks such as shoulders, waist, and legs, and processes them on-device or in controlled environments for privacy. At the same time, it studies retailer product images to interpret garment cut, proportions, and how fabrics drape, fold, and stretch.

Jaspreet Bindra, Co-founder of experiential learning platform AI&Beyond, said the feature marks an important shift from catalogue-style visualisation to AI-driven realism.

“Unlike most existing e-commerce try-on tools that rely on static overlays, limited mannequins or heavily stylised avatars, Google’s approach uses generative AI to simulate how garments behave on diverse human forms, factoring in drape, stretch and proportion. The biggest USP here is scale and intelligence—Google is not just building a feature, but a learning system that improves with data across brands, categories and geographies,” he told AIM.

For Indian shoppers, many of whom remain hesitant to buy apparel online, the feature helps build trust. They can experiment with looks, share outfits with friends, and recreate a fitting room-like experience. Ankush Acharya, a 35-year-old marketing professional, found the tool quite accurate. “It came really close to capturing the overall fit and style of shirts. It even changed my pants and shoes to better match the product.”

What Works, What Doesn’t

As Google integrates try-on directly into search listings, users can try items from multiple brands, compare fit instantly, and discover products faster. Its Nano Banana generative AI model uses diffusion for high-quality image editing to show how fabrics fold, clothes stretch, textures react to lighting, and garments behave across body types. Unlike AR tools that need 3D assets, Google requires only 2D catalogue images, reducing friction for brands and marketplaces.

However, the feature has limitations. AI-generated previews often struggle with complex patterns, multi-layered outfits, or nuanced fabric behaviour, leading to approximations rather than perfect simulations. Acharya also noticed a glitch when trying on a shirt. “It was a little more slim-cut than it was supposed to be,” he observed.

It also does not provide size recommendations, stock checks, or guarantees of real-world accuracy, which doesn’t encourage high-value purchases.

“AI still struggles with real-world complexity. Fabric physics, lighting variations, body posture and individual fit preferences are hard to perfectly model, which means virtual try-on will remain probabilistic rather than precise. These tools reduce uncertainty, not eliminate it. Long-term viability will depend on how seamlessly they integrate into discovery and decision journeys, rather than being novelty add-ons,” Bindra explained.

Variety is another constraint. Google’s tool currently supports tops, bottoms, dresses, jackets and shoes, but leaves out lingerie, bathing suits/swimsuits, accessories (other than sometimes on diverse models), costumes, and traditional/religious wear.

The feature, powered by Search Labs, is limited to 18+ users in the US. Rendering times of 10–15 seconds per outfit also slow down the experience. Moreover, as the tool runs on Google’s platform rather than retailer websites, brands have little control over data, analytics, or shopper behaviour insights.

Privacy concerns loom large. Camera access raises fear of misuse, and earlier versions reportedly produced inappropriate alterations such as body enhancement effects or accessories. While Google did not participate in the story, a spokesperson earlier told CNET, “Your uploaded photo is never used beyond trying things on virtually, nor is your photo used for training purposes. It is not shared with other Google products, services or third parties, and you can delete or replace it at any time.”

But data quality remains critical. “While Google has made progress on representing diverse body types, true inclusivity requires continuous, region-specific data inputs, especially in markets like India, where body morphology and clothing styles vary significantly,” Bindra said.

Also, the proposed AI licensing and copyright guidelines from the Department for Promotion of Industry and Internal Trade (DPIIT) threaten to create a regulatory rigamarole for Google using catalogues from Indian brands.

“On regulation, frameworks such as the proposed DPIIT guidelines should ideally enable trust and transparency without stifling innovation. If designed thoughtfully, they can actually strengthen adoption by setting clear guardrails rather than caging the technology for Indian users,” he added.

Just Another Tool?

Meanwhile, Indian brands have been experimenting with their own virtual try-on tools. Nykaa launched India’s first major virtual try-on for makeup in December 2021, using L’Oréal’s ModiFace. Myntra introduced its “Looks Virtual Try-On” in late 2024, and Lenskart innovated with its 3D eyewear try-on after partnering with US startup Ditto. There’s also Myntra Style Studio and Flipkart’s Fit Finder.

Internationally, Sephora’s Virtual Artist and Warby Parker’s eyewear try-on have been early innovators. Walmart introduced AI-powered apparel try-on in 2022, later upgrading it to support customer photos. Amazon’s virtual try-on, meanwhile, is far more practical for categories like shoes and eyewear because of its real-time AR approach.

These tools are expected to make an impact on India’s booming e-commerce apparel market, projected to hit $98.5 billion by 2032, according to a CoherentMi study. For merchants, the feature may help reduce returns—apparel has some of the highest return rates (35–40% as per a 2024 Return Prime report) due to poor fit expectations. The tools can also help D2C brands without brick-and-mortar stores seeking higher conversions and lower expenses by cutting photoshoot costs. But that can only happen once Indian brands come aboard.

The post Google’s Try-On Feature: Good for Indian D2C Growth or Just Another Tool? appeared first on Analytics India Magazine.

ServiceNow to Buy Armis for $7.75 Billion

ServiceNowServiceNow

ServiceNow is set to acquire cyber exposure management firm Armis for approximately $7.75 billion in cash, as the company looks to deepen its presence in cybersecurity across IT, operational technology (OT), medical devices, and other cyber-physical environments.

​The acquisition is expected to expand ServiceNow’s security workflow offerings and accelerate its push toward AI-native, proactive, and autonomous cybersecurity, according to a release.

​The transaction is slated to close in the second half of 2026, subject to regulatory approvals and customary closing conditions.

​Armis, founded in 2015, specialises in cyber exposure management and cyber-physical security, offering real-time, agentless discovery and risk prioritisation across managed and unmanaged assets, including OT, IoT, medical, and industrial devices.

Its platform is used by Global 2000 enterprises, more than 35% of the Fortune 100, and public-sector organisations worldwide, according to the release.

​ServiceNow said the combination will create a unified, end-to-end security exposure and operations stack that can “see, decide, and act” across an organisation’s entire technology footprint.

By integrating Armis’ real-time asset discovery, threat intelligence, and risk prioritisation with ServiceNow’s automated remediation and response workflows, the company aims to offer customers a single, AI-driven platform for managing cyber risk.

Amit Zavery, president, chief operating officer and chief product officer at ServiceNow, said in a statement, “In the agentic AI era, intelligent trust and governance that span any cloud, any asset, any AI system, and any device are non-negotiable if companies want to scale AI for the long-term. Together with Armis, we will deliver an industry-defining strategic cybersecurity shield for real-time, end-to-end proactive protection across all technology estates.”

​The deal comes amid rising enterprise spending on cybersecurity as AI adoption expands the attack surface.

ServiceNow noted that worldwide end-user spending on information security is projected to reach $240 billion in 2026, driven by rising threats and the growing use of AI, including generative AI.

The company’s security and risk business crossed $1 billion in annual contract value in the third quarter of 2025, it informed.

​ServiceNow said the acquisition is expected to more than triple its market opportunity for security and risk solutions and accelerate its roadmap to autonomous, proactive cybersecurity.

​Armis co-founder and CEO Yevgeny Dibrov said the threat landscape is evolving faster than many organisations can respond.

“AI is transforming the threat landscape faster than most organisations can adapt. Every connected asset has become a potential point of vulnerability,” he said.

“We built Armis to protect the most critical environments and give both public and private sector organisations the real-time intelligence they need to stay ahead—so they can see their entire environment clearly, understand risk in context, and take action before an incident occurs.”

​The companies have been longtime partners and already offer multiple integrations that link Armis’ data and insights with ServiceNow workflows.

Following the acquisition, Armis’ capabilities will be integrated with the ServiceNow AI Control Tower, which governs and manages AI across the enterprise, and with ServiceNow’s configuration management database, providing business context for assets and exposures.

​Armis reported more than $340 million in annual recurring revenue, with year-over-year ARR growth exceeding 50%, ServiceNow said. The company employs around 950 people.

​Under the terms of the definitive agreement, ServiceNow will fund the transaction through a combination of cash on hand and debt.

The post ServiceNow to Buy Armis for $7.75 Billion appeared first on Analytics India Magazine.

Coforge Launches EvolveOps.AI, an Agentic AI-Powered IT Operations Platform

Coforge has launched EvolveOps.AI, an agentic AI-powered IT operations management platform to help enterprises prepare for an AI-first era and improve business resiliency from the edge to the cloud.

The platform is built to deliver end-to-end autonomous operations across the lifecycle of enterprise systems running on hybrid cloud environments, the company said in a release.

EvolveOps.AI leverages purpose-built hybrid cloud architecture and agentic operations to drive agility, resilience and large-scale transformation.

Coforge said EvolveOps.AI is designed to amplify enterprises’ existing investments in observability, data fabric and automation platforms, accelerating the transition toward agentic AI-powered operations.

Built entirely on open-source technologies, the platform can be deployed rapidly using a repository of pre-built adapters and plug-ins, a fine-tuned, purpose-built small language model (SLM), and agentic AI resolver personas that can autonomously manage IT operations.

By applying AI and machine learning across a unified data fabric for technology operations, the platform aims to reduce operational noise, speed up incident lifecycle management and improve the reliability of mission-critical systems.

The tier-2 company claimed that enterprises using EvolveOps.AI have recorded a 25% reduction in system downtime, a 40% reduction in IT operational expenses, a 60% reduction in mean time to detection and resolution, and a 40% faster time to market for products.

“Our strategy for cloud and infrastructure is anchored in Mission Zero—Zero Disruption, Zero Touch, Zero Friction—for every cloud transformation we execute,” said Ashish Kumar, global business unit head – cloud, AI-infra, security and ServiceNow at Coforge, said in a statement.

“With EvolveOps.AI, we are operationalising that mission by infusing AI agents into every stage of the technology operations lifecycle. The platform helps our clients shift from reactive firefighting to proactive, autonomous operations, delivering higher resilience, improved developer productivity, and a superior experience for business users and customers,” he added

At the core of EvolveOps.AI is a combination of fine-tuned SLMs and deterministic models, which the company says delivers faster time-to-value while significantly reducing the cost to serve.

The company has developed 28 agentic personas so far, spanning roles such as site reliability engineering, infrastructure and cloud engineering, network engineering, Kubernetes engineering, command center engineering, service management, and FinOps.

These agentic personas are designed to analyse, reason, decide and act across complex IT scenarios.

The platform also incorporates enterprise-grade guardrails that allow organisations to switch between human-in-the-loop operations and fully autonomous modes, depending on governance and risk requirements.

EvolveOps.AI has been architected to integrate with major hyperscalers and leading IT operations management platforms.

Its Hybrid Cloud Manager module supports full-stack builds and policy-driven automation across Amazon Web Services, Microsoft Azure, Google Cloud Platform, Oracle Cloud Infrastructure, and private cloud environments. It also integrates with a broad ecosystem of observability, IT service management, security and automation tools.

According to the company, this approach allows enterprises to adopt autonomous operations without disrupting their existing technology landscapes, while standardising governance, FinOps and reliability practices across multi-cloud estates.

The post Coforge Launches EvolveOps.AI, an Agentic AI-Powered IT Operations Platform appeared first on Analytics India Magazine.

The AI Coding Gold Rush Ends Where Harness Begins

The AI Coding Gold Rush Ends Where Harness BeginsThe AI Coding Gold Rush Ends Where Harness Begins

On a bright afternoon in Bengaluru’s HSR Layout, where AI startups bloom faster than cafés and ambition hums louder than traffic, Harness, the AI-native software delivery platform, was turning demos into products overnight.

Today, platforms like Replit, Lovable, and the new generation of AI developer tools can spin up features in minutes, including Indian alternatives like Emergent, Rocket, and others. These so-called vibe-coding tools or code-automation platforms have radically transformed the first 30-40% of software development.
At Harness’s Bengaluru office, where meeting rooms are named after cult films, series, and games, the company hosted its inaugural developer community event, AI Connect, focusing on solving complex software challenges. This phase—the often messy, unseen, and unglamorous 60-70% of the software lifecycle—is where Harness operates. It involves testing, securing, governing, verifying, deploying, rolling back, auditing, and building trust in code. This is the part that AI demos rarely address, yet enterprises cannot afford to overlook it.

“Only 30% of software engineering happens on the laptop. The real 70% starts after you code,” says Jyoti Bansal with disarming clarity.

Harness recently raised a $240 million Series E round, valuing the company at $5.5 billion. Bansal has already built and exited a unicorn before, the likes of AppDynamics, which got acquired by Cisco in 2017.

Bansal shrugs off the label, perhaps a reflex born from growing up in a small town in Rajasthan’s Jaisalmer. He quips the “billionaire founder” mould and rejects the performative glamour around it. “That’s not what drives me,” he said. “Labels don’t build companies. Obsession with solving real problems does.”
In 2025, the company reportedly reached $250 million in Annual Recurring Revenue (ARR), showing 50% year-over-year growth, and has expanded its workforce to 1,200 employees operating out of 14 offices globally.

Check out the full conversation exclusively on Front Page by AIM Network.

By combining specialised AI agents, deep organisational context, and reliable orchestration, the platform turns software delivery workflows into an intelligent system that learns, adapts, and acts on behalf of engineering teams.

“Agents are easy to demo. The hard part is making agents that actually work for a real bank or airline,” Bansal said.

When asked if AI agents are killing SaaS faster than ever, Bansal added that he doesn’t believe the narrative.

Building Advanced AI Systems

A few kilometres from where dozens of early-stage AI startups are prototyping the future in Bengaluru, Harness is expanding, anchoring its work in generative AI for software delivery, intelligent testing, secure DevOps automation, platform intelligence, cloud optimisation and modern resilience systems.

“India is taking on an increasingly strategic role as a major hub for the innovations that shape Harness’s long-term platform vision,” said Bansal.

Head of R&D India, Prashant Verma, puts it even more plainly: “We’re building one of the world’s most advanced AI engineering ecosystems right here in India.”

But the infrastructure ambition is matched by culture. Harness behaves like a federation of founders. “We run Harness like 15 startups inside one company,” said Bansal.

Harnessing Enterprises Ambitions

The company states it has powered 128 million deployments, executed 81 million builds, safeguarded 1.2 trillion API calls, and assisted organisations in optimising over $1.9 billion in cloud expenses.

Harness said, its enterprise customer, United Airlines, sped up deployment by 75% and migrated 80% of workloads to the cloud; Morningstar reduced 36,000 pipelines to 50 templates; Citibank cut release cycles from weeks to minutes; Keller Williams increased deployment six-fold; National Australia Bank cut build times by 67% and improved troubleshooting by 85%.

Harness told AIM that it will eventually go public. His previous company was minutes away from ringing the bell before Cisco acquired it.

Bansal insists that the IPO is an outcome, not an obsession. The real mission, however, he said, is to build a world where everything after code, testing, governance, reliability, deployment, security, cost and resilience, becomes as automated, intelligent and dependable as the AI that now writes the code itself.

“If you’re a software engineer and you’re not great at using AI and agents, your job is at risk,” Bansal said, reflecting the urgency of that shift. However, he clarified that Harness is not replacing engineers, but is future-proofing them.

Platforms like Replit and Lovable keep pushing the pace at which code can be created. AI will continue to compress the creativity cycle, and Harness is building for that checkpoint.

The post The AI Coding Gold Rush Ends Where Harness Begins appeared first on Analytics India Magazine.

Dell, NVIDIA to Host AI Developer Meetup in Hyderabad

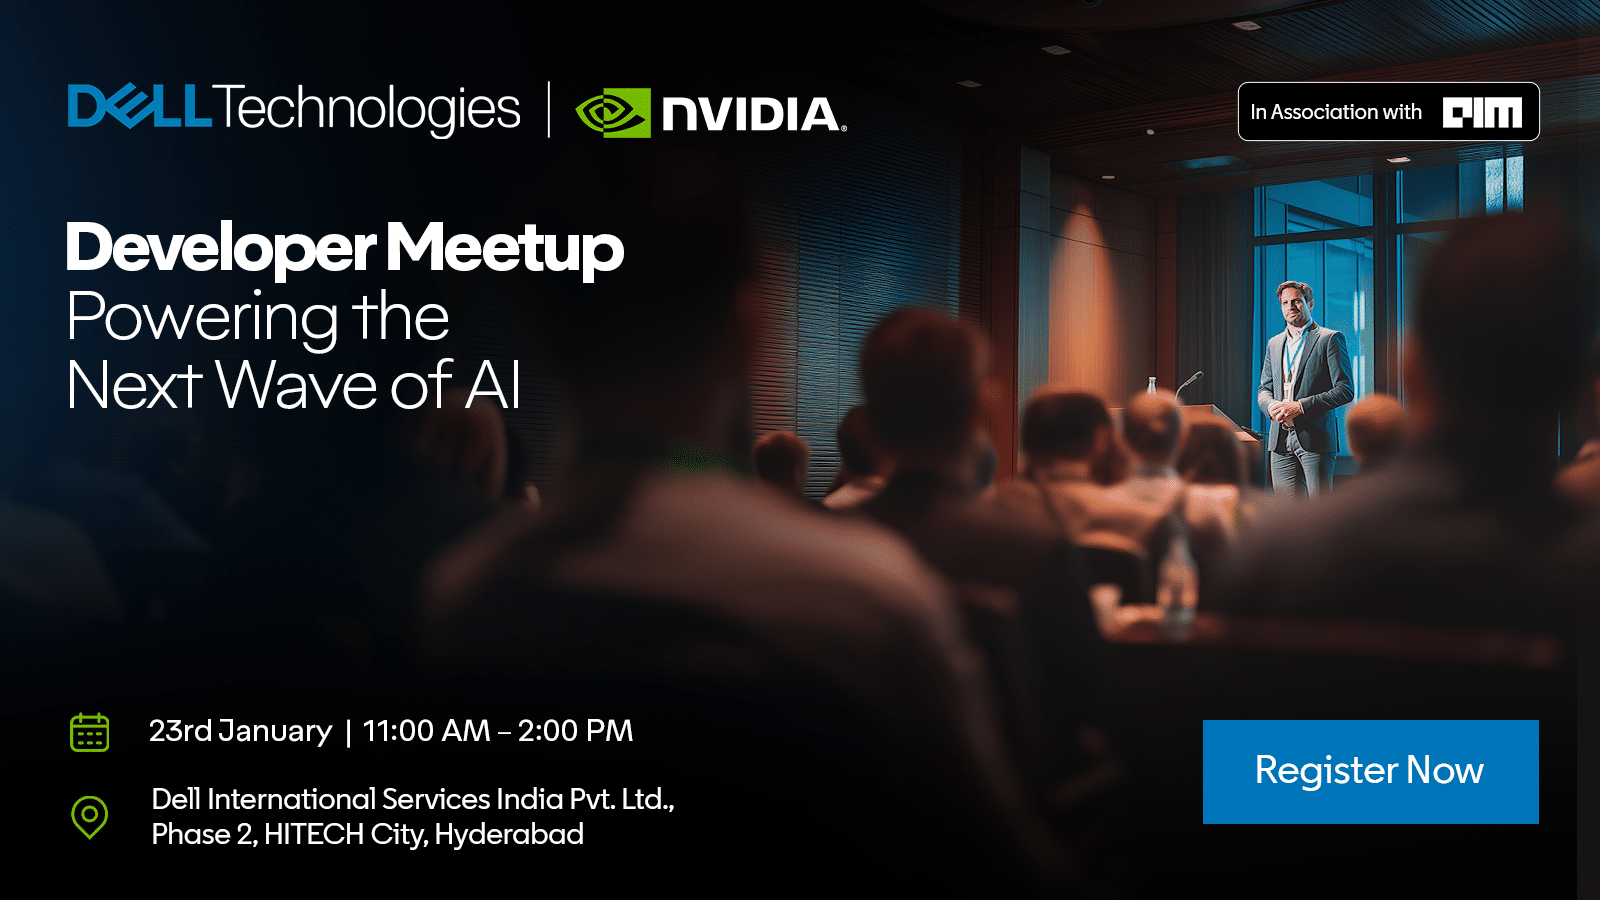
A new developer meetup, powered by two global technology leaders — Dell Technologies and NVIDIA — is coming to Hyderabad.

The event, called ‘Dell x NVIDIA Developer Meetup: Powering the Next Wave of AI’, is aimed at engineers and enterprise teams building AI systems that must perform outside controlled demos.

As organisations move beyond experiments, the pressure is shifting to execution. Developers are now wrestling with questions of infrastructure fit, performance bottlenecks, and workflow design.

The focus is less on accessing models and more on how AI is built, tested, and operated across local environments, edge deployments, and production systems with real constraints.

📅 Date: January 23, 2026
⏰ Time: 11:00 AM – 2:00 PM (Registration starts at 10:30 AM)
📍 Venue: Dell Technologies, Phase 2, Plot No. 42, HITEC City Layout,
Serilingampalli Revenue Mandal, Hyderabad
Register Now

The meetup, organised in association with AIM, is framed as a working forum rather than a launch event.

It is designed for practitioners who want to exchange their learnings, especially the trade-offs teams make as they move from proofs-of-concept to systems that must run reliably at scale.

Who should attend: AI engineers, data scientists, data engineers, and professionals working hands-on with AI and machine learning in production environments.

Leaders from Dell and NVIDIA will join customers and AI builders to discuss concrete problem statements, solution paths, and patterns emerging across organisations deploying AI today.

Topics will range from infrastructure choices and cost-performance balance to how developer practices are evolving alongside new hardware and platforms.

A central highlight of the event will be a live demonstration of the Dell Pro Max with GB10, a compact, developer-focused AI system.

The session is intended to show how local AI development and inference can be approached in practice, and where such systems fit within broader enterprise AI architectures.

Register Now

The agenda blends context with hands-on experience. A keynote will set the stage by outlining the direction of AI infrastructure and the changing developer ecosystem.

This will be followed by customer and practitioner sessions focused on applied use cases and lessons learned from real deployments. A fireside chat and closing discussion will connect these perspectives and open the floor for broader reflection.

The meetup will conclude with a networking lunch and a hands-on product experience at the booth.

Participation is invite-only. Registrations will be screened, and confirmed invitations will be sent to selected participants.

Register Now

The post Dell, NVIDIA to Host AI Developer Meetup in Hyderabad appeared first on Analytics India Magazine.

How Gradient-Boosting is Quietly Powering India’s Research Push

In its push to meet ambitious sustainable development goals, from ensuring access to clean water and building resilient infrastructure to protecting biodiversity, India is increasingly turning to data and artificial intelligence.

However, the spotlight is not on conversational or generative models. As climate pressures intensify, researchers require AI systems that can interpret environmental data responsibly, without demanding supercomputer-scale resources or relying on opaque logic. This is where gradient-boosting models are gaining traction.

These models are quietly powering analyses across hydrology, ecology, geology, agriculture and urban planning. They work particularly well with real-world environmental data, offer transparent explanations, and run efficiently on standard research hardware. This approach resonates not only in India but also across the broader BRICS scientific community, where researchers prioritise open, interpretable tools designed to address practical challenges.

One notable example is CatBoost, the open-source gradient-boosting library developed at Yandex. Its ability to handle tabular environmental data, from pollution categories to terrain labels, has made it useful for Indian research groups studying river contamination, slope stability and carbon storage. Instead of spending weeks cleaning datasets, scientists can focus on identifying patterns and communicating evidence to policymakers.

In sustainability research, where predictions must be traceable and defensible, efficiency matters as much as accuracy.

Across Indian laboratories, boosting models are not substituting scientific judgement. Instead, they help researchers turn messy environmental data into reliable insights. This article examines how these methods are shaping India’s research landscape, the practical benefits they offer, and how they support the country’s sustainability mission.

What Is Gradient Boosting

Gradient boosting is a machine-learning method that builds a sequence of models, with each new model correcting the errors of the previous one.

Unlike large neural networks that require significant computing resources, gradient boosting can run on standard laboratory machines while still delivering accurate and explainable results. This makes it a practical choice for scientific and sustainability research.

Researchers can identify the factors influencing predictions, for example, why a model forecast pollution in a specific river stretch or flagged a slope as potentially unstable. This interpretability makes boosting methods well-suited for environmental, social and governance (ESG) research, where traceability, reproducibility and transparent assumptions are essential.

CatBoost offers an additional advantage. It can handle categorical features such as land-use labels, crop classifications and pollutant codes without extensive preprocessing. This removes a significant portion of the manual work that scientists would otherwise need to perform.

Given that categorisation is often where environmental datasets become inconsistent or messy, reducing this burden lowers the barrier to scientific modelling. In doing so, CatBoost reflects a broader BRICS approach to innovation — developing practical tools to address real-world problems such as floods, pollution, urban expansion, and biodiversity loss.

How India Is Using Boosting for Environmental Research

India has no shortage of data on flooding, pollution, slope failures and urban impacts. The challenge lies in converting that information into decisions that protect people and ecosystems.

Below are three examples showing how researchers are applying boosting methods to issues central to India’s development and sustainability agenda.

India’s rivers face a dual challenge: unpredictable monsoons and widespread pollution. Monitoring and predicting water quality is a classic “messy data” problem, involving numerous interacting physical, chemical and biological factors, high spatial variation and firm seasonal shifts. Gradient-boosting models are well-suited to convert such complex datasets into actionable insights.

Researchers working in the Godavari River Basin have applied boosting algorithms to downscale global climate models to produce regional rainfall and temperature projections. This has led to more accurate flood forecasts and improved irrigation planning, according to a study published in the Journal of Hydrology: Regional Studies in 2025.

Water-quality researchers have also adopted these techniques. A study published in Scientific Reports in 2025 used a stacked ensemble of models, including CatBoost and XGBoost, to predict the Water Quality Index (WQI) across major Indian rivers between 2005 and 2014.

The models achieved strong predictive accuracy, with an R² value of around 0.995. This enabled researchers to prioritise sampling locations and detect emerging pollution hotspots earlier than would be possible with traditional laboratory testing alone.

The combination of predictive performance and transparency supports better water-risk management, faster identification of contamination zones and more decisive regulatory action.

Civil Engineering

As cities expand into steep and geologically fragile terrain, India faces a rising risk of landslides and slope failures, particularly during the monsoon season. Boosting models are helping engineers anticipate and mitigate these risks.

Although a recent CatBoost-based slope-stability study was conducted outside India, the methodology closely mirrors the challenges found across the Himalayas, the Western Ghats and other vulnerable regions.

Published in Scientific Reports in 2024, the study demonstrated that CatBoost could generate early warnings of potential landslides by learning from soil properties, terrain features and rainfall patterns. Indian researchers are now exploring similar approaches for local conditions.

Such predictive modelling allows planners to reinforce slopes, design safer highways and integrate risk-aware decisions into urban development, shifting engineering practices from reactive mitigation to proactive safety.

Ecology and Sustainability

Tracking forest growth, biomass and carbon sequestration is central to India’s biodiversity and climate-action goals. Gradient-boosting models are increasingly used to combine satellite imagery with field measurements to estimate ecosystem productivity.

A 2025 Scientific Reports study from China showed that CatBoost could estimate gross primary productivity (GPP) with high accuracy using multisource satellite data and environmental variables, achieving an R² value of 0.890.

While the research focused on Shanxi province, the modelling approach — combining vegetation indices, climate data and boosting algorithms — closely aligns with the challenges faced by India’s forest-monitoring and carbon-mapping programmes.

By translating diverse ecological datasets into practical guidance, boosting models can help Indian researchers identify restoration priorities, monitor changes in carbon sinks and support evidence-based conservation policies more efficiently than traditional methods.

Why Gradient Boosting Matters for India’s ESG Goals

Meeting India’s sustainability targets — including net-zero emissions by 2070, ecosystem restoration, clean water access, resilient infrastructure and biodiversity protection — requires solutions that are effective, affordable and transparent.

Gradient-boosting models, particularly tools such as CatBoost, align closely with these needs.

They work well with heterogeneous scientific data, including soil types, rainfall categories and land-use classes. They require significantly less computing power than deep-learning models for tabular datasets, making them accessible to universities and research labs with limited resources. Their interpretable outputs allow scientists to validate findings rather than relying on black-box predictions.

Importantly, these models also enable closer collaboration between domain experts, data scientists and policymakers, allowing AI tools to be co-designed and directly integrated into planning systems.

In short, gradient boosting makes applied AI practical, scalable and trustworthy — qualities essential for advancing India’s sustainability mission.

Gradient boosting may never command the attention of generative AI models, but its impact on real-world challenges is substantial. In India, these methods are helping to support cleaner rivers, safer infrastructure, more innovative water management, and healthier forests.

CatBoost and similar tools demonstrate that “AI for good” does not require massive models or vast computing resources. Instead, it often depends on efficient, open-source systems that scientists and policymakers can deploy, audit and trust.

As India accelerates its sustainability and infrastructure ambitions, gradient boosting, supported by an expanding open-data ecosystem, is quietly powering a green research revolution.

The post How Gradient-Boosting is Quietly Powering India’s Research Push appeared first on Analytics India Magazine.

AIM Print December 2025

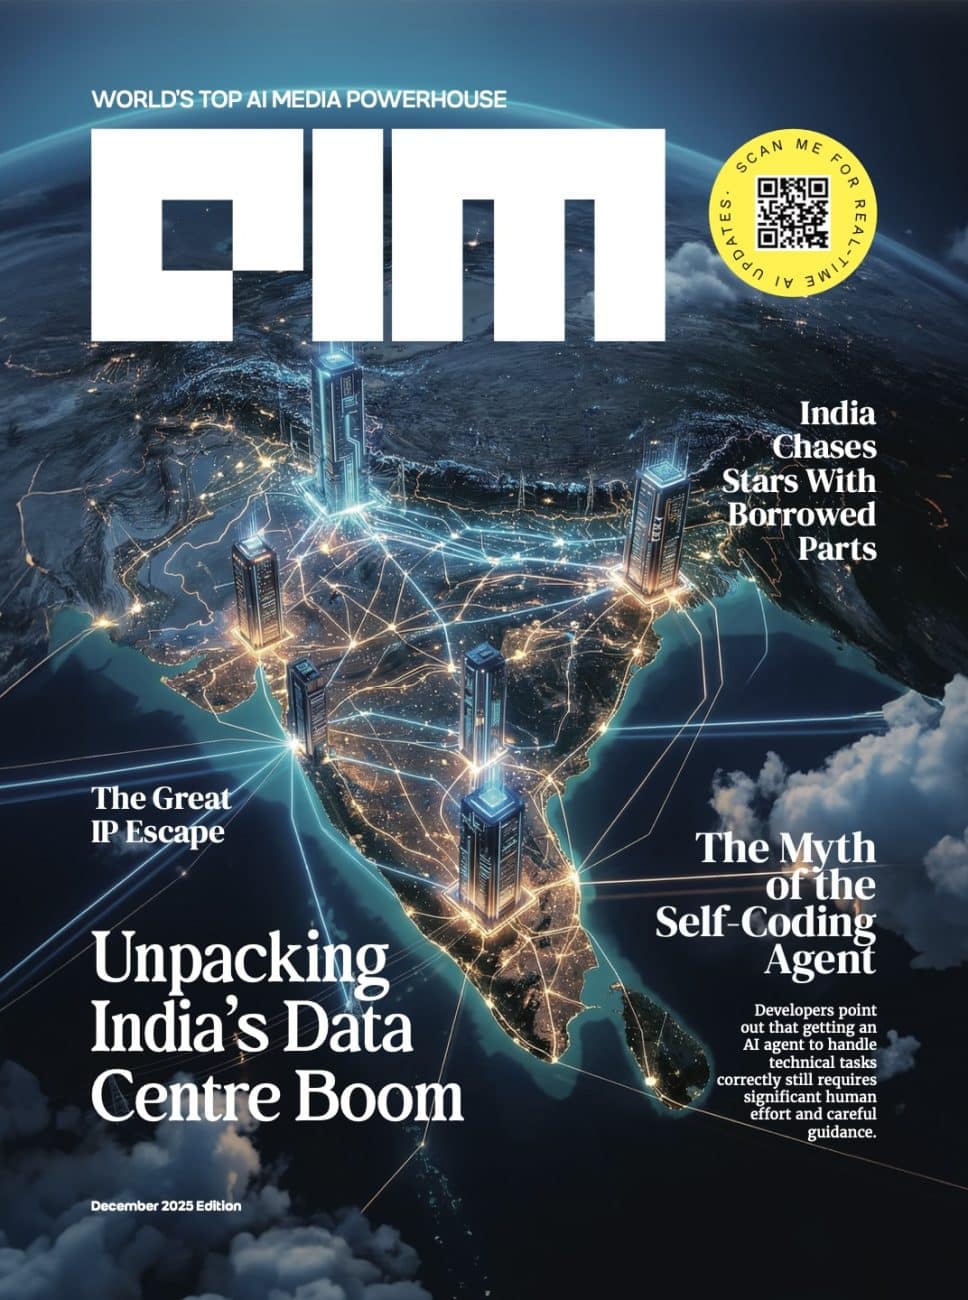
The December 2025 edition of AIM Print captures India at a defining moment in its AI and technology journey. Across data centres, global capability centres, startups, policy debates, and frontier research, the edition documents a country moving fast, but not always evenly, as it tries to convert scale and ambition into durable value.

At the centre of this edition is a recurring tension. India is generating data, talent, and experimentation at global scale, yet the systems that turn these into long-term advantage remain under strain. From infrastructure bottlenecks to governance gaps, from AI hype cycles to grounded enterprise realities, the stories in this issue examine where momentum is real and where it is still fragile.

The data centre boom and its limits

The cover story, India’s Data Centre Gold Rush, written by Supreeth Koundinya, anchors the edition. India now generates roughly 20 percent of global data but stores only about 3 percent locally. That imbalance is driving a wave of hyperscale investment from companies such as Google, Digital Connexion, Reliance Industries, Brookfield, Digital Realty, Tata Consultancy Services, NTT DATA, and Sify Infinit Spaces.

The story tracks how policy mandates like RBI’s data localisation rules, SEBI regulations, and the Digital Personal Data Protection Act are accelerating in-country storage. Executives including Amit Agrawal of Techno Digital, Anil Nama of CtrlS Datacenters, and MP Vijay Kumar of Sify explain why power availability, subsea cable landings, and state-level incentives are reshaping where data centres are built.

Yet the article also asks harder questions. Can India scale AI-ready infrastructure without repeating the environmental and resource stress seen in Bengaluru. Can Tier-2 cities like Mangaluru, Hubballi, Mysuru, Panvel, and Siruseri develop ecosystems, not just server farms.

This theme continues in Smruthi Nadig’s Data Centres Seek New Homes Beyond Bengaluru, where voices such as Priyank Kharge, Rahul Takkallapally of Bharat Cloud, Amin Habibi of VergeCloud, Vinod Subramanian and Soumil Gupta of Invest India highlight the growing importance of edge computing, water security, and local demand creation.

Global Capability Centres under pressure

GCCs emerge as one of the most closely examined institutions in this issue. In ROI Keeps GCCs Awake At Night, Shalini Mondal reports that while over 90 percent of GCCs have piloted or scaled AI, nearly 72 percent still lack a structured ROI framework.

Leaders such as Julie Sweet of Accenture, Karthik Padmanabhan of Zinnov, Saurabh Sharma of ProHance, Sagar PV of Mindsprint, Alouk Kumar of Inductus Group, and Monica Pirgal of Bhartiya Converge argue that the era of experimentation is over. GCCs are now expected to deliver measurable outcomes across productivity, innovation, and revenue, not just cost savings.

The companion piece, The Great IP Escape, deepens the debate by asking who owns the innovation produced inside India’s 1,700+ GCCs. Voices including Sridhar Vembu of Zoho, Ashutosh Sharma of Forrester, Sunil Padmanabh, and Namita Adavi of Zinnov point out that while India is filing more AI patents than ever, slow approvals and tax complexity still push companies to register IP abroad.

Together, these stories frame GCCs as no longer peripheral. They are now central to India’s innovation economy, but only if governance, incentives, and execution mature in step.

IndiaAI and the global race for models

In The World Chases AGI, IndiaAI Is Still Building Pillars, Siddharth Jindal examines the gap between global frontier labs and India’s national AI mission. While companies like Google, OpenAI, Anthropic, Microsoft, NVIDIA, and Meta are shipping new models at breakneck speed, IndiaAI remains focused on foundational infrastructure.

Abhishek Singh of the IndiaAI Mission outlines progress across compute, datasets, and safety, including support for Sarvam AI’s sovereign LLM and BharatGen’s models such as Param, Shrutam, and Patram. Critics like Sanchit Vir Gogia of Greyhound Research and Jacob Joseph of CleverTap argue that India needs speed, patient capital, and execution clarity, not just policy frameworks.

This tension between ambition and velocity runs through the edition, reflecting a broader national challenge.

Startups, process intelligence, and applied AI

Several long-form features focus on companies trying to make AI operational rather than aspirational.

Mohit Pandey’s profile of Boris Levine, CTO of StoneX Group, explores how regulated enterprises adopt AI cautiously. Levine discusses why productivity gains matter less than process redesign, why context matters more than raw model power, and why India’s engineering talent in Pune and Bengaluru is central to StoneX’s future.

In Celonis Wants to Free the Process, Pandey reports from Celosphere 2025, where Alexander Rinke, Carsten Thoma, Kaushik Mitra, and Alex Hill explain how process intelligence underpins enterprise AI. Partners and customers including IBM, Accenture, Microsoft, Oracle, AWS, Deloitte, Snowflake, McKinsey, TCS, Infosys, Tech Mahindra, Mercedes-Benz, and Vinmar appear as examples of AI grounded in operational reality.

On the startup front, Smruti S profiles Orbo AI and founder Manoj Shinde, detailing how the Magic Mirror and contextual search are reshaping beauty retail through computer vision, AR, and zero-party data. The piece shows how AI startups are increasingly judged on measurable impact rather than novelty.

India Becomes Japan’s Venture Lab highlights cross-border capital flows, featuring investors such as Nao Murakami of Incubate Fund Asia, Jay Krishnan of Beyond Next Ventures, Emmanuel Selva Roya of the Mizuho India Japan Study Centre, and companies spanning fintech, deep tech, semiconductors, and AI infrastructure.

Developers, agents, and reality checks

Ankush Das’s The Myth of the Self-Coding Agent and The Right to Code Unassisted cut through agentic AI hype. Developers and leaders including Namanyay Goel of Giga AI, Brijesh Patel of SNDK Corp, Neeti Sharma of TeamLease Digital, and Liu Tang of TiDB argue that AI is a multiplier, not a replacement. Human judgement, governance, and context remain non-negotiable.

This realism is echoed in Mira Murati Ends GPU Babysitting, where Supreeth Koundinya examines Thinking Machines Lab’s Tinker API. Researchers such as Tyler Griggs of UC Berkeley and Sachin Dharashivkar of AthenaAgent describe how abstraction and infrastructure automation can accelerate research without centralising power inside a few labs.

A country in transition

The edition closes with The Last Word, adapted from a conversation with Dr Lilian Pintea of the Jane Goodall Institute, reflecting on AI as a tool that must remain grounded in human values, community impact, and stewardship.

Across nearly 100 pages, the December 2025 AIM Print edition documents India’s AI story in full complexity. It is not a victory lap, nor a warning bell. It is a snapshot of a system learning, correcting, and recalibrating in real time. The message is clear. India’s future in AI will not be decided by scale alone, but by how thoughtfully it builds the structures that turn capability into lasting advantage.

The post AIM Print December 2025 appeared first on Analytics India Magazine.
Accenture results signal continuity, not inflection, for Indian IT

Accenture’s first-quarter fiscal 2026 results point to steady execution rather than a change in demand trajectory, with brokerages saying management commentary suggests enterprise technology spending conditions remain broadly consistent with the previous year.

For Indian IT services companies, analysts tracking the sector said the results offer a read-through that reinforces stability in large transformation and outsourcing demand, even as discretionary spending shows no material improvement.

Accenture reported revenue of $18.7 billion for the quarter, up 6% year-on-year, according to its earnings filing.

The company said growth during the quarter was led by its managed services and consulting businesses, with revenues increasing 8% and 4%, respectively.

Accenture also reported new bookings of $20.9 billion, up 12% year-on-year, including $2.2 billion in advanced artificial intelligence bookings, indicating sustained deal activity despite an unchanged demand environment.

Brokerages tracking Indian IT services said Accenture’s results and management commentary offer a relevant read-through for the sector.

Analysts of such firms said the quarter reinforces the view that demand has stabilised, but has not yet entered a recovery phase driven by discretionary technology spending.

JM Financial said Accenture’s management commentary suggests that clients continue to prioritise large transformation programmes, while discretionary demand remains broadly unchanged compared with last year.

According to the brokerage, this indicates that a recovery in discretionary technology spending is likely to take time rather than materialise sharply.

JM Financial also said Accenture’s commentary highlights the continued importance of digital and data core modernisation work.

The brokerage said such foundational initiatives typically precede industry-specific solutioning, process redesign and ongoing optimisation through managed services.

According to the firm, this sequence supports a sustained pipeline of work for Indian IT services companies, which continue to play a central role in executing and scaling such programmes.

The brokerage added that acceleration in managed services revenues and management commentary around improving pricing in certain pockets of the business are incremental positives for the sector.

However, it cautioned that recent gains in Indian IT stocks mean execution against expectations remains critical.

Motilal Oswal confirmed that the demand environment remains “unchanged (for now),” based on Accenture’s management commentary.

The brokerage said there is no visible macroeconomic catalyst yet that would drive a sharp improvement in discretionary technology spending, reinforcing the view that near-term growth will continue to be driven by large, committed transformation programmes rather than optional IT projects.

At the same time, Motilal Oswal said Accenture’s commentary indicates that the groundwork for the next AI services cycle is gradually being laid.

According to the brokerage, client conversations are increasingly shifting from experimentation to readiness, with enterprises focusing on cleaning up data, modernising platforms and securing systems so artificial intelligence can be deployed at scale.

It noted that more than half of Accenture’s advanced AI engagements are now triggering data-modernisation work, underscoring the linkage between AI adoption and foundational technology services.

Motilal Oswal also highlighted Accenture’s outsourcing momentum, with overall bookings crossing $20 billion during the quarter. The brokerage said the increasing share of fixed-price, outcome-based contracts, now accounting for around 60% of Accenture’s revenue, reflects evolving commercial and delivery models across the IT services industry, with implications for productivity, execution discipline and margins.

Nomura agreed that Accenture’s results suggest that demand conditions remain largely similar to the previous year, with no noticeable change in the macroeconomic environment.

The brokerage said a sharper growth revival for Indian IT services companies would depend on broader macroeconomic improvement, particularly in the US, rather than company-specific execution alone.

Nomura said revenue growth momentum continues to be strong in the financial services vertical and expects this to support near-term performance for Indian IT services companies with exposure to banking and financial services clients.

The brokerage also highlighted Accenture’s emphasis on ecosystem partnerships, noting that a significant portion of its revenues is derived from work done with key technology partners.

According to Nomura, Accenture’s commentary reinforces that clients are moving beyond proof-of-concept AI initiatives to live use cases.

However, it said this shift continues to drive demand for core services such as cloud, data engineering and platform modernisation, rather than standalone AI deployments.

Accenture executives have described enterprise transformation as long-cycle work anchored in foundational technology.

“The pace of overall spending and discretionary spend in our market is at the same levels we have seen over the last year,” said Accenture CEO Julie Sweet during the earnings call, adding that clients continue to prioritise large, strategic transformation programmes.

“We’re not having conversations today that would suggest that there’s going to be a big change in discretionary spending,” Sweet said, adding that there is no clear macroeconomic catalyst that would materially shift client confidence.

“Clients continue to prioritise their most strategic and large-scale transformational programs, which convert to revenue more slowly, but position us at the center of the reinvention agendas,” she said.

“At least one out of every two advanced AI projects lead to a data project,” Sweet said, highlighting the linkage between AI adoption and foundational technology services.

Accenture chief financial officer Angie Park said, “About 60% of our work is now fixed-price,” reflecting clients’ preference for outcome-based, large-scale engagements and greater certainty in delivery.

Kotak Institutional Equities (KIE) too said Accenture’s commentary offers a clear read-through for Indian IT services, reinforcing the view that discretionary technology spending remains unchanged with no visible near-term recovery, as client conversations continue to reflect caution amid macroeconomic uncertainty.

The brokerage said that while a discretionary rebound is not its base case, such a recovery would have lent greater confidence to its assumption of 150–200 basis points higher growth for FY2027 across its coverage universe.

Instead, KIE noted that client priorities remain firmly centred on large-scale transformation programmes and cost take-out initiatives, with these deals being competed aggressively by global peers, including Accenture.

According to the firm, a sustained increase in the number of such large transformation deals is critical for any meaningful acceleration in industry growth.

Gaurav Vasu, CEO of UnearthInsight, agreed that Accenture’s performance points to a longer growth recovery cycle, with enterprise technology spending still constrained by a muted macro environment, and FY26 growth guidance indicating only modest improvement.

He said while revenue growth continues to be supported by AI-driven bookings and market-share gains, there are no clear signs yet of a broad-based upcycle in technology spending.

Vasu added that AI and GenAI are fundamentally rewiring enterprise technology spending, shifting demand away from traditional consulting-led technology services toward outcome-led, AI-enabled solutions, even as AI becomes increasingly embedded across most enterprise engagements.

As a result, he said standalone AI disclosures are likely to become less meaningful over time, reflecting how AI is being absorbed into core transformation and modernisation work, rather than driving a discrete spending cycle.

The post Accenture results signal continuity, not inflection, for Indian IT appeared first on Analytics India Magazine.