Enhancing metadata-driven data warehousing through AI

modern mainframe disk storage in the data center

In today’s data-driven world, organizations are constantly seeking ways to unlock the full potential of their data. Data warehousing has emerged as a crucial component in managing and analyzing vast amounts of information. However, with the ever-increasing complexity of data ecosystems, metadata-driven data warehousing, empowered by artificial intelligence (AI), has become the key to unlocking valuable insights and driving actionable business decisions. In this article, we will explore the importance of AI in metadata-driven data warehousing, provide a brief description of the metadata-driven architecture, and outline actionable steps to harness its benefits.

What is a Metadata-powered Data Warehouse? Metadata-driven architecture in data warehousing refers to using metadata to drive various data management and analysis processes. Metadata provides information about data attributes, structures, and relationships, and is crucial in facilitating data integration, governance, and analysis within a data warehousing environment.

Unleashing the power of AI in metadata-driven data warehousing

The rise of Artificial Intelligence (AI) technologies has opened new horizons for further enhancing metadata-driven data warehousing. AI can be a game-changer, augmenting the capabilities of metadata-driven approaches and enabling organizations to extract even more value from their data. Let’s explore how AI unleashes its power in metadata-driven data warehousing:

Automating metadata creation and maintenance

AI can automate the labor-intensive tasks of metadata creation and maintenance, reducing manual effort and improving efficiency. By leveraging AI algorithms, organizations can automatically extract metadata from various sources, such as data schemas, dictionaries, and data profiling results. For example, AI can analyze the structure and content of a database table to infer metadata attributes such as data types, primary keys, and relationships between tables. This automation accelerates the metadata management process and ensures that metadata remains updated.

Improving data quality and accuracy

AI algorithms can enhance data quality through metadata-driven approaches. By analyzing patterns and anomalies in the data, AI can detect data inconsistencies, outliers, and data quality issues that traditional rule-based checks might overlook. For instance, AI can identify data outliers based on statistical analysis and suggest data transformations or cleansing actions. By integrating AI-powered data quality checks into the metadata-driven framework, organizations can proactively address data quality challenges and ensure the accuracy and reliability of the data within the data warehouse.

Enabling advanced analytics and predictive insights

AI empowers organizations to unlock advanced analytics and predictive insights by leveraging metadata-driven data warehousing. AI

algorithms can uncover hidden patterns, correlations, and associations within the data by analyzing metadata attributes such as data types, ranges, and relationships. For example, AI can identify the key factors influencing customer churn by analyzing metadata related to customer demographics, purchase history, and interactions. This knowledge enables organizations to generate predictive models and make data-driven decisions for customer retention strategies.

Enhancing data integration and transformation

AI techniques such as natural language processing (NLP) and machine learning (ML) can streamline data integration and transformation processes in metadata-driven data warehousing. AI-powered NLP algorithms can interpret textual descriptions and user queries, enabling automated mapping between business terms and technical metadata attributes. ML algorithms can analyze historical metadata and usage patterns to suggest data transformation rules and mappings. For example, AI can learn from past transformations and propose the most appropriate transformation logic to convert data from one format to another, saving time and effort in data integration workflows.

A metadata-led approach combined with AI can also improve an enterprise’s data governance capabilities.

Enhancing data governance and compliance with AI

Data governance and compliance are critical aspects of modern data management, and AI technologies offer valuable opportunities to enhance these areas within the context of metadata-driven data warehousing. By leveraging AI capabilities, organizations can ensure regulatory compliance and effectively address data privacy and security requirements. Here’s how AI enhances data governance and compliance:

Automated data classification and tagging

AI can automate classification and data tagging based on its sensitivity, regulatory requirements, and business policies. By analyzing metadata attributes and content patterns, AI algorithms can accurately categorize data into relevant classifications, such as personally identifiable information (PII), financial data, or sensitive intellectual property. For instance, AI can examine the metadata and content of a dataset to identify social security numbers, credit card details, or other sensitive information, enabling automated tagging and appropriate access controls.

Data privacy and security enforcement

AI technologies play a vital role in enforcing data privacy and security measures. With the help of AI algorithms, organizations can proactively identify and mitigate potential privacy risks within their data assets. AI can analyze metadata and content patterns to detect anomalies or unauthorized access attempts, trigger alerts for suspicious activities, and enforce access controls based on data privacy regulations. For example, AI can monitor metadata attributes and user behaviors to identify abnormal data access patterns and detect potential data breaches promptly.

Intelligent data masking and anonymization

AI-powered techniques can facilitate data masking and anonymization processes to comply with privacy regulations while preserving data utility for analytics. AI algorithms can analyze metadata attributes, understand data relationships, and apply intelligent masking techniques to protect sensitive information. For instance, AI can automatically generate synthetic or masked data that retains statistical characteristics while

obfuscating personally identifiable details, allowing organizations to share or use the data in compliance with privacy regulations.

Real-time monitoring and audit trail analysis

AI enables real-time monitoring and analysis of data activities, allowing organizations to track data access, usage, and modifications. By analyzing metadata and monitoring user behaviors, AI algorithms can identify suspicious activities that might indicate data breaches or non-compliance incidents. For example, AI can detect unauthorized attempts to modify or access sensitive data, triggering alerts for immediate investigation and remediation.

Data governance policy enforcement

AI algorithms can automate the enforcement of data governance policies and procedures. By leveraging metadata attributes, AI can evaluate data quality, consistency, and adherence to defined standards. It can analyze metadata to ensure compliance with regulations and policies, such as data retention periods or sharing agreements. For example, AI can assess metadata attributes to validate that data entities are correctly documented, data lineage is maintained, and data usage adheres to defined policies.

Continuous compliance monitoring and reporting

AI technologies can facilitate constant monitoring and reporting of compliance status. By analyzing metadata and tracking changes in regulations or policies, AI algorithms can generate automated compliance reports, highlighting any areas of non-compliance or potential risks. For example, AI can analyze metadata against evolving privacy regulations and develop compliance dashboards that provide an overview of compliance status, identify potential gaps, and recommend corrective actions.

To summarize, AI enhances data governance and compliance efforts within data warehousing. Through automated data classification, privacy enforcement, data masking, real-time monitoring, policy enforcement, and continuous compliance monitoring, AI technologies provide organizations with the tools to ensure regulatory compliance, mitigate risks, and safeguard sensitive data. Organizations can establish robust data governance frameworks by leveraging AI with metadata-driven approaches and maintaining a secure and compliant data environment.

AI as the future of metadata-driven data warehousing

Metadata-driven data warehousing, enhanced by the power of AI, has revolutionized the landscape of data management and business intelligence. The use of metadata as a driving force behind data integration, governance, and analytics has proven to be a game-changer for organizations seeking to leverage their data assets effectively.

Metadata-driven data warehousing opens new possibilities for organizations to unlock the full potential of their data. By harnessing the power of metadata and AI, organizations can drive business intelligence, enhance data governance and compliance, and achieve greater agility and insights.

Data-centric development: A hypothetical tech manufacturing example

dna-3539309_1280

My son and I both had stints in 2022 at low-volume, high-margin, long-established manufacturers. My son was doing assembly for a power management system maker with renewable energy/smart grid customers. I was doing compliance document management and related analytics for a bioengineering equipment maker.

Both companies had some of the same nagging challenges. My son characterized the biggest problem he saw as inventory tracking and control. Assemblers lacked confidence that the subsystems they needed would be available in the right state of assembly when and where they needed them.

In the case of the company I had the opportunity to experience firsthand, workers couldn’t predict or assure the availability of various kinds of resources, whether it was parts, other supplies, specialized labor or something else less tangible, such as approvals.

The information systems at both companies are typical of what I’ve encountered during my 35 years here in the Valley. The companies are both well-managed and profitable. But the data architecture ultimately fails. The failure is because of the propensity to balkanize or strand data that should be consistently woven into a unified, discoverable whole, so that the right information can get to where it needs to be at the right time, for the right purpose(s).

How a great business culture can fall short

The bioengineering equipment maker workforce I got to know has a powerfully effective, enlightened culture, committed leadership and delivers sophisticated products and services to some very discriminating and knowledgeable buyers. Even so, they are compelled to use disconnected bits of dozens of applications and multiple SaaS suites to get work done. It’s like that’s the only way they know to do what they’re doing.

Duplication of effort is the only way to get a system qualified, shipped, and installed at the customer site. Each unit of operations understands the root problems but doesn’t have the authority, budget, or understanding of data architecture innovation to solve these problems. It’s fortunate the margins are high and demand strong. Otherwise, even the highest-performing business units might go into the red.

The result is time wasted and a workforce underutilized. The workforce spends considerable time either working around information gaps, or searching for information that’s been buried or isn’t in the correct form to be able to finish tasks. Time that could be spent on higher-order activities instead has to be spent with extra data entry, emails, meetings, or phone calls to address small issues that invariably gum up the process.

How data-centric development opens new opportunities

All organizations that sell products and services have their own version of the manufacturing company data challenge I’ve just described. They may not be making or shipping products, but the information dilemma generally is endemic to organization-wide systems.

Data-centric development (DCD) takes a different tack on how to address the issue. In fact, DCD is less centralized and less tightly coupled than conventional enterprise development approaches.

Think agents or digital twins on the client side designed to be interactive, instead of just APIs, for instance. And think knowledge graph(s) (KGs) on the server side that make up a semantic integration layer designed for all types of data and content. The KG methodology has its heritage in the content world, though it’s just as applicable for transactional and analytics data.

With this list of how DCD can address process and supply chain disconnects, the assumption is that a DCD best practice is standard semantics within a knowledge graph building and implementation context. Description and predicate logic (think set theory or the coded equivalent of Venn diagrams and Boolean logic for starters) empower that graph.

  1. Relationship-rich, smarter data is the norm. Data centricity within a KG context implies that organizations are committed to doing more with their data. Smarter data helps because the relationships (the verbs) that connect entities (subjects/objects) are explicit, well articulated and dynamic. Contrast with table linking and foreign keys, and relationship logic stored elsewhere than with the data.
  2. In the case of KGs, relationship (predicate and description) logic is in the graph. This design initially confuses developers who feel that the “logic should be in the app,” period.
  3. Both broad pattern and entity/event context modeling can be used to model the business. A primary objective with DCD is contextual computing: data explicitness, clarity and reuse potential derives from developers helping to build each relevant context, such as department, business line, partner or supplier context.
  4. The richness and connectability of the data enable context modeling across hundreds or thousands of sources. Current ontology (graph data model that describes, for example, how a business runs in an abstract, reusable way) modeling techniques are both pattern and event oriented. An ontology, business-specific taxonomies and rules constitute the shared intelligence that resides in the knowledge graph.
  5. Developers call the descriptions and rules in the graph. Rather than recoding the logic as a part of the application, developers use shared logic from the knowledge graph. The logic is therefore just as accessible as the instance data.

How this helps organizations

What’s most painful from a staff quality and efficiency perspective is that much of the data entry has to be done several times, in different places, for different contexts. The duplication is not only wasteful, but results in data that’s up to date in some places, but not yet in others, or clean in one way, but not analytics ready in another.

The more places humans and machines together generate the same or similar data, the greater the chance there is for misunderstanding or misinterpretation. Each of these interpretive disconnects constitutes its own bottleneck.

Data-centric development with its “create once, use everywhere” approach has the potential to ensure that bottlenecks are avoided or only need to be fixed once. A fix can become persistent and shared. Moreover, the intelligence created with the help of the information fabric can refine the information shared context by context, as well as identify discrepancies so they can be rectified before they create a larger problem.

Let Elsa be your new Alexa: Amazon adds ‘Hey Disney!’ voice assistant

Hey Disney on Echo Show Kids

Amazon has announced a new voice assistant available on supported Echo devices called 'Hey Disney!', which will let customers interact with their choice of over 20 characters from Disney, Pixar, Star Wars, and more.

This update marks the first Alexa Custom Assistant, as Hey Disney! is built on Alexa's artificial intelligence technology and is officially named the Disney Magical Companion.

Also: Amazon Echo Pop review: A portable smart speaker for small spaces

With Amazon selling both an Echo Show and Echo Dot specifically marketed for children, including in the latest generations of smart speakers, the new Disney voice assistant will be able to interact with and entertain people of all ages, from kids to adults (don't pretend having Goofy tell you the weather wouldn't be entertaining).

To get started, you can ask your Echo device, "Alexa, introduce me to Hey Disney!", and follow the prompts to set up the Disney Magical Companion.

Echo Show Kids with Mickey Mouse-inspired stand and Tiana onscreen.

You'll then be walked through the purchase and setup process, as the Disney Magical Companion is available for purchase through an annual, auto-renewing subscription.

Also: I bought this Amazon kids tablet instead of an iPad and wasn't sorry

Although the feature is available through an Alexa Skills subscription, it's also included in the Amazon Kids+ membership.

After your new Disney Magical Companion is set up, you can kiss Alexa goodbye and use 'Hey Disney!' as the wake-up words for your device.

Also: How to turn your old Fire tablet into an Echo Show

Your kids will be able to hear the voices of their favorite characters, whether its Minnie Mouse or Olaf, Mater or Tiana, Donald Duck or R2-D2, and have access to Disney trivia games, soundscapes, storybooks, and play-along adventures.

See also

Blackbird lands $20M investment to expand its risk management tools

Blackbird lands $20M investment to expand its risk management tools Kyle Wiggers 7 hours

Blackbird AI, a startup developing AI-powered software for risk intelligence, today announced that it raised $20 million in a Series B funding round led by Ten Eleven Ventures.

Bringing New York-based Blackbird’s total raised to $30 million, the tranche also had contributions from Dorilton Capital, Generation Ventures StartFast Ventures and Trousdale Ventures as well as angel investors.

“Blackbird was born out of a shared vision to leverage technology for the greater good of society,” co-founder and CEO Wasim Khaled told TechCrunch in an email interview. “Recognizing disinformation as one of the most alarming global threats of the 21st century, we were deeply concerned about the alarming ease with which even the most educated individuals were succumbing to the spread of online falsehoods and conspiracy theories.”

Blackbird, founded in 2017, claims that its first product — an algorithm to perform network analysis and adversarial cohort modeling — was used by the U.S. Department of Defense to analyze online propaganda and influence campaigns across high-profile websites. When the pandemic hit, forcing cuts in Blackbird’s Defense Department contract, Blackbird shifted its focus to the enterprise and rebuilt its backend systems to significantly broaden their scope, adding tools to ingest and normalize text, image, video and audio data from social media, news outlets, the dark web and elsewhere.

For organizations, Blackbird attempts to detect cyber “information” attacks directed against them, like mass deepfake campaigns, and equip IT teams with the capabilities to counter influence operations. Using Blackbird, users can delve into details like the content sharing patterns of specific actors or the narratives emerging in active discussions.

Blackbird provides heat map visualizations of how narratives — including toxic narratives (e.g., those involving hate speech) — flow across social media, flagging bot-like accounts and characterizing how high-profile people like influencers impact that flow. Blackbird claims it can discover key influencers within cohorts of people, mapping out how a narrative spreads over time.

“Blackbird enables leaders to swiftly counter misinformation, mitigate aggressive complaints and preempt backlash, positioning them as informed and proactive,” Khaled said. “Beyond threat mitigation, Blackbird also fosters business growth by keeping a finger on the industry pulse, tracking competitors and nurturing media relations. It measures the effectiveness of communication strategies, providing actionable insights for refinement.”

Of course, that’s promising a lot. We can’t speak to the accuracy of Blackbird’s platform, having not been afforded the chance to test it ourselves.

What’s undeniably true is that algorithms aren’t perfect. Machine learning algorithms still struggle to gain a holistic understanding of words in context. Compounding the challenge is the potential for bias to creep into the algorithms.

But even if it does perform as well as Khaled claims, Blackbird is far from alone in the reputation and risk intelligence space. Rivals include Graphika, Logically and Cyabra, which raised $5.6 million in October 2021.

Fortunately for Blackbird, it’s a large enough market to support a range of vendors. According to one estimate, the risk management software sector could be worth $86.53 billion by 2030 — up from $27.80 billion in 2021. A separate Deloitte report found that more than half of companies plan to address reputation risk by investing in technology such as analytical and brand monitoring tools

Blackbird wouldn’t disclose how many customers it has. But Khaled claims the growing threat from disinformation has been good for business.

“Disinformation, in our interconnected world, doesn’t just spread — it gallops, wreaking havoc on an organization’s reputation and operations,” he continued. “And let’s face it, the world isn’t becoming any less unpredictable. It’s in this very unpredictability that Blackbird finds its strength.”

Praxis Data Science Program: Transforming Careers Through Industry-Relevant Education and Remarkable Placement Success

Praxis Business School has emerged as a pioneer in data science education, attracting students from diverse backgrounds seeking quality education and excellent placement opportunities. The PGP Data Science program at Praxis offers a transformative learning experience, preparing students to excel in the dynamic field of data science.

After our placement drive, we sat with students from the business school to discuss their reasons for choosing Praxis, the unique learnings from the Praxis Programme and their viewpoints on what drives companies to recruit from Praxis.

Q1. What Made You Choose the PGP Data Science Program at Praxis?

“Having initially enrolled in an online data science course, I was dissatisfied with the quality of education and the remote learning experience. Seeking a more immersive and top-notch learning environment, I embarked on a quest to find the best institute in India for data science. That’s when Praxis caught my attention because of its reputation for excellence in data science education and an exceptional on-campus placement record,” said Aji Thomas, a student from Praxis.

He added that after conducting extensive research and hearing positive reviews from alumni, I confidently chose to join the PGP-DS program at Praxis.

Another student Andrew George Cherian said that he became acquainted with Praxis and its unrivalled course structure and distinguished faculty through a college friend of mine who graduated from Praxis in 2019.

“As someone with six years of experience in the engineering sector, the prospect of undergoing a uniquely crafted program that could reshape my career within a mere nine months was immensely appealing. Praxis’s esteemed position in the data science realm, coupled with its ability to deliver on its promises, solidified my belief that this institution was the ideal choice for me,” he added.

Sanskriti Jain, a Praxis alumni, realises the importance of an offline classroom environment after the pandemic and made an informed decision to join Praxis.

“Praxis’s prominent ranking as a pioneer in data science education further validated my choice. The institution’s commitment to offering an exceptional education and fostering a supportive learning environment comprising both faculty and peers cemented my belief that Praxis was the perfect fit for my data science journey. Praxis undoubtedly is the premier destination for Data Science Education in India,” Jain added.

Q2. We understand that Praxis has an incredible day-zero with 20+ recruiters, something that is normally witnessed at top institutes like IIMs/ IITs. Can you give us a glimpse of what happened that day?

“The campus buzzes with excitement in the week leading up to the much-anticipated Day Zero placement drive at Praxis. But it is on Day Zero itself when the real magic unfolds. There’s an influx of renowned companies, including industry giants like PwC, EY, Wells Fargo, ITC, Hero Fincorp, Kantar, Subex, and many others, at Praxis to seek out exceptional talents,” said Thomas.

He presented the entire scene of Day Zero. The air is filled with anticipation as the shortlisted students step into the final interview rounds. And then, the offers start pouring in. As the clock strikes 5:10 AM, the first offer of the day arrives, setting the tone for an unforgettable experience. By noon, an astonishing 45% of the batch has already secured placements. The numbers soar as the day progresses, with students receiving remarkable offers, including an impressive Rs. 17.6 LPA to nine students and Rs. 16 LPA to thirteen students.

Cherian took us through the preparations that happen behind the curtain. “I would like to emphasize the hard work that goes into making this a monumental day. The weeks leading up to Day Zero are filled with meticulous preparations, as students engage in pre-placement sessions, written tests, mock GDs and interviews conducted by faculty and alumni, to gear up for the ultimate test of their abilities.”

He added that it is all worth the effort, as is evidenced by the enormous success Praxis students achieve, batch after batch.

“Close your eyes and imagine the scene— an atmosphere brimming with enthusiasm, and a campus teeming with anticipation. It’s 3:45 am, and students eagerly converge at Praxis for the extraordinary Day Zero placement drive,” said Jain

“As the clock strikes 5:00 am, the interview process commences. As time goes by, and offers begin to pour in, the collective achievements of the students are celebrated. By 6 PM, 62+% of the batch has secured prestigious placements,” she continued.

Day Zero at Praxis is a spectacle that is a testament to the exceptional education, unwavering support, and pursuit of excellence that defines Praxis Business School.

Q3. What makes companies make a beeline to recruit at Praxis?

“Praxis stands out due to its industry-oriented program and diverse student community. The curriculum caters to industry demands, providing practical tech skills and exposure to various domains. Students from different backgrounds, ranging from beginners to experienced professionals, offer a wealth of perspectives and ideas. The fair and transparent recruitment process ensures access to the most suitable candidates for companies seeking diverse talent,” said Thomas.

Talking about Praxis’ consistent track record of producing high-quality students attracts companies year after year, Cherian said that the institute’s continuous curriculum updates align with industry requirements, ensuring students are well-prepared.

“The exceptional performance of Praxis alumni also contributes to the repeated recruitment from leading companies, reaffirming Praxis’ strong industry relevance,” he added.

“Praxis’ esteemed alumni actively participate in the recruitment process, setting high standards for current students. Their recognized industry performance and contributions enhance Praxis’ reputation and make it an attractive choice for recruiters. The repeated presence of reputable companies reinforces the institution’s industry relevance,” said Jain.

Q4. As a part of the Placement Committee (PlaceCom) can you help us understand what makes the Praxis Program special?

Praxis’ curriculum is recognized for its rigorous and relevant content, continuously updated to meet industry needs. The faculty members, who are industry experts, blend theoretical and practical knowledge, ensuring students are job-ready,” said Jain.

She added that collaborative projects and assignments foster peer-to-peer learning, creating a supportive learning environment. The capstone project, guided by faculty mentorship, allows students to apply their knowledge and receive evaluations from industry experts, further enhancing their skills.

“With strong industry connections and a vast alumni network, Praxis facilitates access to a wide range of job openings and employers. The Student Placement Committee plays a crucial role in ensuring student and employer satisfaction by understanding specific requirements, offering counselling and skill-building sessions, and continuously improving based on recruiters’ feedback,” said Thomas.

“As a member of the student Placement Committee, I have witnessed the institute’s unwavering support and guidance for students throughout the program,” said Cherian.

He further said that Praxis not only imparts knowledge but also embraces empathy, understanding the aspirations and challenges of each student. The institute’s pure intent to nurture and uplift its students is palpable in every interaction. Multiple opportunities are provided to convert job applications into offers, and comprehensive assistance is given for interview preparation. “Praxis Business School’s PGP Data Science program offers a compelling educational experience and exceptional placement opportunities. With its comprehensive support and transformative learning environment, the Praxis Program sets students on a path to success in the field of data science,” concluded Cherian.

The post Praxis Data Science Program: Transforming Careers Through Industry-Relevant Education and Remarkable Placement Success appeared first on Analytics India Magazine.

5 Free Julia Books For Data Science

5 Free Julia Books For Data Science
Image by Author

You might be hearing a lot about Julia and why it is the future of data science, but you don’t know where to start. I have the perfect solution for you. You can start by checking out the awesome list of free books on the Julia programming language that will prepare you for software engineering and data science-related tasks.

You will learn about Julia libraries for data frames, data visualization, machine learning, and creating and running a web service. Moreover, you will learn object-oriented programming, metaprogramming, and parallel computing.

1. Think Julia

Think Julia: How to Think Like a Computer Scientist by Ben Lauwens and Allen B. Downey is a book for anyone who wants to learn Julia, from beginners to experienced programmers.

5 Free Julia Books For Data Science
Book Cover

The book begins with an introduction to Julia, explaining what it is, how it works, and why it is different from other programming languages. The authors then provide a brief history of Julia and discuss its current development and future potential.

The book has simple examples to illustrate each concept and provides exercises at the end of each chapter to reinforce learning.

The book also covers more advanced topics, including arrays, matrices, strings, and input/output. Moreover, It covers object-oriented programming, metaprogramming, and parallel computing.

2. Julia as a Second Language

Julia as a Second Language by Erik Engheim is another beginner-friendly guide for programmers who are already familiar with another programming language and want to learn Julia as a second language.

The book starts with an introduction to Julia and its history, followed by a discussion of its features, advantages, and unique selling points. It compares Julia to other popular programming languages, such as Python, MATLAB, and R.

5 Free Julia Books For Data Science
Book Cover

It also covers object-oriented, functional programming, and advanced topics, such as arrays, matrices, strings, and input/output. The author also covers metaprogramming, parallel computing, and how to work with external libraries and packages.

3. Statistics with Julia

Statistics with Julia by Hayden Klok and Yoni Nazarathy is a comprehensive guide to statistical analysis using the Julia programming language. This is for anyone who wants to learn how to perform statistical analysis and modeling using Julia.

5 Free Julia Books For Data Science
Book Cover

The book covers basic syntax, followed by an introduction to the fundamentals of statistics, including probability theory, descriptive statistics, statistical inference, statistical methods, and models, including linear regression, logistic regression, clustering, and time series analysis.

It also covers how to work with external data sources, including CSV files and databases, and how to visualize data using Julia's plotting libraries.

You will be learning about reproducibility in statistical analysis and how to organize and document code and data.

4. Julia Data Science

Julia Data Science by Storopoli, Huijzer, and Alonso is an open-source and open-access book on how to use Julia programming for data science-related tasks.

The book begins by explaining what is data science and software engineering and then explains why you should spend time learning the language that is never mentioned in the job posting.

5 Free Julia Books For Data Science
Book Cover

The book starts by introducing the Julia syntax, data structures, file systems, and standard libraries. Then, it moves to topics that are important for data analysis and modeling using data frames and data visualization libraries.

The book is well-written, easy to follow, and provides a comprehensive introduction to data analysis and modeling libraries for beginners or experienced data scientists.

5. Julia for Data Analysis

Julia for Data Analysis by Bogumi? Kami?ski is a practical guide to data analysis using Julia for experienced data analysts, programmers, and beginners who want to learn how to use Julia for performing effective data analysis and reporting.

5 Free Julia Books For Data Science
Book Cover

The book is divided into two parts.

The first part is about the basics of Julia programming, where you will learn syntax, loop, and data structures. Next, you will learn elements of the Julia language that are important when creating scalable projects.

The second part is about the toolbox for data analysis. In this part, you will learn to handle data using a dataframe, clean, manipulate, and transform data for analysis, and create a web service for sharing data analysis results.
Abid Ali Awan (@1abidaliawan) is a certified data scientist professional who loves building machine learning models. Currently, he is focusing on content creation and writing technical blogs on machine learning and data science technologies. Abid holds a Master's degree in Technology Management and a bachelor's degree in Telecommunication Engineering. His vision is to build an AI product using a graph neural network for students struggling with mental illness.

More On This Topic

  • 5 Free Books to Learn Statistics for Data Science
  • 5 Free Data Science Books You Must Read in 2023
  • Top 2020 Stories: 24 Best (and Free) Books To Understand Machine Learning;…
  • Free From MIT: Intro to Computational Thinking with Julia
  • KDnuggets News, November 2: The Current State of Data Science Careers • 15…
  • 24 Best (and Free) Books To Understand Machine Learning

The Secret Weapon for the Survival of Indian Edtech Firms

ChatGPT has presented a significant challenge to the edtech firms forcing stakeholders to either embrace its capabilities or risk falling behind. Last month, US-based edtech firm Chegg, in a trading update, stated that the company’s business has been adversely affected by the increasing use of generative AI. While the first-quarter results were relatively unaffected by this trend, the impact has become more noticeable in the past two months.

At a time when some edtech platforms undermined the power of ChatGPT and ended up at the cusp of failure, there were others like Khan Academy that assessed the potential of generative AI early and embraced it. For instance, in March, Khan Academy launched Khanmigo, a GPT-4-powered virtual tutor and learning guide.

In India, edtech firms are following suit, however, the industry is currently facing a precarious situation. While these firms experienced rapid growth during the pandemic, they are now grappling with instability as normalcy gradually returns. Many of them are facing difficulties in maintaining stability, leading to downsizing and layoffs within the sector. Hence, generative AI could emerge as a saviour for the sector as it could help provide hyper-personalised learning experiences to students.

“Edtech firms will continue to be a UX layer (that provides context, capacity, and creativity) above generative AI. And if this UX layer is enabled with Natural Language Processing (NLP) and has rich Machine Learning data, edtech firms can prompt generative AI to create meaningful learning experiences,” Rishabh Ranjan, chief data scientist at ConveGenius, told AIM.

Indian edtech firms leveraging generative AI

Today, in India, we have a host of edtech firms using Large Language Models (LLMs) to provide hyper-personalised learning experiences to students. Mayank Kumar, co-founder & managing director at upGrad told AIM that the edtech firm is exploring the idea of building their own proprietary LLM. “These cutting-edge models have proven to be invaluable assets in enhancing our educational offerings and providing valuable insights to our learners. However, we also have an eye towards the future, as we are actively exploring the possibility of building our own proprietary LLM.”

upGrad has also built a GPT-powered chatbot to allow learners to conduct mock interviews at their convenience. “The chatbot is designed to offer real-time performance scores and feedback to our learners while also providing them with guidance/corrective measures to improve their skill sets,” Kumar said. Additionally, they are also in the process of developing a coaching bot.

Akshay V, founder at EdZola also told AIM that they have been using GPT models API’s long before ChatGPT was announced to explore how generative content can help nonprofits and educational institutions. Most recently, Byju’s, the most valuable startup in India, announced Wiz, a series of AI models for hyper-personalised learning. The suite includes BADRI, MathGPT, and TeacherGPT and these models will be integrated across the entire product portfolio of Byju’s from Pre-K to Gray.

Similarly, Cuemath wants to solidify the maths learning approach by helping teachers customise their teaching method for each of their students. “We are currently working on multiple use cases and experimenting with this technology with copilots for our teachers to create prompts that they can refer to, cue students and help them solve the problem,” Manan Khurma, chief executive & founder at Cuemath, told AIM.

Additionally, Cuemath is exploring the use of LLM to generate content for maths learning, practice and exam preparation. “If the experiments turn out to be successful, we will be able to curate unique test papers for students that will be specifically based on their learning journeys and their abilities to solve maths rather than putting them all to solve the same level of complex mathematical problems,” Khurma added.

SkillUp Online, which offers online IT certification, is also using generative AI to drive deeper engagement with learners, providing personalised and immersive teaching assistance. “It is also exploring how the technology can be used to empower teachers and instructors to deliver content more effectively and efficiently,” Ratan Deep Singh, chief executive & chief evangelist, SkillUp Online, told AIM.

Furthermore, there are a few other firms which are leveraging generative AI such as ConveGenius, Unacademy and Doubtnut. AIM also reached out to a host of other edtech players in the industry like Vedantu and TimesPro among others, however, they refused to share any details in this regard.

Generative AI adding to Regulatory challenges

Regulating the edtech firms in India has remained a concern for a long time. Even though significant steps have been taken in this regard, the use of generative AI gives regulatory concerns a whole new dimension. “AI-based technologies in education have the potential to transform the way students learn, but they also raise concerns about privacy, security, bias, and ethical considerations,” Advocate Satya Muley, founder at Satya Muley & Co, had earlier told AIM.

In this regard, the Internet and Mobile Association of India (IAMAI) has taken a proactive step by establishing the India Edtech Consortium (IEC), an autonomous body aimed at fostering self-regulation within the edtech industry. The IEC’s primary objective is to develop a comprehensive Code of Conduct for edtech companies, along with implementing an effective grievance redressal mechanism for addressing consumer concerns. However, the consortium’s focus on AI systems and ethical considerations within edtech startups remains relatively limited.

LLMs like GPT-4 hallucinates comparatively lesser compared to GPT3.5, its predecessor. However, it does hallucinate. A professor at Texas A&M-Commerce failed more than half of his students when ChatGPT incorrectly asserted that it had written their papers. Consequently, the university chose to withhold the affected students’ diplomas. Incidents like this highlights the challenges that come with LLMs. Tools like Byju’s MathGPT, for example, could provide wrong answers to students, or LLMs could generate content which are factually wrong. Now, imagine a situation where a student fails an exam by learning inaccurate content generated by a LLM? Byju’s have mentioned that their models have an accuracy of 90%, which means there is room for error, even though minute.

Kumar said upGrad deals with these challenges in multiple facets. They have a robust filtering mechanism, which includes data filtering, comprehensive training and also human review. “Our team of human reviewers plays a crucial role in evaluating the text generated by LLMs. Their expertise and discernment contribute to maintaining the accuracy, safety, and overall quality of the generated content,” he concluded.

The post The Secret Weapon for the Survival of Indian Edtech Firms appeared first on Analytics India Magazine.

OpenAI announces updates to API, including improved function calling capabilities

OpenAI logo on the website displayed on a phone screen and ChatGPT on AppStore displayed on a phone screen are seen in this illustration photo taken in Krakow, Poland on June 8, 2023. (Photo by Jakub Porzycki/NurPhoto via Getty Images)

As OpenAI has gained more popularity than ever thanks to the launch of ChatGPT last fall, its application programming interface (API) has also become a sought-after tool for developers. Different companies have found inspiration in OpenAI's success and want to replicate it, leading to developers using its APIs to build more and more tools.

To help deal with this surge in demand, OpenAI has announced some changes to its API, such as improved function calling capability, more steerable versions of GPT-4 and GPT-3.5 Turbo, a new 16k context version of GPT-3.5 Turbo, and a 75% cost reduction in the Embeddings model, the latter resulting in reduced costs for developers that pay for the API.

Also: 92% of programmers are using AI tools, says GitHub developer survey

Some of the new updates include a new function calling capability in the Chat Completions API that will allow developers to connect the power of the GPT models with external tools more reliably. With the update, developers will be able to provide instructions for GPT-4 and GPT-3.5 Turbo by describing the functions, and the model will output a JSON object with the necessary arguments to call those functions.

This update makes it easier for developers to build chatbots or applications that interact with external tools and APIs to perform specific tasks, such as sending emails, retrieving weather or flight information, or extracting data from text sources such as websites.

Also: GPT-3.5 vs GPT-4: Is ChatGPT Plus worth its subscription fee?

The updates also make for more steerable GPT-4 and GPT-3.5 models, so developers can exert greater control over the models' output. OpenAI is allowing developers to craft the context, specify desired formatting, and provide instructions to the model about the desired output. Essentially, developers have more say over the tone, style, and content of the responses generated by the models used in their applications.

OpenAI also announced the launch of the new 16k context version of GPT-3.5 Turbo, which differs from the GPT-3.5 model behind ChatGPT, as it was specifically tailored for developers to create chat-based applications. The latest 16k model is an upgraded variant from the standard, previously used 4k model.

Also: AMD unveils MI300x AI chip as 'generative AI accelerator'

The context in "16k context" is used to describe the text within a conversation that helps provide context and helps the model understand the input and provide responses that are relevant to the conversation. The 4k, or 4,000, tokens in the standard GPT-3.5 Turbo model limited the model's ability to maintain the context in a conversation to a few paragraphs. 16k, or 16,000, tokens, equals about 20 pages of text, giving the model a larger amount of text as context.

Lastly, OpenAI announced it's been able to become more efficient and reduce costs, so it's reducing the Embeddings model by 75% to $0.0001 per 1k tokens, and the GPT-3.5 Turbo by 25% to $0.0014 per 1k input tokens and $0.002 per 1k output tokens. The new GPT-3.5 Turbo-16k model is priced at $0.003 per 1k input tokens and $0.004 per 1k output tokens.

Artificial Intelligence

Delhi-based Erisha Space Plans to Launch Satellite in 2024

Delhi-based Erisha Space Plans to Launch Satellite in 2024

In April, the announcement of the Indian Space Policy 2023 made the space available for private sectors. Banking on this, Erisha Space, a space technology company has announced its plan to launch a satellite equipping AI-based image processing capabilities for environmental analysis and sustainable development.

The satellite set to be launched in 2024, will boost the company’s remote vision capabilities by GIS and photogrammetry in various domains.

Founded in 2022 in New Delhi and operating out of Bengaluru, the company has been leveraging multi-mission satellite sensors, ground instruments, SCADA, and socio-economic data to develop mathematical models for tracking and monitoring large-scale changes in the environment for tackling climate change.

Darshan Rana, managing director of Erisha Space and head of the parent company Rana Group said, “We aim to bring about effective planning and monitoring of national missions through space-based geospatial support.”

The satellite equipped with image processing capabilities will be able to provide insights for agro-economic, topographic mapping, infrastructure planning, deforestation, city planning, and environmental impact assessment.

Debaddatta Mishra, director of Erisha Space has also worked as a senior scientist at ISRO. He further announced that the company is developing an SSLV by the year 2026 with a payload capacity of 1,000 kilograms in lower earth orbit.

Read: It’s Time for ‘Swachh Antariksh Abhiyan’

India has been taking steps to make the space more accessible for everyone, including big-tech and startups. The Indian government also planned to allow 100% foreign direct investment (FDI) in the space sector, paving the way for big-tech companies to invest in India.

Earlier, all the contribution in the space industry in India was done by ISRO. But now with private players like Bellatrix Aerospace, Skyroot Aerospace, and now Erisha Space, the hopes for space technology in India have launched.

The post Delhi-based Erisha Space Plans to Launch Satellite in 2024 appeared first on Analytics India Magazine.

Copy from a Friendly LLM, but Don’t Expect Perfect Results

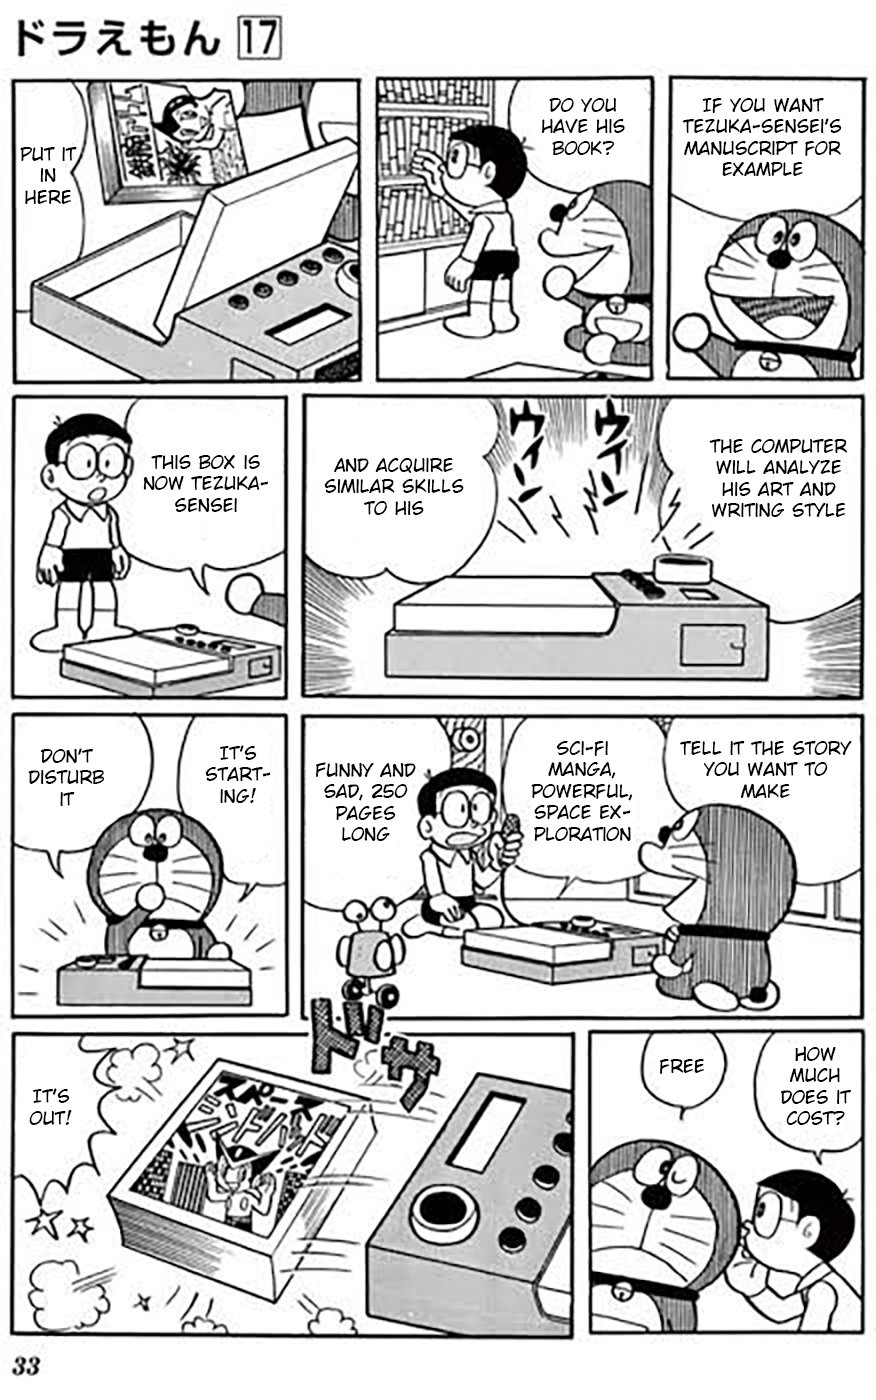
Exactly 44 years ago, one of the popular Japanese manga series Doraemon, predicted how a computer was able to generate output perfectly.

Source: Reddit

Cut to present, we are not even close.

In February, an article published in The New Yorker spoke about large language models (LLMs) like GPT-4, and pulled parallels to training these models with that of Xerox photocopiers, where the output is often grainy and usually not the same as the original document/input. The output of large language models shows similar traits.

Coincidently, the latest research paper called ‘The Curse of Recursion’ also backs this very analogy which talks about model collapse – a degenerative process whereby, over time, models tend to forget the true underlying data distribution, even in the absence of a shift in the distribution over time.

Model Collapse

The researchers said that training models with content generated by LLMs (say GPT-4 and alike) leads to irreversible defects, causing the loss of less common content. This content is not preserved in trained models which are ultimately removed in the generated output. They call this effect ‘Model Collapse.’ This results in output that are biased towards frequently occurring patterns or content, with the less common content being eliminated.

Source: arxiv.org

The researchers also suggest that in order to ensure long-term learning, it’s important to have access to the original data source and additional data that is not generated by LLMs. However, differentiating content between that generated by LLM and other data raises challenges in tracking and verifying the source of internet-crawled content.

Simply put, the model collapse phenomenon says that if the models are going to be trained on generated content, the results will not only eliminate a lot of the original work but also carry forward flaws, which only exacerbates the problems created by chatbots.

LLM Poisoning

The researchers also underlined the big problem of poisoning attacks that make chatbots act in inexplicable ways. Recently, Google chief Sundar Pichai spoke about the same where he admitted to not understanding how their AI chatbot Bard comes up with certain responses. While Google is still clueless, OpenAI is experimenting with methods such as process supervision to reduce hallucinations and data poisoning, inching closer towards AGI.

When LLMs Try to Act Smart

Currently, open-source models such as Alpaca, Vicuna, GPT4All, can be fine-tuned with the output of close-sourced ChatGPT with the hope to build stronger models. However, the imitation process is only going to lead to flawed results. See it for yourself below:

According to research, ‘The False Promise of Imitating Proprietary LLM’, fine tuning a weaker model to improve its capabilities has minimal to no impact on the model, as the base data remains the same and it only alters the style of the model. In addition, through this method, the new models will also inherit the flaws and biases of the stronger model.

A few months ago, ahead of Bard launch, Google was accused by a former employee of training Bard using ChatGPT’s data. Sam Altman was fine with it, however, Google was quick to rubbish these claims.

But, could this be a reason why Bard is not as good as ChatGPT?

The post Copy from a Friendly LLM, but Don’t Expect Perfect Results appeared first on Analytics India Magazine.