Everyone is creating their own personalised GPT and the most important one just dropped. LLM Course GPT is here, which is an interactive chatbot built on custom GPT available on the GPT Store, trained on LLM course data.
Click here to check out the GPT if you have a GPT-4 subscription.
The model is created by Maxime Labonne, who is an open source enthusiast and also a machine learning scientist at JPMorgan. It leverages code interpreters to create a mini-RAG pipeline and retrieves the relevant context to answer questions.
This comes just a week after Labonne completed the LLM Course, which is a GitHub repository containing three courses for LLM Fundamentals, LLM Scientist, and LLM Engineer, for different levels and stages of building and applying LLMs for use cases. The LLM Course GPT is built using this course.
The course and the GPT offers a comprehensive understanding of what it takes to build LLMs and using it for building applications using it.
Recently, Labonne also created Phixtral, which combines the competence of Mistral’s Mixture of Experts model and Microsoft’s Phi-2.
Labonne spoke with AIM in an exclusive interview and expressed his passion for building open source models and teaching people how to build models.
“In the long run, open source is [going to be] too powerful and there are way too many people who want to experiment with it right now,” Labonne said. He believes that eventually open source models will overtake the closed ones. “It is like there are monkeys with a typewriter – one of them will create a masterpiece at some point,” he quipped about open source developers, who are not bound by companies and academic institutions.
The post Learn to Build LLMs Using this Latest GPT appeared first on Analytics India Magazine.
In a world of Kannada, Tamil, Telugu and Odia Llamas, and SarvamAI’s bilingual LLM OpenHathi supporting both Hindi and English, Tech Mahindra’s Project Indus is all geared up to build LLMs grounds-up. These will specifically cater to speakers of the Hindi language across dialects like Bhojpuri, Kangdi, Angika, Nagpuri, Khortha, Kudmali, Panch-Parganiya, Hadauti etc.
“Hindi is spoken by 615 million speakers, much more than anybody who considers English as their first language as native speakers as well,” said Nikhil Malhotra, CIO at Tech Mahindra and the brain behind Project Indus, sharing with AIM the details of the project, data challenges, tech stack, and the roadmap ahead in an exclusive interaction.
Malhotra said that most of the models in India are built on top of Llama or use existing foundational model APIs. Those who seem to be building from scratch are yet to reveal what they are really built on—underlining that “it’s INDUS and BharatGPT, which are actually built from the ground up”.
Project Indus started in June last year to build India’s very own foundational models from scratch; there hasn’t been a turning back ever since. “When I came back from the US, the whole idea was how do you start the language revolution?” said Malhotra, sharing his interaction with CP Gurnani, who took Sam Altman’s words a little too seriously.
Coincidentally, Malhotra, around that time, was also working on a language model calledBHAML, or Bharat Mark-up Language. This AI system was used by kids to code in a language of their choice. He was roped in to build Project Indus.
“India did not have a foundational model at that point in time. So, we had different models. We had translational models like Bhashini, we had different, but there was no cut foundational modelling in the system,” shared Malhotra, speaking at length about the data challenges around low-resource Indic languages, particularly in Hindi (which has more than 49 dialects).
He stressed on the underrepresentation of Indic languages in the existing AI systems and models, including GPT-4, Llama and others.
“Because most of these dialects are on the endangered list. 80% of the Indians that do not speak English could also communicate,” said Malhotra.
Malhotra emphasised the significance of linguistic diversity, mentioning less common dialects like Angika, Nagpuri, Khortha, Kudmali, Panch-Parganiya, and Hadauti. “The aim is to serve languages spoken by 100,000 to 200,000 people, ensuring inclusivity across various linguistic groups.”
He further reiterated that, “The vision was to become a platform that can serve every Indian and every business… It could be a housewife, a patient, a farmer, or even machines.” This inclusivity defines the versatile persona-oriented nature of The Indus Project.
Data Collection and Language Diversity
The foundation of Indus relies on a vast dataset of 10 billion tokens, predominantly sourced from various parts of northern India, Bhashini, Bhasha-dan, etc.
“I sent teams to the country’s northern belt; we went to Madhya Pradesh, Rajasthan, and some parts of Bihar.” The teams’ task was to collect Hindi and dialect data by interacting with professors and leveraging the Bhasha-dan portal available on ProjectIndus.in.
He also highlighted the initiative to involve Tech Mahindra employees in contributing everyday interactions through sentences like ‘Main ghar se bahar jata hu’ to the portal to gather diverse linguistic prompts.
However unique, these methods would’ve taken years to collect quality and diverse larger data sources so the team turned to using the Falcon structure, incorporating data from the pile dataset, a free open-source resource. Additionally, they translated some datasets from Pile into Hindi, contributing significantly to the overall data volume.
Malhotra mentioned the development of toolkits to manage biases in the data, including a bias tool that identifies nine different types of biases in continuous text. About 70,000 to 80,000 sentences were annotated by individuals to create a biased analogy or classification algorithm, allowing for the identification and handling of biases in the dataset.
Model Architecture and Innovation
Project Indus team has used decoder-architecture-based transformers. However, Malhotra noted that, “These are transformers, but it has Tokenisers, which will be only Hindi.”
Malhotra highlighted the significance of the Hindi-only tokenisation, with approximately “10 billion tokens and 539 million parameters.” The decoder stack undergoes pre-training before being embedded within the Transformers of Hugging Face for open-source utilisation.
The LLMOps system involves data collection, pretraining, fine-tuning, understanding model behaviour, monitoring, and production deployment. Malhotra mentioned using open-source tools like CommEt and Switch for LLMOps management.
Additionally, to address the challenge of computational efficiency and the economics of scale, he said they will use Tensor Networks, inspired by quantum, to optimise the model’s performance, which the team is expected to release in April. “We needed multi-parallel GPUs in terms of what we were doing. So we actually used C-DAC’s GPUs, about 48 large 40 GB GPUs, and trained them for at least four days, four to five days,” said Malhotra.
What’s next?
Project Indus is gearing up for its use in diverse applications, including rural finance, agri-tech and media and entertainment. It aims to empower rural communities with a language model that understands their dialects, reducing reliance on call centres.
The team said that the model will be offered in open-source and enterprise-source formats, catering to innovators and enterprise applications. An innovative proposal involves making tractors conversational to address farmers’ challenges on the edge.
Malhotra said that following the Hindi model, the focus of the mere 14-member driven team will shift to Bangla, which is spoken by up to 400 million people.
Furthermore, he emphasised India’s potential to lead in AI research and development. With abundant data, talent, and unique use cases, he urged the Indian ecosystem to focus on defining new algorithms for AI. The call is to leapfrog in terms of innovation and sustainability, ensuring that AI serves the diverse needs of the Indian populace.
“We’ve caught on to the trend of LLMs, but we are still not leading the trend. (But) I think it’s time for Indian researchers and the Indian ecosystem to lead the trend,” concluded Malhotra, outlining the key factors that position India uniquely for AI advancements: an abundant data source and a pool of talent.
Recent News & Stories
[Exclusive] Tech Mahindra’s Nikhil Malhotra on Making Foundational Models for India
Learn to Build LLMs Using this Latest GPT
OpenAI Got 9.9 Problems, But Gary Ain’t One
Microsoft Research India Extends Deadline for Research Fellow Program Applications to Feb 16, 2024
The Real Reason Behind Google’s Recent ‘Layoffs’
The post [Exclusive] Tech Mahindra’s Nikhil Malhotra on Making Foundational Models for India appeared first on Analytics India Magazine.
OpenAI has partnered with Common Sense Media to maximize the benefits of AI for teens and families while minimizing risks.
The two organisations will initially collaborate on AI guidelines and education materials for parents, educators and young people, as well as a curation of family-friendly GPTs in the GPT Store based on Common Sense ratings and standards, the company said in the blog post.
“AI offers incredible benefits for families and teens, and our partnership with Common Sense will further strengthen our safety work, ensuring that families and teens can use our tools with confidence,” said Sam Altman, CEO of OpenAI.
OpenAI recently launched the GPT Store, which features millions of GPTs catering to different purposes.
Common Sense Media is a non-profit organisation that reviews digital media content for kids, ranging from movies, TV shows, books to podcasts. With this partnership, OpenAI intends to create a separate kids’ section that would have GPTs to help children educate themselves. This would also make it easier for parents to check how their children are using ChatGPT.
“Together, Common Sense and OpenAI will work to make sure that AI has a positive impact on all teens and families,” said James P. Steyer, founder and CEO of Common Sense Media.
“Our guides and curation will be designed to educate families and educators about safe, responsible use of ChatGPT, so that we can collectively avoid any unintended consequences of this emerging technology,” he added.
The post OpenAI Partners With Common Sense Media to Make ChatGPT Family Friendly appeared first on Analytics India Magazine.
Semron wants to replace chip transistors with ‘memcapacitors’ Kyle Wiggers 8 hours
A new Germany-based startup, Semron, is developing what it describes as “3D-scaled” chips to run AI models locally on smartphones, earbuds, VR headsets and other mobile devices
Co-created by Kai-Uwe Demasius and Aron Kirschen, engineering graduates from the Dresden University of Technology, Semron’s chips use electrical fields to perform calculations instead of electrical currents — the medium of conventional processors. This enables the chips to achieve higher energy efficiency while keeping the fabrication costs to produce them down, Kirschen claims.
“Due to an expected shortage in AI compute resources, many companies with a business model that rely on access to such capabilities risk their existence — for example, large startups that train their own models,” Kirschen told TechCrunch in an email interview. “The unique features of our technology will enable us to hit the price point of today’s chips for consumer electronics devices even though our chips are capable of running advanced AI, which others are not.”
Semron’s chips — for which Demasius and Kirschen filed an initial patent in 2016, four years before they founded Semron — tap a somewhat unusual component known as a “memcapacitor,” or a capacitor with memory, to run computations. The majority of computer chips are made of transistors, which unlike capacitors can’t store energy; they merely act like “on/off” switches, either letting an electric current through or stopping it.
Semron’s memcapacitors, made out of conventional semiconductor materials, work by exploiting a principle known in chemistry as charge shielding. The memcapacitors control an electric field between a top electrode and bottom electrode via a “shielding layer.” The shielding layer, in turn, is controlled by the chip’s memory, which can store the different “weights” of an AI model. (Weights essentially act like knobs in a model, manipulating and fine-tuning its performance as it trains on and processes data.)
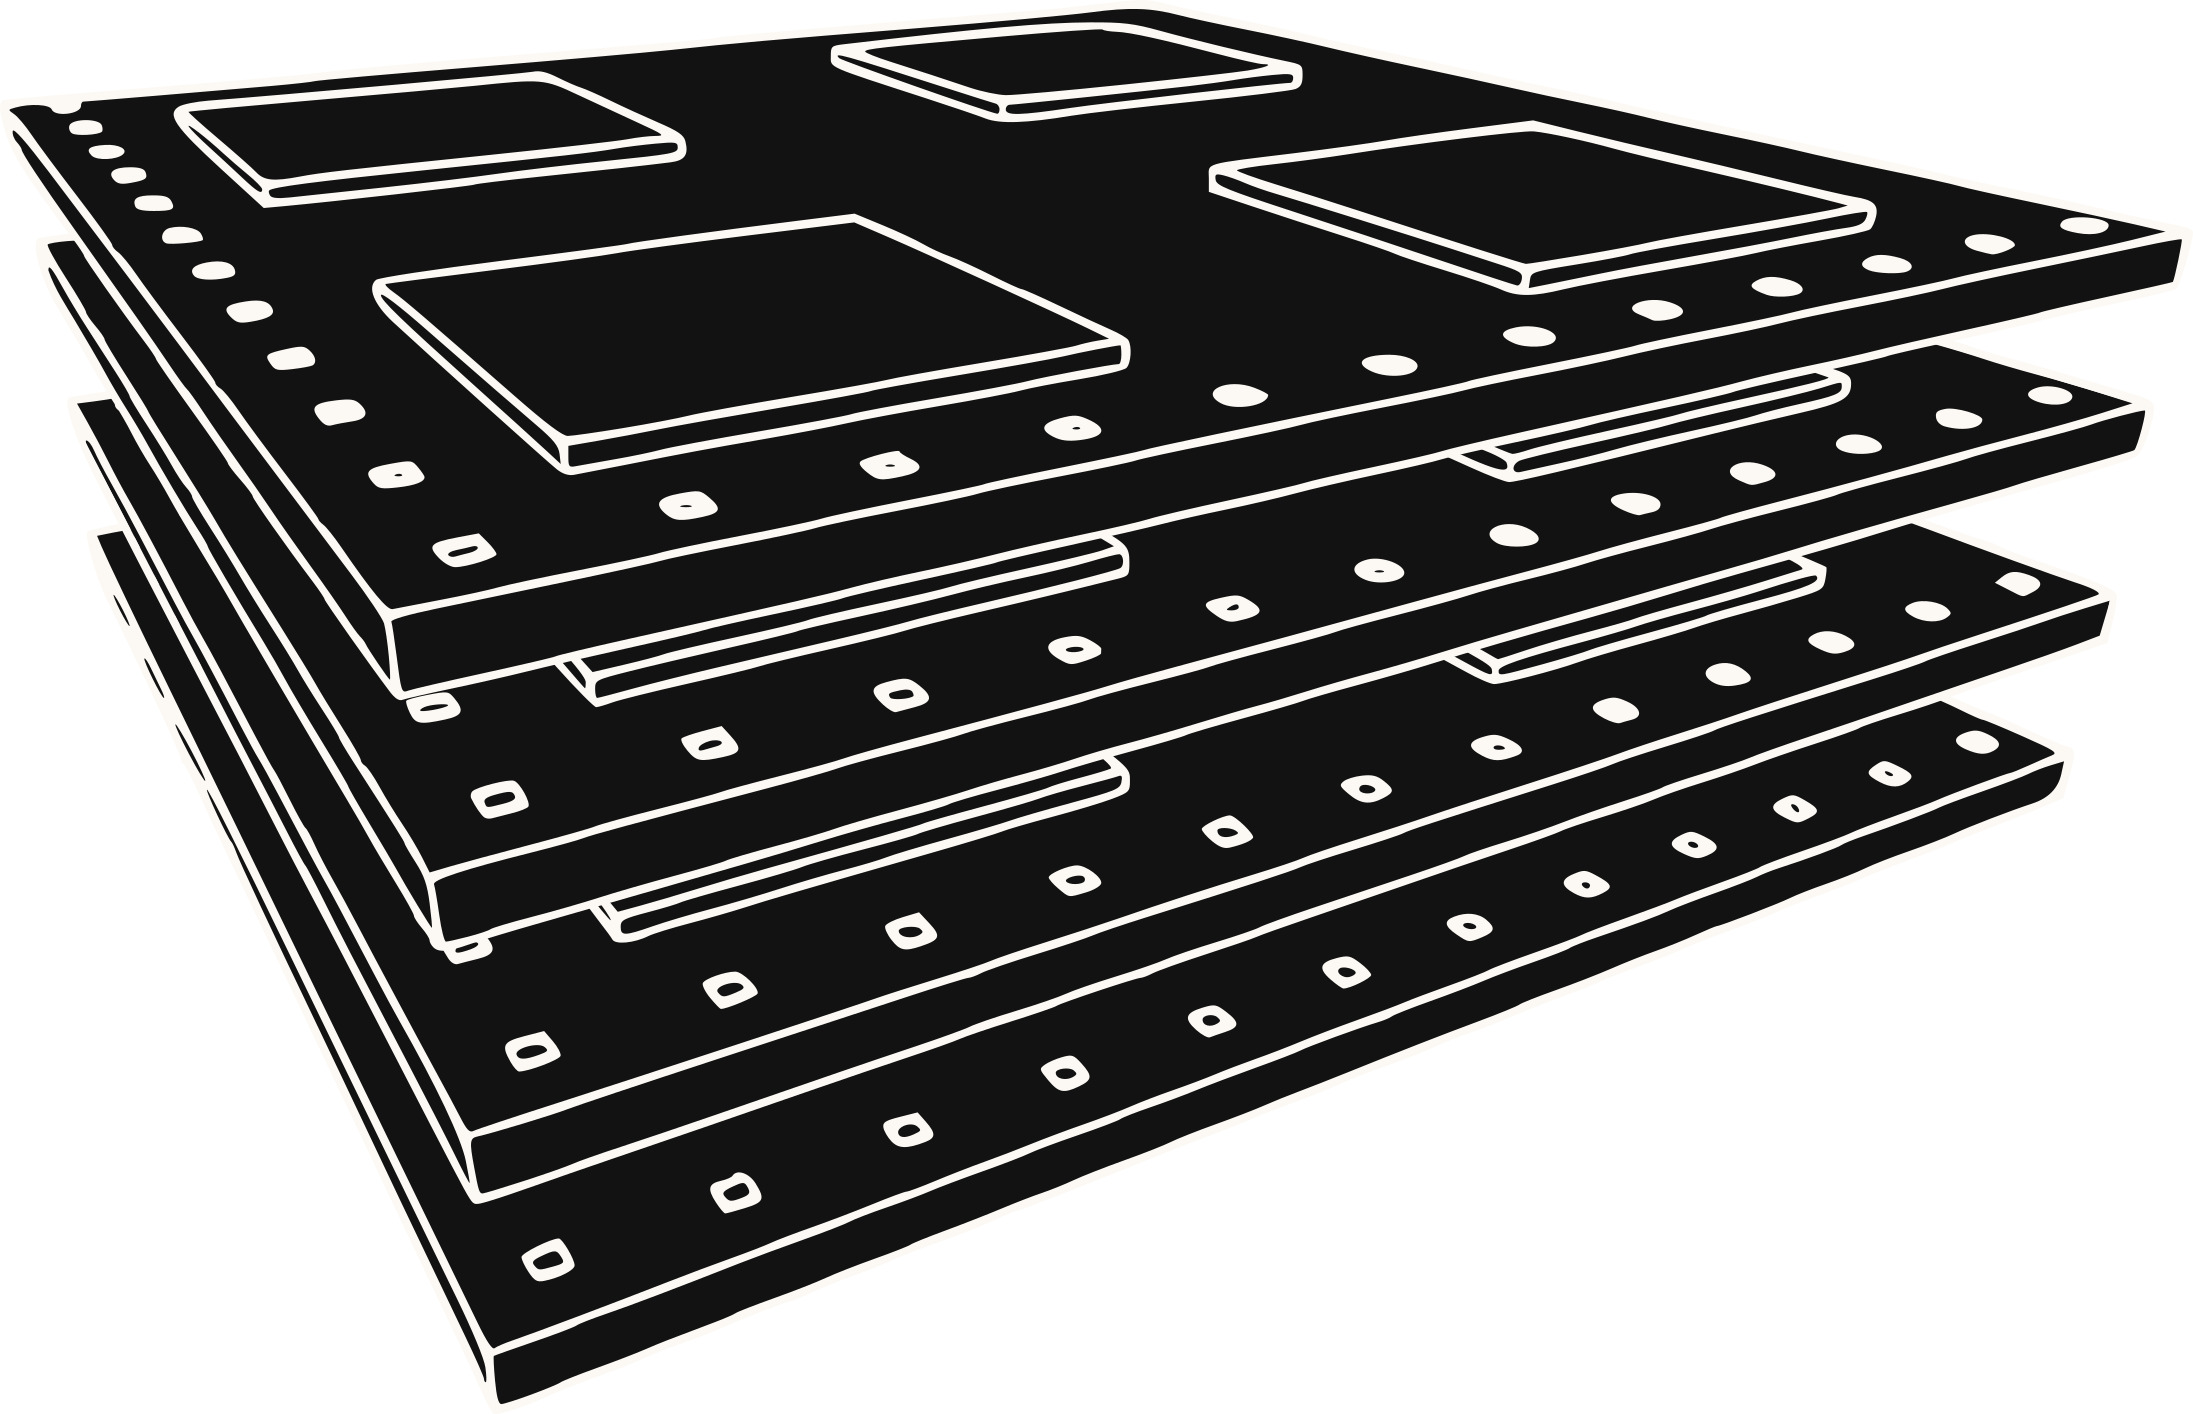
The electric field approach minimizes the movement of electrons at the chip level, reducing energy usage — and heat. Semron aims to leverage the heat-reducing properties of the electric field to place as as many as hundreds of layers of memscapacitors on a single chip — greatly increasing compute capacity.
A schematic showing Semron’s 3D AI chip design.
“We use this property as an enabler to deploy several hundred times the compute resources on a fixed silicon area,” Kirschen added. “Think of it like hundreds of chips in one package.”
In a 2021 study published in the journal Nature Electronics, researchers at Semron and the Max Planck Institute of Microstructure Physics successfully trained a computer vision model at energy efficiencies of over 3,500 TOPS/W — 35 to 300 times higher than existing techniques. TOPS/W is a bit of a vague metric, but the takeaway is that memcapacitors can lead to dramatic energy consumption reductions while training AI models.
Now, it’s early days for Semron, which Kirschen says is in the “pre-product” stage and has “negligible” revenue to show for it. Often the toughest part of ramping up a chip startup is mass manufacturing and attaining a meaningful customer base — albeit not necessarily in that order.
Making matters more difficult for Semron is the fact that it has stiff competition in custom chip ventures like Kneron, EnCharge and Tenstorrent, which have collectively raised tens of millions of dollars in venture capital. EnCharge, like Semron, is designing computer chips that use capacitors rather than transistors, but using a different substrate architecture.
Semron, however — which has an 11-person workforce that it’s planning to grow by around 25 people by the end of the year — has managed to attract funding from investors including Join Capital, SquareOne, OTB Ventures and Onsight Ventures. To date, the startup has raised 10 million euro (~$10.81 million).
Said SquareOne partner Georg Stockinger via email:
“Computing resources will become the ‘oil’ of the 21st century. With infrastructure-hungry large language models conquering the world and Moore’s law reaching the limits of physics, a massive bottleneck in computing resources will shape the years to come. Insufficient access to computing infrastructure will greatly slow down productivity and competitiveness both of companies and entire nation-states. Semron will be a key element in solving this problem by providing a revolutionary new chip that is inherently specialized on computing AI models. It breaks with the traditional transistor-based computing paradigm and reduces costs and energy consumption for a given computing task by at least 20x.”
Microsoft Research India (MSRI) has extended the application and nomination deadline for its Research Fellows (RF) Program to February 16, 2024, for the Fall 2024 term.
The program, situated at MSR India, provides participants with exposure to world-class research led by top computer science and technology researchers. Research Fellows engage in various aspects of the research lifecycle, from ideation and implementation to evaluation and deployment.
Eligible candidates for the RF Program should have completed their BS/BE/BTech or MS/ME/MTech in Computer Science or related areas, graduating by summer 2024.
Evaluation criteria encompass academic performance, raw intelligence, development skills, and demonstrated ability or aptitude for research and software development. Microsoft emphasizes an inclusive work environment, valuing diversity in its workforce.
Alumni of the MSR Research Fellows have achieved notable milestones, including admission to renowned PhD programs at MIT, Stanford, UC Berkeley, CMU, IISc, etc. Some have also founded successful companies like Everwell, Capillary, and Ola, while others contribute to Microsoft in development positions.
Applications for the Research Fellow program at Microsoft Research India will open on 11th December 2023. The deadline for university nominations and individual applications is set for 16th February 2024. In March 2024, the interview phase will commence. Following the interviews, between April and May 2024, offers will be extended to accepted candidates. The selected Research Fellows are expected to commence their roles at MSR India in July 2024.
The post Microsoft Research India Extends Deadline for Research Fellow Program Applications to Feb 16, 2024 appeared first on Analytics India Magazine.
In a recent blog, the AI expert Gary Marcus, who stood by Sam Altman at the US Senate hearing last year, expressed concerns about OpenAI, listing out a bunch of serious challenges that the ChatGPT maker might face this year.
“As a scientist and technologist, who has watched the company for a long time, I see a long list of challenges for the company this year,” said Marcus.
Legal Troubles?
Marcus acknowledges that OpenAI is the key player when we talk about the future of AI. However, that distinction comes with a lot of criticism and as he puts it, OpenAI would “remain under a microscope henceforth”.
When it comes to the NYT lawsuit, it is just the first of the millions that are going to come along, he writes. People have been calling the lawsuit as the one that finally moved OpenAI to respond to a lawsuit for the first time as it provided the proof of ChatGPT being trained on the publisher’s data – a classic case of copyright infringement.
Meanwhile, OpenAI has now been making deals with publishers such as AP, Axel Springer, American Journalism Project, and NYU, paying $1 million to $5 million to publications for licensing their articles.
It does look like the deal went kaput with NYT since the news publisher had approached Microsoft and OpenAI for a resolution in April, but nothing substantial came out in the end. On the other hand, NYT has also partnered with Google for the same reasons.
Now, Altman has said that OpenAI does not need to use NYT data to train models anymore. “Some people want to partner with us, some people don’t,” said Altman.
The only thing that might take a hit because of this is OpenAI ends up paying for the infringements, which might cut massively into the profits. The company has accepted that it would be almost impossible for AI to get trained adequately without copyright materials. That means it has to end up paying the amount to either accept the licence material or pay the fine.
But on the contrary, money might not be that big of a deal for OpenAI as it has been going through several rounds of funding. According to latest reports, it is looking to raise funds for a valuation of $100 billion. All of that is with Microsoft backing the company, which might end up OpenAI not caring so much about paying off the allegations, if proved correct.
Profit, moat, and technology
OpenAI has it all. Though not currently, the company is definitely on the road to being profitable soon. The company was operating at a loss for the longest time since it developed ChatGPT. Now, even though it is spending billions of dollars for training GPT-5, it said in December that it recently topped $1.6 billion annualised revenue because of ChatGPT.
When we said that OpenAI is as good as its next model, it definitely stands true. Currently, Google is about to release Gemini Ultra and Meta is on its way to release open source Llama 3, which admittedly on par with GPT-4, but OpenAI could just release GPT-5, which would overshadow the impact of both these models. Interestingly, the company can also decide to open source one of its older models such as GPT-4 to please the open source community.
When it comes to hallucinations, and a lot of experts claiming that generative AI might soon reach a plateau, that stands true for all the offerings on the globe. OpenAI would still be the leader when it comes to building these models, and being the innovative and forth-running company, would come up with different solutions, in completely different verticals.
Though as the generative AI landscape is diversifying and people are different providers to as backup plans, the same is the case with any other provider of any other technology. For example, Apple is still the most successful company regardless of hundreds of competitors rising in the market.
Though, the tensions will remain
At the WEF 2024 conference in Davos, Altman said that he still does not know for certain about what Ilya Sutskever is doing at OpenAI, hinting that there is still trouble among the board and the team in general. The tussle between being an altruistic non-profit organisation or going for-profit is out in the public, which definitely is going to be a concern for the company in the year.
All of this is when, as Marcus pointed out, the FTC has developed a strong interest in OpenAI with concerns about privacy and security, adding to the several leak reports. Moreover, the most recent “Inquiry into Generative AI Investments and Partnerships,” that was issued to Alphabet, Amazon, Anthropic, Microsoft, and OpenAI, is definitely going to push OpenAI to keep all of its investments and secrets in order.
But as uncle Marcus concluded, these tensions are not exclusive to OpenAI. Though it might remain in the focus, it might be better off than others. Though the valuations might drop, nothing substantial is going to affect the hottest AI startup.
He also forgot that OpenAI is not built by a bunch of 24-year old programmers, but as the recent openings suggest, the company is trying to woo in a bunch of young talent.
The post OpenAI Got 99 Problems, But Gary Ain’t One appeared first on Analytics India Magazine.
Just like Apple and Duolingo, Google has now chosen to sever ties with its third-party contractor, Appen, instead of taking the layoff route. This also signals a broader trend of companies tightening their belts on AI training data expenditures. The shift away from renewing contracts stems from a preference among AI model developers for special generative AI services over traditional manual methods.
Appen, once a linchpin in training some of the world’s premier AI systems for Adobe, Salesforce, and Nvidia, faced a downturn in its fortunes following a change in leadership. The departure of long-time CEO Mark Brayan, who steered the company for seven years, marked a turning point. The reins were handed over to Armughan Ahmad, a tech veteran with 25 years of experience, yet this transition precipitated a series of executive exits.
Despite boasting a global platform of over 1 million freelance workers in 170 countries, Appen has witnessed a 13% revenue decline in 2022. Citing “challenging external operating and macro conditions”, the company struggled to adapt to the burgeoning era of generative AI.
Former employees, choosing anonymity due to fears of reprisal, shared insights with CNBC, attributing Appen’s current challenges to years of lax quality controls and a disjointed organisational structure. As generative AI’s prominence grows in the tech industry, Appen and similar companies are finding themselves at the crossroads, navigating the consequences of their AI shortcomings.
Automation at Work
For the early days of AI models, manual data collection processes have led contractors like Appen to thrive, but the scene has dynamically changed with the rise of large language models (LLMs). These human-mimicking AI systems – namely Google’s Bard and OpenAI’s ChatGPT – can now scour data from the digital infrastructure to answer queries and even generate images in response.
In the recent turn of events, these language model companies have started spending less money on outsourcing work through firms like Appen. Instead, they are laser-focused on resetting their business through automated services provided by Labelbox and Scale AI, which specialise in generative AI.
Just a mere four months back, Google Cloud decided to lengthen its partnership with Labelbox, a platform that rolls out a suite of tools tailored for AI techniques like reinforcement learning with human feedback (RLHF), reinforcement learning from AI Feedback (RLAIF), evaluation, and red teaming.
Meanwhile, another player in the field, Scale AI, has been solidifying its standing with a clientele that reads like a who’s who of top-tier companies including Toyota, Instacart, PayPal, and Flexport. Scale AI has been making waves, providing bespoke data solutions to navigate the intricate waters of the machine learning lifecycle. The competition in this field is nothing short of a star-studded affair and is only going to get tougher form here.
Excuses Excuses
Google pivoting from Appen to Labelbox is a classic example of why companies should be quick and not hesitate to integrate generative AI and evolve with the landscape. The demand for automated services powered by AI is rising as it’s cheaper, faster and involves fewer problems.
Kim Stagg, Appen’s vice president of product, has publicly declared that the work required for generative AI services was different from what the company had previously needed. The company appears to be in no position to board the generative AI boat and has been left behind.
While the Appen executives have conveniently blamed AI, former employees have argued that the problem lies with the organisation’s structure and shuffling of executives. The pattern is seen in several companies that use generative AI as an excuse to hide their internal mishandled problems. Cory Stahle, an economist, has clarified that AI tools are not yet sophisticated enough to replace workers entirely. According to Stahle, if AI were really the culprit, layoffs would be far more widespread across diverse industries. “And we haven’t seen that happen yet,” he said.
The post The Real Reason Behind Google’s Recent ‘Layoffs’ appeared first on Analytics India Magazine.
OpenAI partners with Common Sense Media to collaborate on AI guidelines Kyle Wiggers 10 hours
OpenAI hopes to win the trust of parents — and policymakers — by partnering with organizations that work to minimize tech and media harms to kids, preteens and teens.
Case in point, OpenAI today announced a partnership with Common Sense Media, the nonprofit organization that reviews and ranks the suitability of various media and tech for kids, to collaborate on AI guidelines and education materials for parents, educators and young adults.
As a part of the partnership, OpenAI will work with Common Sense Media to curate “family-friendly” GPTs — chatbot apps powered by OpenAI’s GenAI models — in the GPT Store, OpenAI’s GPT marketplace, based on Common Sense’s rating and evaluation standards, OpenAI CEO Sam Altman says.
“AI offers incredible benefits for families and teens, and our partnership with Common Sense will further strengthen our safety work, ensuring that families and teens can use our tools with confidence,” Altman added in a canned statement.
The launch of the partnership comes after OpenAI said that it would participate in Common Sense’s new framework, launched in September, for ratings and reviews designed to assess the safety, transparency, ethical use and impact of AI products. Common Sense’s framework aims to produce a “nutrition label” for AI-powered apps, according to Common Sense co-founder and CEO James Steyer, toward shedding light on the contexts in which the apps are used and highlight areas of potential opportunity and harm against a set of “common sense” tenets.
The OpenAI logo displayed on a smartphone screen in front of computer screen with the ChatGPT logo.
In a press release, Steyer alluded to the fact that today’s parents remain generally less knowledgeable about GenAI tools — for example, OpenAI’s viral AI-powered chatbot ChatGPT — than younger generations. An Impact Research poll commissioned by Common Sense Media late last year found that 58% of students aged 12 to 18 have used ChatGPT compared to 30% of parents of school-aged children.
“Together, Common Sense and OpenAI will work to make sure that AI has a positive impact on all teens and families,” Steyer said in an emailed statement. “Our guides and curation will be designed to educate families and educators about safe, responsible use of [OpenAI tools like] ChatGPT, so that we can collectively avoid any unintended consequences of this emerging technology.”
OpenAI’s under pressure from regulators to show that its GenAI-powered apps, including ChatGPT, are an overall boon for society — not a detriment to it. Just last summer, the U.S. Federal Trade Commission opened an investigation into OpenAI over whether ChatGPT harmed consumers through its collection of data and publication of false statements on individuals. European data authorities have also expressed concern over OpenAI’s private information handling.
OpenAI’s tools, like all GenAI tools, tend to confidently make things up and get basic facts wrong. And they’re biased — a reflection of the data that was used to train them.
Kids and teens, aware of the tools’ limitations or no, are increasingly turning to them for help with not only with schoolwork but personal issues. According to a poll from the Center for Democracy and Technology, 29% of kids report having used ChatGPT to deal with anxiety or mental health issues, 22% for issues with friends and 16% for family conflicts.
Large language models (LLMs) like GPT-4, Claude, and LLaMA have exploded in popularity. Thanks to their ability to generate impressively human-like text, these AI systems are now being used for everything from content creation to customer service chatbots.
But how do we know if these models are actually any good? With new LLMs being announced constantly, all claiming to be bigger and better, how do we evaluate and compare their performance?
In this comprehensive guide, we'll explore the top techniques for evaluating large language models. We'll look at the pros and cons of each approach, when they are best applied, and how you can leverage them in your own LLM testing.
Task-Specific Metrics
One of the most straightforward ways to evaluate an LLM is to test it on established NLP tasks using standardized metrics. For example:
Summarization
For summarization tasks, metrics like ROUGE (Recall-Oriented Understudy for Gisting Evaluation) are commonly used. ROUGE compares the model-generated summary to a human-written “reference” summary, counting the overlap of words or phrases.
There are several flavors of ROUGE, each with their own pros and cons:
ROUGE-N: Compares overlap of n-grams (sequences of N words). ROUGE-1 uses unigrams (single words), ROUGE-2 uses bigrams, etc. The advantage is it captures word order, but it can be too strict.
ROUGE-L: Based on longest common subsequence (LCS). More flexible on word order but focuses on main points.
ROUGE-W: Weights LCS matches by their significance. Attempts to improve on ROUGE-L.
In general, ROUGE metrics are fast, automatic, and work well for ranking system summaries. However, they don't measure coherence or meaning. A summary could get a high ROUGE score and still be nonsensical.
Where LCS is the length of the longest common subsequence.
ROUGE-W weights the LCS matches. It considers the significance of each match in the LCS.
Translation
For machine translation tasks, BLEU (Bilingual Evaluation Understudy) is a popular metric. BLEU measures the similarity between the model's output translation and professional human translations, using n-gram precision and a brevity penalty.
Key aspects of how BLEU works:
Compares overlaps of n-grams for n up to 4 (unigrams, bigrams, trigrams, 4-grams).
Calculates a geometric mean of the n-gram precisions.
Applies a brevity penalty if translation is much shorter than reference.
Generally ranges from 0 to 1, with 1 being perfect match to reference.
BLEU correlates reasonably well with human judgments of translation quality. But it still has limitations:
Only measures precision against references, not recall or F1.
Struggles with creative translations using different wording.
Susceptible to “gaming” with translation tricks.
Other translation metrics like METEOR and TER attempt to improve on BLEU's weaknesses. But in general, automatic metrics don't fully capture translation quality.
Other Tasks
In addition to summarization and translation, metrics like F1, accuracy, MSE, and more can be used to evaluate LLM performance on tasks like:
Text classification
Information extraction
Question answering
Sentiment analysis
Grammatical error detection
The advantage of task-specific metrics is that evaluation can be fully automated using standardized datasets like SQuAD for QA and GLUE benchmark for a range of tasks. Results can easily be tracked over time as models improve.
However, these metrics are narrowly focused and can't measure overall language quality. LLMs that perform well on metrics for a single task may fail at generating coherent, logical, helpful text in general.
Research Benchmarks
A popular way to evaluate LLMs is to test them against wide-ranging research benchmarks covering diverse topics and skills. These benchmarks allow models to be rapidly tested at scale.
Some well-known benchmarks include:
SuperGLUE – Challenging set of 11 diverse language tasks.
GLUE – Collection of 9 sentence understanding tasks. Simpler than SuperGLUE.
MMLU – 57 different STEM, social sciences, and humanities tasks. Tests knowledge and reasoning ability.
Winograd Schema Challenge – Pronoun resolution problems requiring common sense reasoning.
ARC – Challenging natural language reasoning tasks.
Hellaswag – Common sense reasoning about situations.
PIQA – Physics questions requiring diagrams.
By evaluating on benchmarks like these, researchers can quickly test models on their ability to perform math, logic, reasoning, coding, common sense, and much more. The percentage of questions correctly answered becomes a benchmark metric for comparing models.
However, a major issue with benchmarks is training data contamination. Many benchmarks contain examples that were already seen by models during pre-training. This enables models to “memorize” answers to specific questions and perform better than their true capabilities.
Attempts are made to “decontaminate” benchmarks by removing overlapping examples. But this is challenging to do comprehensively, especially when models may have seen paraphrased or translated versions of questions.
So while benchmarks can test a broad set of skills efficiently, they cannot reliably measure true reasoning abilities or avoid score inflation due to contamination. Complementary evaluation methods are needed.
LLM Self-Evaluation
An intriguing approach is to have an LLM evaluate another LLM's outputs. The idea is to leverage the “easier” task concept:
Producing a high-quality output may be difficult for an LLM.
But determining if a given output is high-quality can be an easier task.
For example, while an LLM may struggle to generate a factual, coherent paragraph from scratch, it can more easily judge if a given paragraph makes logical sense and fits the context.
So the process is:
Pass input prompt to first LLM to generate output.
Pass input prompt + generated output to second “evaluator” LLM.
Ask evaluator LLM a question to assess output quality. e.g. “Does the above response make logical sense?”
This approach is fast to implement and automates LLM evaluation. But there are some challenges:
Performance depends heavily on choice of evaluator LLM and prompt wording.
Constrainted by difficulty of original task. Evaluating complex reasoning is still hard for LLMs.
Can be computationally expensive if using API-based LLMs.
Self-evaluation is especially promising for assessing retrieved information in RAG (retrieval-augmented generation) systems. Additional LLM queries can validate if retrieved context is used appropriately.
Overall, self-evaluation shows potential but requires care in implementation. It complements, rather than replaces, human evaluation.
Human Evaluation
Given the limitations of automated metrics and benchmarks, human evaluation is still the gold standard for rigorously assessing LLM quality.
Experts can provide detailed qualitative assessments on:
Accuracy and factual correctness
Logic, reasoning, and common sense
Coherence, consistency and readability
Appropriateness of tone, style and voice
Grammaticality and fluency
Creativity and nuance
To evaluate a model, humans are given a set of input prompts and the LLM-generated responses. They assess the quality of responses, often using rating scales and rubrics.
The downside is that manual human evaluation is expensive, slow, and difficult to scale. It also requires developing standardized criteria and training raters to apply them consistently.
Some researchers have explored creative ways to crowdfund human LLM evaluations using tournament-style systems where people bet on and judge matchups between models. But coverage is still limited compared to full manual evaluations.
For business use cases where quality matters more than raw scale, expert human testing remains the gold standard despite its costs. This is especially true for riskier applications of LLMs.
Conclusion
Evaluating large language models thoroughly requires using a diverse toolkit of complementary methods, rather than relying on any single technique.
By combining automated approaches for speed with rigorous human oversight for accuracy, we can develop trustworthy testing methodologies for large language models. With robust evaluation, we can unlock the tremendous potential of LLMs while managing their risks responsibly.
The world of artificial intelligence (AI) mostly exists in cloud-computing facilities and rarely touches your smartphone. When you use a tool like ChatGPT to answer a prompt, the hard work of training the program, so that it functions properly, has been done days, weeks, and months before, behind the scenes, in the enormous AI data centers built by Microsoft and others.
However, 2024 could be the year the divide is crossed — and it could be when AI starts to learn in your pocket. Efforts are underway to make it possible to train a neural net — even a large language model (LLM) — on your personal device, with little or no connection to the cloud.
Also: 7 ways to make sure your data is ready for generative AI
The most obvious benefits of on-device training include: avoiding the delay incurred by having to connect to the cloud; learning from local information on a constant and personalized manner; and preserving privacy that would be violated by sending personal data to a cloud data center.
The impact of on-device training could be a transformation in the capabilities of neural networks. AI could be personalized to your own actions as you walk around, tapping, scrolling, and dragging. AI could learn from the environments you pass through during your daily routine, gathering signs about the world.
Recent work by Apple engineers suggests the company is looking to bring larger neural networks, the "generative" kind represented by OpenAI's ChatGPT, to run locally on the iPhone.
More broadly, Google introduced a radically scaled-down AI approach called TinyML several years ago. TinyML can run neural nets in devices with as little as a milliwatt of power, such as smart sensors placed on machinery.
The greater challenge for technology companies is to make those kinds of neural networks not just perform predictions on a phone, but also learn new things on a phone — to carry out training locally.
That effort takes far more processing power, far more memory, and far more bandwidth for any computer to train a neural net than to use the finished neural net to make predictions.
Efforts have been underway to conquer that computing mountain by doing things such as selectively updating only portions of the neural net's "weights" or "parameters." A signature effort there is MIT's TinyTL, which uses what's called transfer learning as a way to refine a neural net that is already mostly trained.
TinyTL has so far been used for small things, such as facial recognition. But the state of the art is now moving to tackling the LLMs of generative AI, including OpenAI's GPT-4. The LLMs have hundreds of billions of neural weights that need to be kept in memory, and then passed to the processor to be updated as new information comes in. This training challenge takes place on a scale never before attempted.
A research report this month by staff at European chip-making giant STMicroelectronics makes the case that it's not enough in these training efforts to perform inference on mobile devices — instead, the client device must also train the neural network to keep it fresh.
"Enabling only model's inference on the device is not enough," write Danilo Pietro Pau and Fabrizio Maria Aymone. "The performance of the AI models, in fact, deteriorates as time passes since the last training cycle; phenomenon known as concept drift," for which the solution is to update the program with new training data.
The authors suggest slimming down a neural net, so it's easier to train a model on a memory-constrained device. Specifically, they experiment with removing what's called "back-propogation", the mathematical method in LLMs that is the most compute-intensive part of training.
Pau and Aymone found that replacing back-propogation with simpler math could reduce the amount of on-device memory needed for the neural weights by as much as 94%.
Some scientists advocate for splitting up the training task among many client devices, which is called "federated learning".
Federated learning in action.
Researchers Chu Myaet Thwal and team at Kyung Hee University this month adapted a form of LLM used for image recognition across as many as 50 workstation computers, each running a single Nvidia GPU gaming card. Their code took less memory on the device to train than the standard version of the neural net without losing accuracy.
Some experts, meanwhile, argue network communications will have to be adjusted, so mobile devices can communicate better when performing federated learning.
Scholars at the Institute for Electrical and Electronic Engineering this month hypothesized a communications network using the forthcoming 6G standard, where the bulk of LLM training is completed first in a data center. Then, the cloud coordinates a bunch of client devices that "fine-tune" the LLM with local data.
Such "federated fine-tuning", where each device learns some portion of an LLM, without starting from scratch, can be done with a lot less processing power on the battery-powered device than in full training.
Many approaches aim to reduce the memory and processing required for each neural weight. The ultimate approach is what's called "binary neural networks", where instead of each weight having a numeric value, the weights have only a one or a zero, which vastly reduces the amount of on-device storage required.
A lot of the technical concerns mentioned above sound abstract, but consider some of the use cases of training a neural net locally.
A team at Nanyang Technological University in Singapore this month used on-device learning to counter cyber threats by having each individual device train its own local version of an AI-based "intrusion-detection system" or IDS, which is a common cybersecurity program.
Instead of the client devices having to interact with a central server, the team was able to download an initial draft of the IDS code and then fine-tune it for local security conditions. Not only is such training more specific to a local security threat, it also prevents the passing of sensitive security information back and forth over the network, where it could be intercepted by malicious parties.
Apple is rumored to be eyeing greater on-board AI functionality for iOS devices and has offered clues to what could be completed in a mobile context.
In a paper in August, Apple scientists described a way to automatically learn the qualities of mobile apps, called the Never-ending UI Learner. The program runs on a smartphone and automatically presses buttons and undertakes other interactions to determine which kinds of controls a user interface requires.
The aim is to use each device to automatically learn, rather than relying on a bunch of human workers who spend their time pressing buttons and annotating app functions.
The experiment was undertaken in a controlled setting by Apple staff. If the trial was attempted in the wild using real customers' iPhones, then "a privacy-preserving approach would be needed (e.g., on-device training)," the authors write.
Another mobile-based concept was described by Apple scientists in 2022 in a paper titled "Training Large-Vocabulary Neural Language Models by Private Federated Learning for Resource-Constrained Devices".
Their goal was to train speech-recognition AI on mobile devices using the federated learning approach.
Each person's device uses samples of interactions with a "voice assistant" (probably Siri) to train the neural net. Then, the neural network parameters developed by each phone are sent to the network, where they're aggregated to make one improved neural net.
The big takeaway from all these research efforts is that scientists are hard at work trying to find ways of compressing and dividing the work of training to make it feasible on battery-operated devices with less memory and less processing power than workstations and servers.
Whether this research effort breaks through in 2024 remains to be seen. However, what's already clear is that the training of neural networks is going to move out of the cloud and, quite possibly, into the palm of your hand.